AI Image Generator

GPT Image 2.5

Two speeds on one page, and the words you typed come back spelled right.

Vidney Workbench

21 models
0/2000
Required: 3 credits

Output

Sample

GPT Image 2.5: Flare vs Sunburst

GPT Image 2.5 comes in two versions, and this page runs both at the same price. What separates them is speed against precision.

OpenAI ships GPT Image 2.5 as two variants behind one interface. What it puts forward for this generation, words in quotation marks rendered as typed and edits that change only what you name, belongs to both of them, and a crowded prompt can still need a second pass on either. Flare is the one OpenAI names as the default for most applications, and it renders in about half the time GPT Image 2 needed. Sunburst puts precision first: it holds complex detail more faithfully and takes longer to finish. On Vidney both take the same prompts, up to four reference images, the same five aspect ratios and the same 1K, 2K and 4K sizes, and they cost the same credits at every size. The choice never touches your balance, only the clock and the result.

The quick one

Flare

Flare is where most work should start. What it adds is speed: it comes back fast enough to iterate on a layout rather than wait on it, and in our own runs a 4K frame finished in 47 seconds. The lettering and the contained edits this generation is known for are all here, just at the quicker pace.

Reach for it when

  • First drafts and exploring directions
  • Batches of variations on one brief
  • Screens and posters you will revise several times

The precise one

Sunburst

Sunburst is the more precise editor of the two, for the frame where nothing may drift. Name one element and the rest of the frame is meant to stay put, and at 4K fine detail such as small print holds up when you zoom in. That care costs time: the 4K frame Flare finished in 47 seconds took Sunburst 64 seconds.

Reach for it when

  • Edits where only the named part may change
  • A product line that must match one approved shot
  • 4K work that will be viewed large or printed

Start on Flare, and switch to Sunburst the moment an edit has to hold or the detail has to survive a close look. Both sit in the model menu of the generator above, listed as GPT Image 2.5 Flare and GPT Image 2.5 Sunburst, at the same credits.

What GPT Image 2.5 does well

01

Five faces, none alike

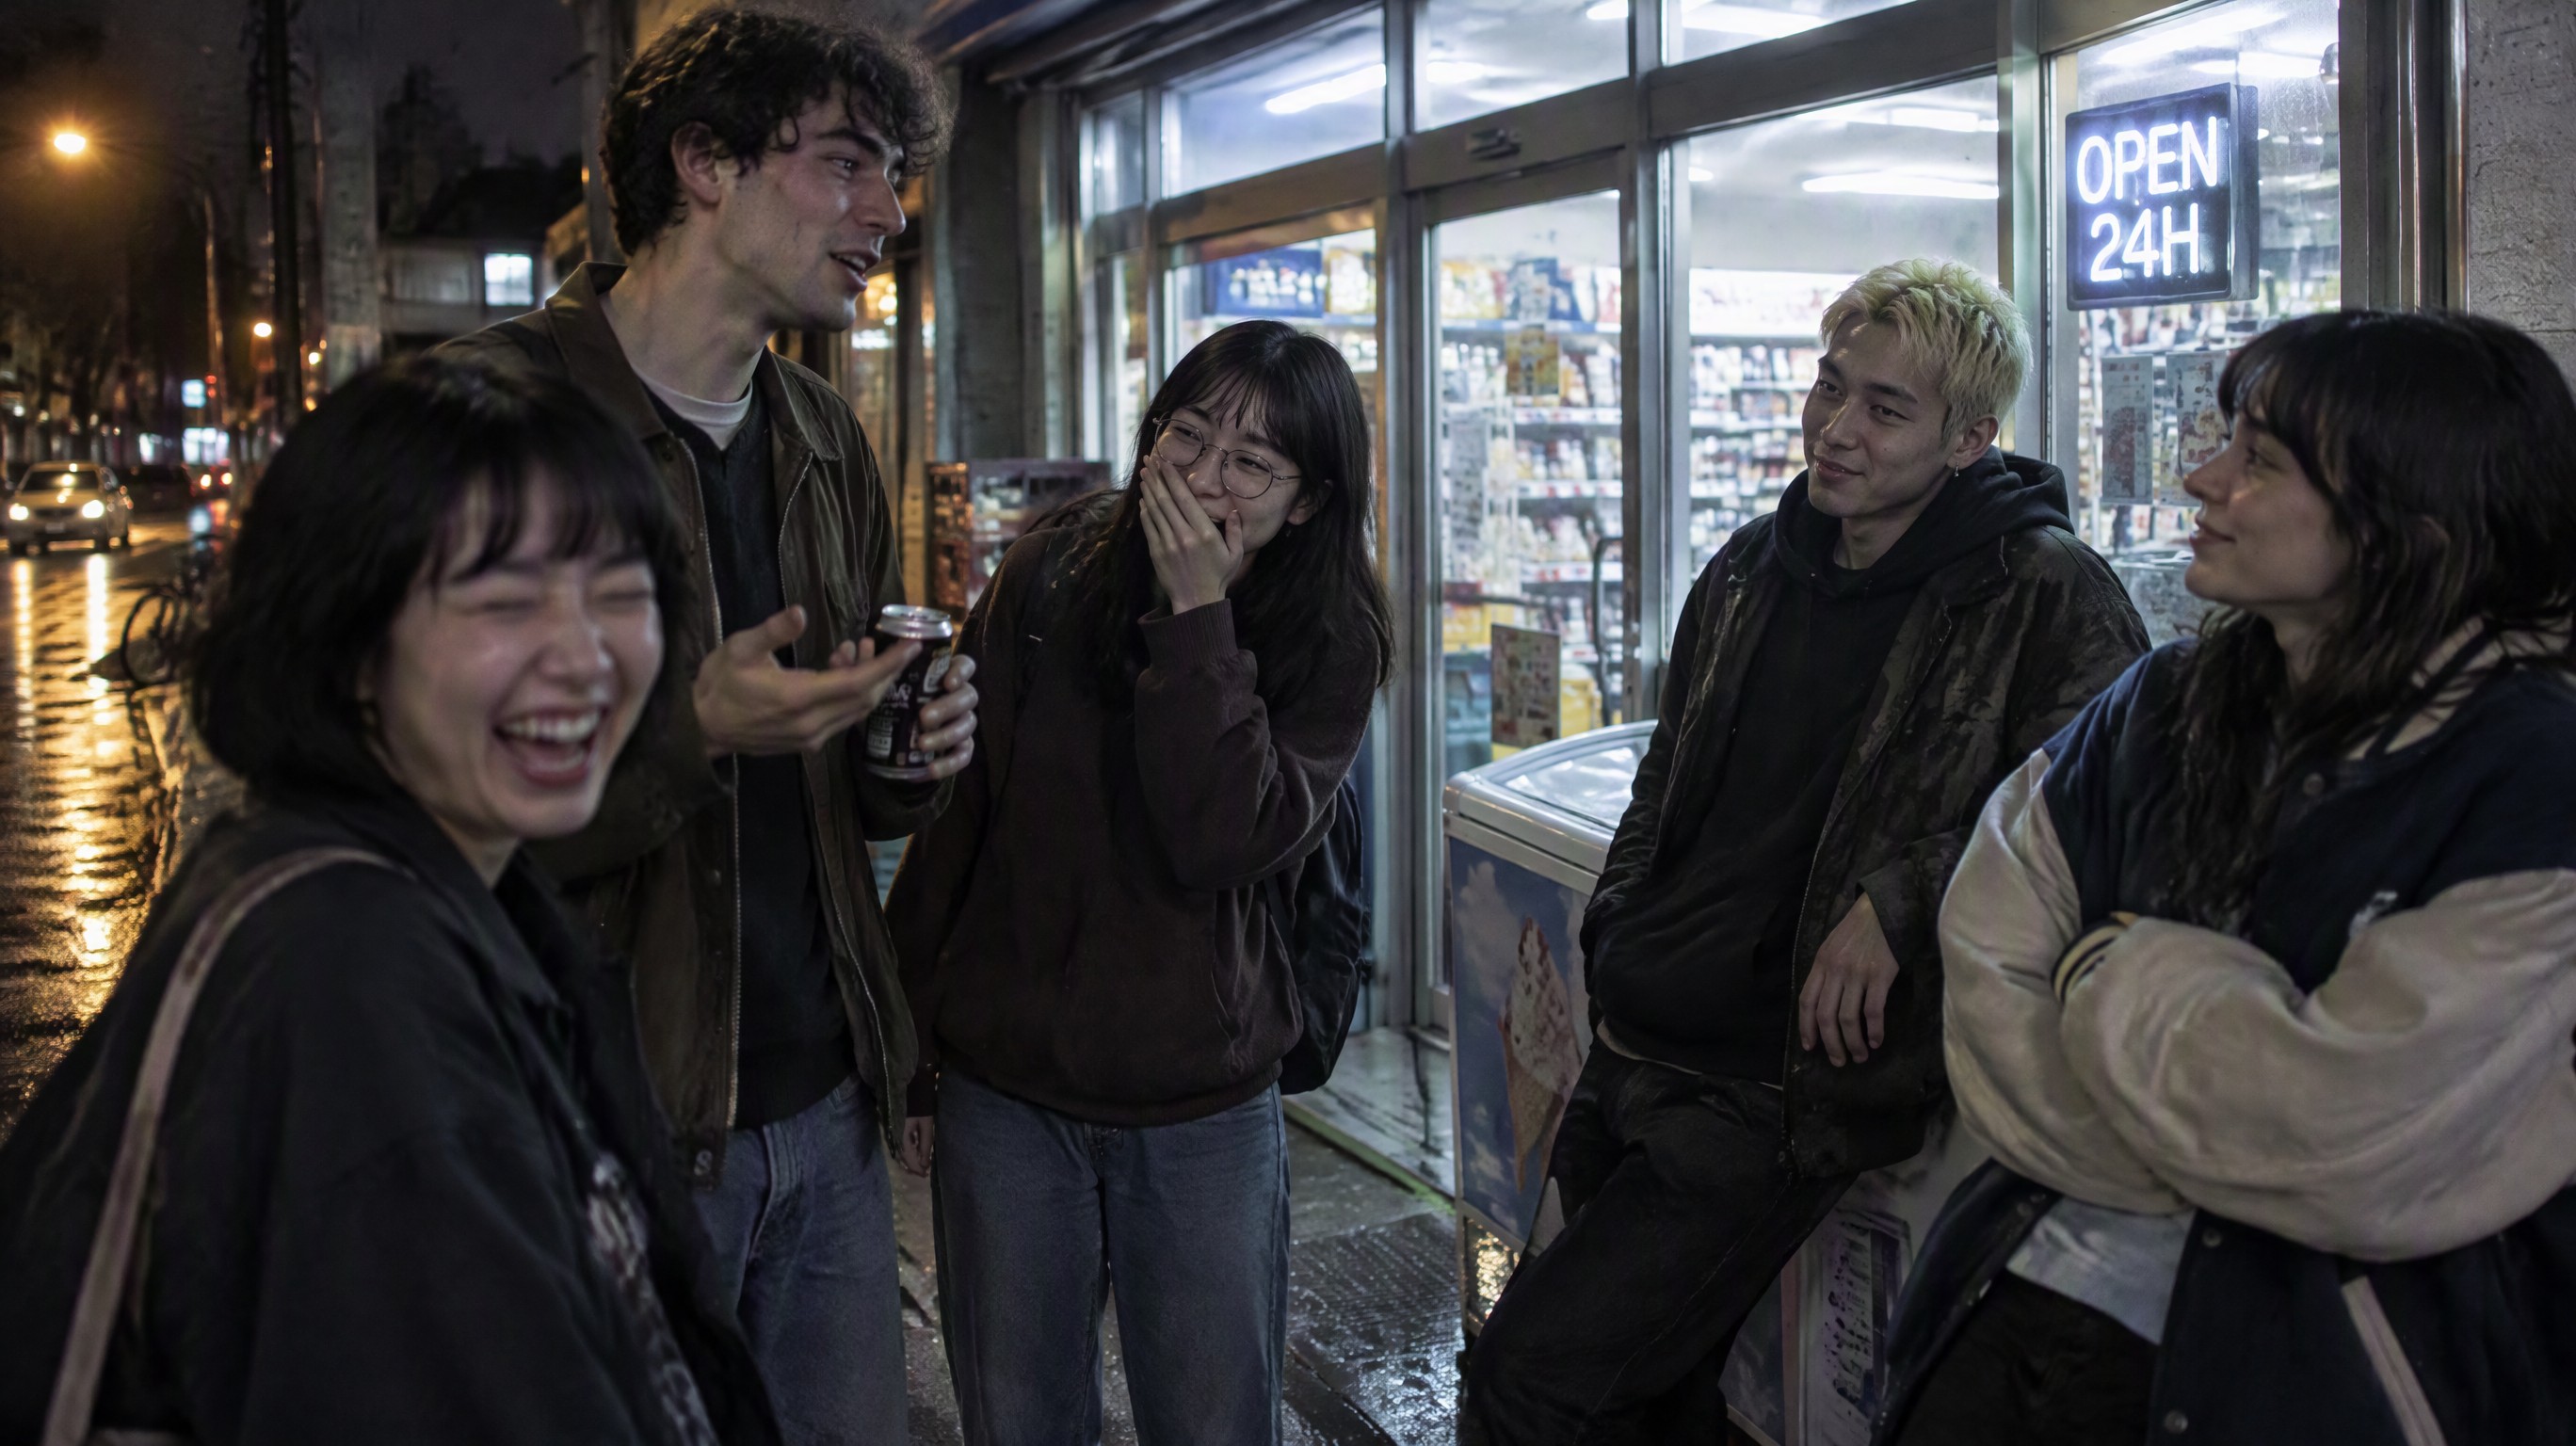
Five friends outside a convenience store after midnight, lit by nothing but the shop window and one streetlamp. Each face is its own person, a different laugh, a different set of eyes, real skin under harsh fluorescent light, and nobody posing for the camera.

Five faces, none alike: Photorealistic candid photograph of five friends in their early twenties hanging out on the sidewalk in front of a small 24-hour convenience store late at night, laughing and talking in the middle of a story. Each face is clearly different and clearly lit: a young woman with a short black bob laughing with her eyes squeezed shut, a tall young man mid-sentence gesturing with a canned coffee, a young woman in round glasses covering her grin with one hand, a young man with bleached hair leaning against the ice-cream freezer by the door with a lopsided smirk, and a young woman in an oversized varsity jacket looking sideways at her friend with a fond half-smile. Natural mixed lighting only: cool white fluorescent light spilling from the store windows onto the pavement, one warm streetlamp far to the left, soft reflections on slightly damp asphalt. Shot on a 35mm lens at f/2 from a few steps away, the friend nearest the camera slightly out of focus, real skin texture with pores and a little shine, no beauty retouching, nobody posing for the camera. The storefront is generic and unbranded; the only readable text is a small glowing sign reading 'OPEN 24H'. Documentary photography, muted colours, faint film grain.
Prompt

Photorealistic candid photograph of five friends in their early twenties hanging out on the sidewalk in front of a small 24-hour convenience store late at night, laughing and talking in the middle of a story. Each face is clearly different and clearly lit: a young woman with a short black bob laughing with her eyes squeezed shut, a tall young man mid-sentence gesturing with a canned coffee, a young woman in round glasses covering her grin with one hand, a young man with bleached hair leaning against the ice-cream freezer by the door with a lopsided smirk, and a young woman in an oversized varsity jacket looking sideways at her friend with a fond half-smile. Natural mixed lighting only: cool white fluorescent light spilling from the store windows onto the pavement, one warm streetlamp far to the left, soft reflections on slightly damp asphalt. Shot on a 35mm lens at f/2 from a few steps away, the friend nearest the camera slightly out of focus, real skin texture with pores and a little shine, no beauty retouching, nobody posing for the camera. The storefront is generic and unbranded; the only readable text is a small glowing sign reading 'OPEN 24H'. Documentary photography, muted colours, faint film grain.

02

A photo and its construction drawing, side by side

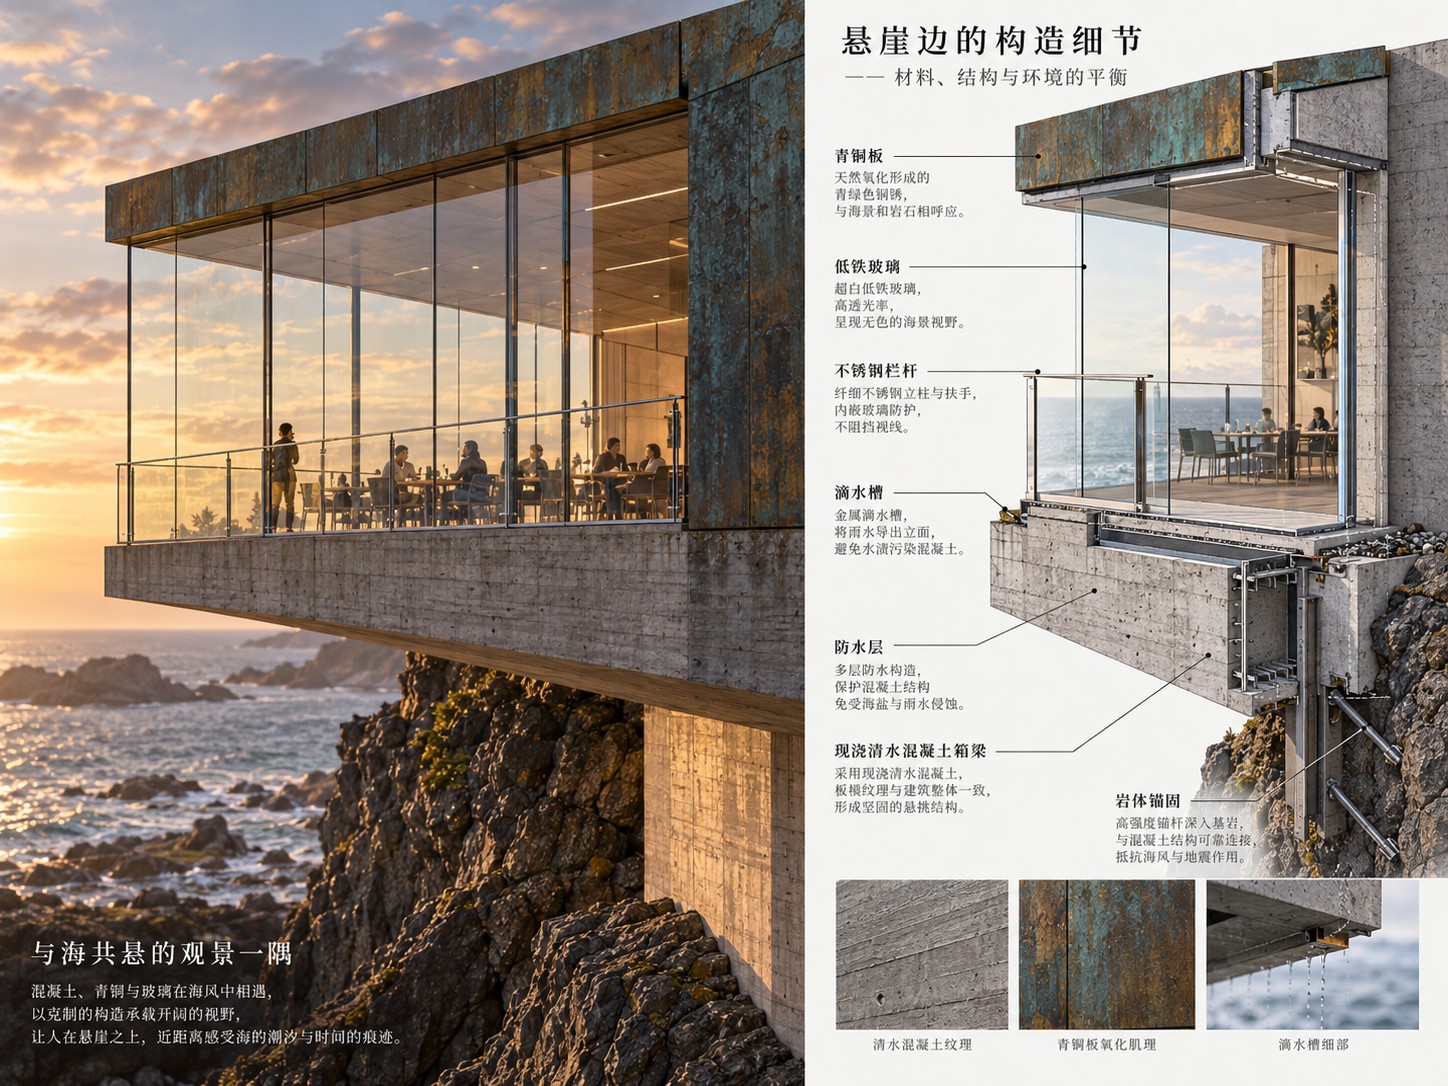
A glass restaurant cantilevered over the sea on the left, its cut-away detail on the right, with seven Chinese callouts running from the patinated bronze cladding down to the rock anchors. Every character in the annotations stays legible, and the drawing matches the photograph part for part.

A photo and its construction drawing, side by side: A two-part editorial spread on one 4:3 canvas. Left half: a photorealistic architectural photograph at golden hour of a small glass-walled restaurant cantilevered from a dark basalt cliff over the sea, the box clad in green-patinated bronze panels and carried on a raw board-marked concrete beam, floor to ceiling low-iron glazing with a thin stainless steel guardrail, diners at tables inside lit by the low sun, waves breaking on the rocks below, soft clouds. Right half on warm off-white paper: an annotated construction detail of the same cantilever drawn as a clean cut-away render with hairline leader lines, titled '悬崖边的构造细节' with the subtitle '材料、结构与环境的平衡', and seven callouts in Chinese reading '青铜板', '低铁玻璃', '不锈钢栏杆', '滴水槽', '防水层', '现浇清水混凝土箱梁', '岩体锚固', each with two or three short lines of explanation in small grey type; along the bottom three small material swatches captioned '清水混凝土纹理', '青铜板氧化肌理', '滴水槽细部'. Bottom left of the photograph a white caption block reading '与海共悬的观景一隅' with three short lines of copy beneath. Editorial typography, generous margins, every character rendered clearly, no other text.
Prompt

A two-part editorial spread on one 4:3 canvas. Left half: a photorealistic architectural photograph at golden hour of a small glass-walled restaurant cantilevered from a dark basalt cliff over the sea, the box clad in green-patinated bronze panels and carried on a raw board-marked concrete beam, floor to ceiling low-iron glazing with a thin stainless steel guardrail, diners at tables inside lit by the low sun, waves breaking on the rocks below, soft clouds. Right half on warm off-white paper: an annotated construction detail of the same cantilever drawn as a clean cut-away render with hairline leader lines, titled '悬崖边的构造细节' with the subtitle '材料、结构与环境的平衡', and seven callouts in Chinese reading '青铜板', '低铁玻璃', '不锈钢栏杆', '滴水槽', '防水层', '现浇清水混凝土箱梁', '岩体锚固', each with two or three short lines of explanation in small grey type; along the bottom three small material swatches captioned '清水混凝土纹理', '青铜板氧化肌理', '滴水槽细部'. Bottom left of the photograph a white caption block reading '与海共悬的观景一隅' with three short lines of copy beneath. Editorial typography, generous margins, every character rendered clearly, no other text.

03

A blossom the size of a sail

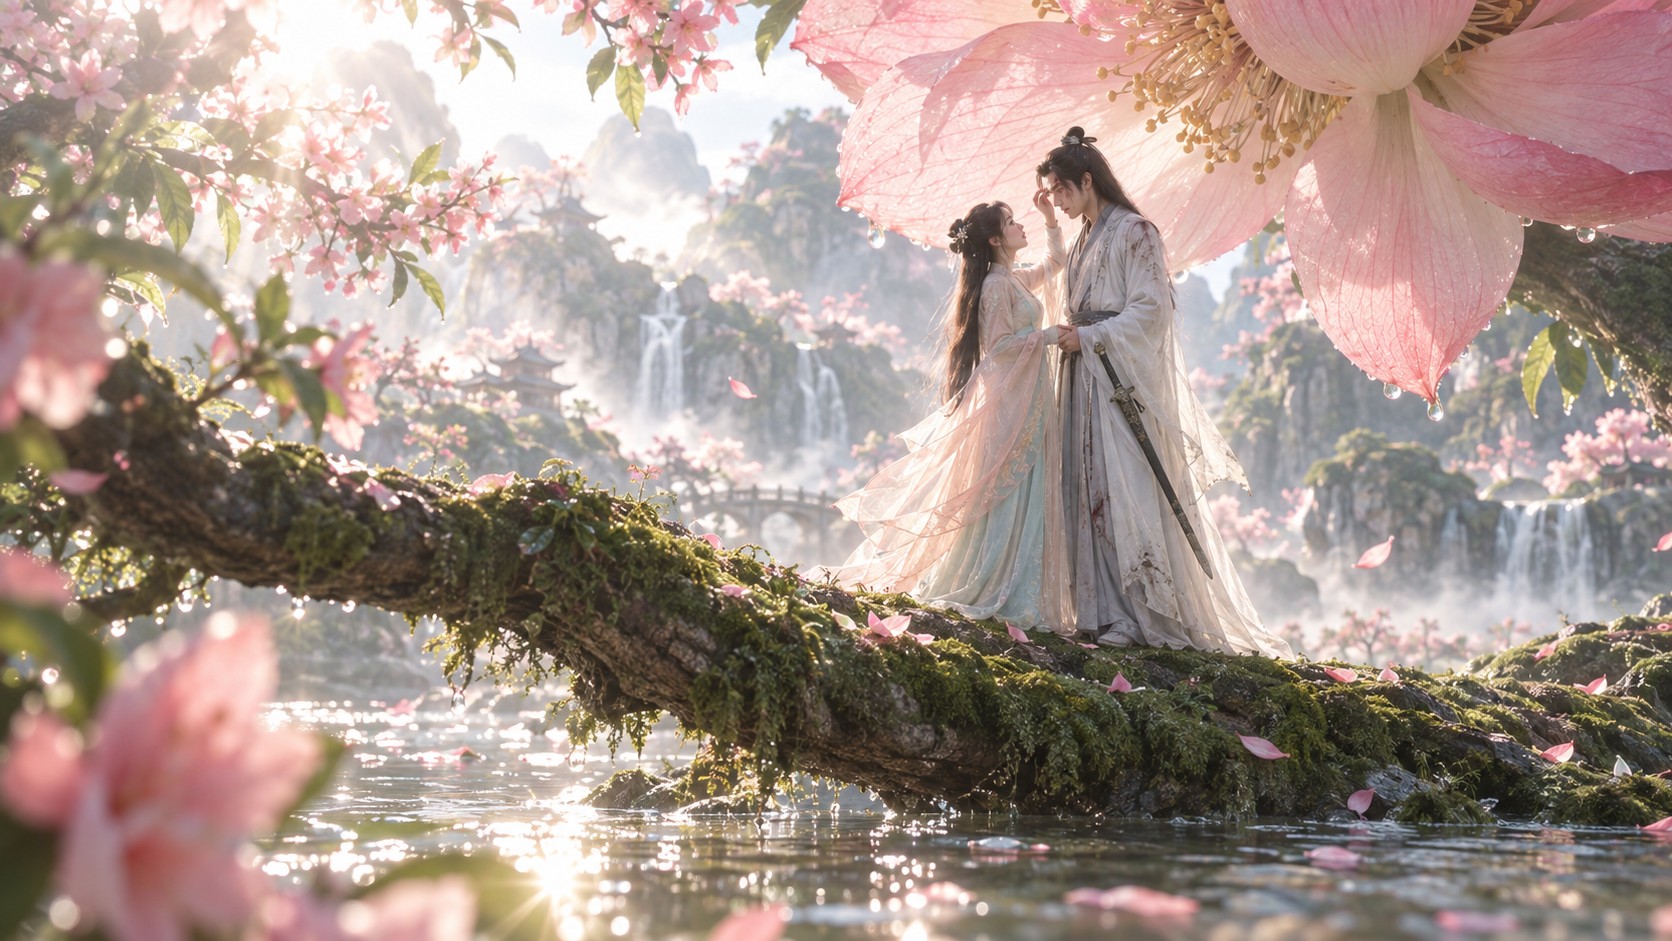
Two figures in hanfu on a mossy trunk above a river, under a translucent pink petal with dew along its edge, karst peaks and waterfalls dissolving into haze behind them. Backlight, mist and wet moss read as one light, with the fabric folds sharp where the focus falls.

A blossom the size of a sail: Cinematic wide shot in a Chinese xianxia fantasy world, photoreal CG. A young woman in flowing pale pink and mint layered hanfu with long black hair and a jade hairpin stands on a moss-covered fallen tree trunk that bridges a shallow river, gently touching the cheek of a young swordsman in white and grey robes with a sword at his hip; both in profile, close together. Above them a giant translucent pink blossom leans over the trunk, its petals the size of sails with dewdrops on the edges and golden stamens. Behind them misty karst peaks with waterfalls, a stone arch bridge and distant pavilion roofs, peach trees in full bloom, petals drifting down onto the water. Backlit morning sun, volumetric haze, soft lens bloom, sparkle and ripples on the water in the foreground, shallow depth of field on the blossoms nearest the camera. Ethereal and romantic, with detailed fabric and wet moss textures.
Prompt

Cinematic wide shot in a Chinese xianxia fantasy world, photoreal CG. A young woman in flowing pale pink and mint layered hanfu with long black hair and a jade hairpin stands on a moss-covered fallen tree trunk that bridges a shallow river, gently touching the cheek of a young swordsman in white and grey robes with a sword at his hip; both in profile, close together. Above them a giant translucent pink blossom leans over the trunk, its petals the size of sails with dewdrops on the edges and golden stamens. Behind them misty karst peaks with waterfalls, a stone arch bridge and distant pavilion roofs, peach trees in full bloom, petals drifting down onto the water. Backlit morning sun, volumetric haze, soft lens bloom, sparkle and ripples on the water in the foreground, shallow depth of field on the blossoms nearest the camera. Ethereal and romantic, with detailed fabric and wet moss textures.

04

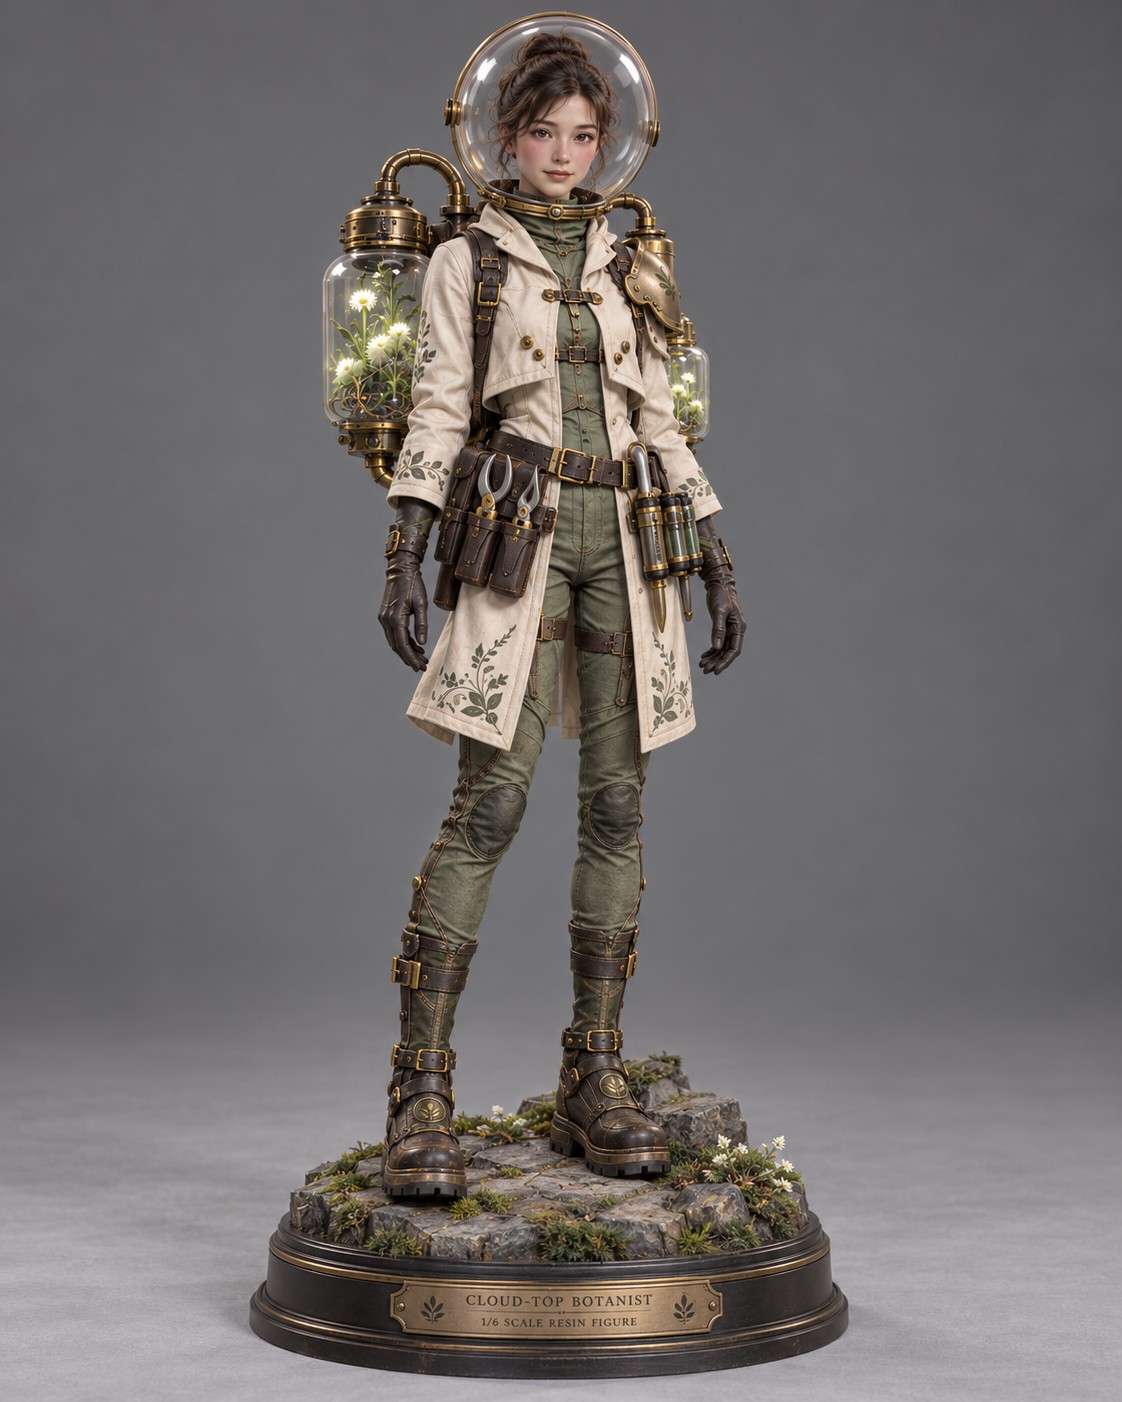
A collectible you could pick up

A 1/6 scale botanist figure on its plinth, glass helmet, brass terrarium tanks and an embroidered canvas coat, shot like a product listing. Glass, brass, leather and cloth each keep their own finish, and the plaque reads “CLOUD-TOP BOTANIST” in full.

A collectible you could pick up: Studio product photograph of a 1/6 scale resin collectible figure: a young woman botanist explorer standing on a rocky mossy base with tiny white wildflowers, wearing a glass dome helmet with brass fittings, a cream canvas coat with green leaf embroidery over an olive utility suit, a leather tool belt holding pruning shears and glass vials, dark leather gloves and tall buckled boots. On her back two brass and glass terrarium canisters with glowing white daisies inside. The figure stands on a round black plinth with a brass plaque reading 'CLOUD-TOP BOTANIST' and a smaller line '1/6 SCALE RESIN FIGURE'. Plain grey seamless backdrop, soft even studio light with a gentle shadow under the base, sharp focus from helmet to boots, visible material finishes: matte fabric, polished brass, clear glass, worn leather. Vertical 3:4 framing.
Prompt

Studio product photograph of a 1/6 scale resin collectible figure: a young woman botanist explorer standing on a rocky mossy base with tiny white wildflowers, wearing a glass dome helmet with brass fittings, a cream canvas coat with green leaf embroidery over an olive utility suit, a leather tool belt holding pruning shears and glass vials, dark leather gloves and tall buckled boots. On her back two brass and glass terrarium canisters with glowing white daisies inside. The figure stands on a round black plinth with a brass plaque reading 'CLOUD-TOP BOTANIST' and a smaller line '1/6 SCALE RESIN FIGURE'. Plain grey seamless backdrop, soft even studio light with a gentle shadow under the base, sharp focus from helmet to boots, visible material finishes: matte fabric, polished brass, clear glass, worn leather. Vertical 3:4 framing.

What you can make with GPT Image 2.5

Group shots where every face is a person

Campaign stills, team pages and social posts with five or six people in frame, each with their own features and expression, lit by whatever light the scene actually has.

Annotated layouts in more than one language

Product sheets, construction details and explainers that pair a photoreal image with labelled callouts, where Chinese and English small print both stay legible.

Scenes and products that read as finished

Cinematic stills for a pitch, or collectibles and packaging shot like a product listing, with glass, metal, fabric and skin each keeping its own finish.

The technology behind GPT Image 2.5

How the model works, based on public documentation and sourced evidence.

GPT Image 2.5 is OpenAI's September 2026 image model, published as a September 8, 2026 snapshot, and it ships as two variants that share one interface: Flare and Sunburst. Flare is the quick one, returning an image in about half the time GPT Image 2 took, and OpenAI names it the default for most applications. Sunburst is the more precise editor of the two and takes longer to render. Both sit on the same price tier, so the choice is speed against editing accuracy rather than budget.

Three things are what OpenAI puts forward. Text placed inside quotation marks is rendered word for word, so interface copy, signage and packaging lines come back as typed. Editing is local: name one element and that element changes while the rest of the frame is left where it was. And composition takes several reference images at once, with the prompt assigning each one its own role. OpenAI's own showcase runs through interface design, portraits, editorial print, graphic design, food photography, architectural visualisation, illustration, and packaging and ecommerce imagery.

In the API a quality setting runs from low up to max and governs both token use and how long a render takes. Size is given either as an aspect ratio or as pixel dimensions whose edges are multiples of 16, with total pixels between 655,360 and 8,294,400. When several images are edited together, a mask applies to the first of them. Transparent backgrounds and streamed partial images exist in the API as well, and OpenAI's prompting guidance leans on naming the subject, the setting and the treatment plainly instead of stacking adjectives.

On Vidney the two variants share a single page with a switch between them. Text to image and image to image are both open, with up to 4 reference images, in 1:1, 4:3, 3:4, 16:9 and 9:16, at 1K, 2K or 4K, where 4K works out to roughly 8.3 million pixels and stands 3840 across at 16:9. Quality is fixed at the middle step, and transparent backgrounds, masked editing and the higher quality steps are not open here. Text to image starts at 3 credits and image to image at 5, with 2K and 4K costing more than 1K.

Sources: openai.com

Who reaches for GPT Image 2.5

GPT Image 2.5 is OpenAI's September 2026 image model, and Vidney puts both of its variants on one page: Flare, the faster of the two and OpenAI's own default for most work, and Sunburst, the slower one built for precise edits. Both run text to image and image to image, take up to four reference images, and cover 1:1, 4:3, 3:4, 16:9 and 9:16 at 1K, 2K or 4K, where 4K works out to roughly 8.3 million pixels. Quality sits at a fixed middle step here, and transparent backgrounds, masked editing and the higher quality steps stay closed for now. Reach for it when the words inside the frame have to be right the first time.

How to generate image with GPT Image 2.5

Create AI image with GPT Image 2.5 on Vidney in three steps.

Glowing panels with one model selected from severalStreams of light forming into an emerging imageA finished image materializing from a vortex of glowing light

GPT Image 2.5 vs Muse Image vs Midjourney V8.1 vs Grok Imagine Image 2.0

Specs side by side with similar models, all runnable on Vidney.

GPT Image 2.5Muse ImageMidjourney V8.1Grok Imagine Image 2.0
Task modesText to Image · Image to ImageText to Image · Image to ImageText to Image · Image to ImageText to Image · Image to Image
Resolution1K · 2K · 4K1K · 2K
Cost3–5 credits per generation3 credits per generation18 credits per generation9–15 credits per generation

What creators say about GPT Image 2.5

Recurring themes from public reviews, comparisons and creator write-ups. Both the good and the bad.

What gets praised

  • Reviewers single out how literally it obeys: counts, times of day and spatial relations asked for in a prompt come back as asked, which is what makes it usable for briefs that have to be followed rather than interpreted.

  • Text rendering draws the most consistent praise. Interface copy, signage and printed matter come back readable at the size they were asked for, so a mockup can be shown to a client without a pass of pasting real words over filler.

  • Editing is the other reason people stay with it. Naming one element and changing only that element holds up across a series, so a product line or a set of covers can be revised without relighting the original shot.

Common complaints

  • Long prompts stacking many elements still slip, with a detail or two dropped or merged, so a complex composition usually needs more than one pass before it is right.

  • Reviewers also note that the native output size has a ceiling, so work headed for large format needs enlarging afterwards, and that fine areas occasionally come back with visible noise.

Related models

More AI image models you can run on Vidney.

Live

Generate AI image with GPT Image 2.0: text to image and image to image, all from one Vidney workspace.

3 credits per generation
Live

Generate AI image with GPT Image 1.5: text to image and image to image, all from one Vidney workspace.

3 credits per generation
Live

Meta's image model checks its own draft before the picture comes back.

3 credits per generation
Live

Generate AI image with Nano Banana 2: text to image and image to image, all from one Vidney workspace.

3 credits per generation
MidjourneyMidjourney V7
Live

Generate AI image with Midjourney V7: text to image and image to image, all from one Vidney workspace.

6 credits per generation
Live

Generate AI image with Nano Banana: text to image and image to image, all from one Vidney workspace.

6 credits per generation

Frequently asked questions

What is GPT Image 2.5?

GPT Image 2.5 is an AI image model you can run on Vidney. It supports text to image and image to image from a single workspace.

How much does GPT Image 2.5 cost per generation?

GPT Image 2.5 costs 3–5 credits per generation. The exact credit cost is shown on the generate button before you run it.

What aspect ratios does GPT Image 2.5 support?

GPT Image 2.5 supports the following aspect ratios: 1:1, 4:3, 3:4, 16:9, 9:16.

Is GPT Image 2.5 free to use?

You can start with GPT Image 2.5 for free on Vidney using your sign-up credits, no card required to try it. After that each run costs 3–5 credits per generation, and the exact cost is always shown on the generate button before you spend a credit.

Can I use GPT Image 2.5 images commercially?

Yes. The images you generate with GPT Image 2.5 on Vidney are yours to use in commercial projects: ads, social posts, client work, and product content. You keep the output; Vidney only handles generation and storage.

Does GPT Image 2.5 add a watermark?

No. GPT Image 2.5 images generated on Vidney are delivered clean, with no Vidney watermark, ready to publish or hand to a client as-is.

What are the best GPT Image 2.5 alternatives?

The closest GPT Image 2.5 alternatives on Vidney are Muse Image, Midjourney V8.1, and Grok Imagine Image 2.0. They all run in the same workspace from one credit balance, so you can run the same prompt on each and compare the results side by side.

Do I need an API key or a provider account to use GPT Image 2.5?

No. Vidney runs GPT Image 2.5 for you, so there are no API keys to manage and no separate provider account to set up.

Create with GPT Image 2.5 now