Vidney

AI画像生成

Muse Image

Meta の画像モデルは、返す前に自分の下描きを自分で見直します。

Vidney ワークベンチ

モデル 21 件
0/2000
必要:3 クレジット

出力

サンプル

Muse Image が得意なこと

01

アニメ映画の一コマ

山岳鉄道が夕暮れの高架橋を渡ります。水彩で描かれた谷の上に、澄んだセル画の線。長編から抜き出した一枚に見えます。客車の窓の明かりまで含めて。
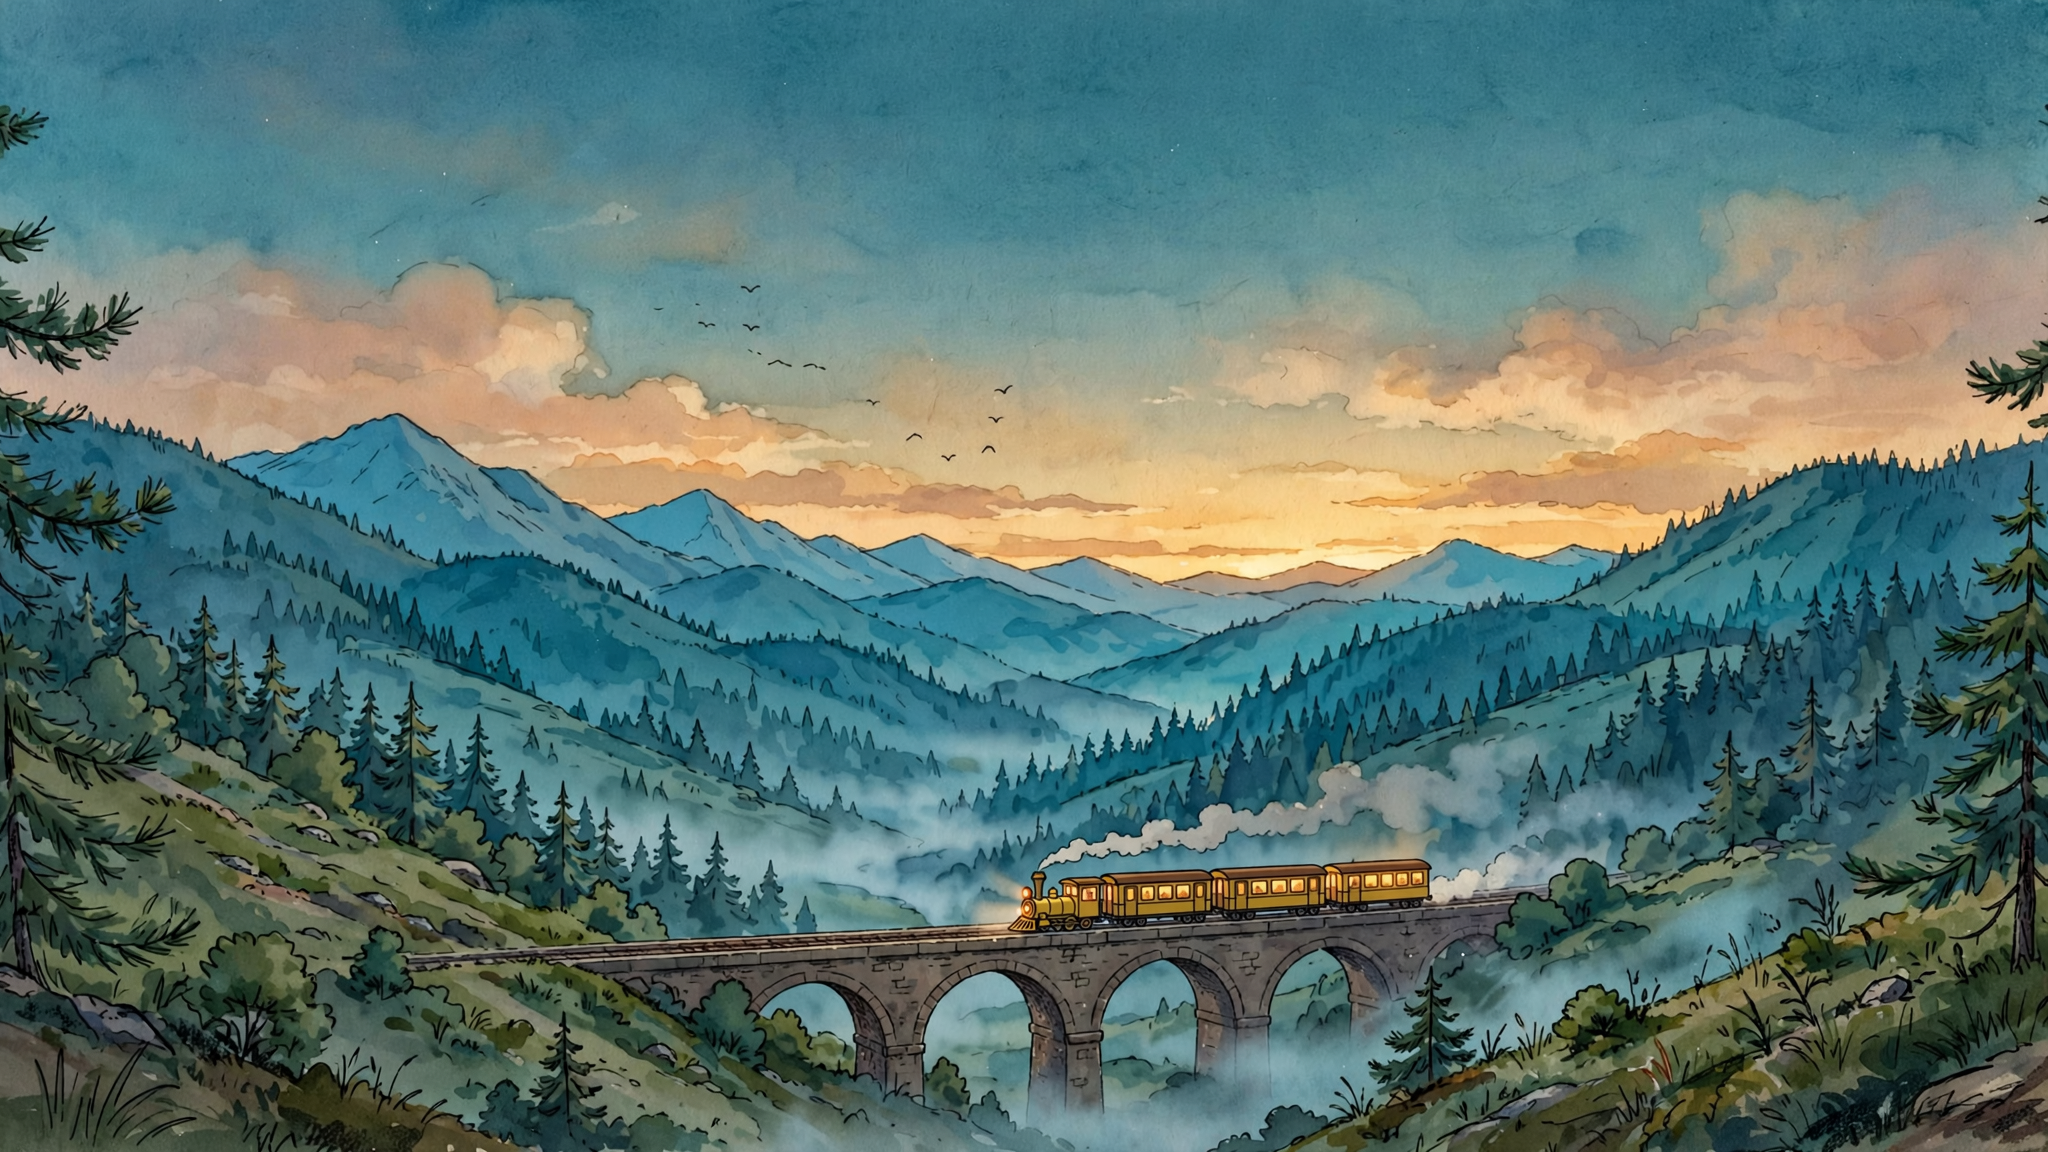
アニメ映画の一コマ: A single frame from a hand drawn 2D animated feature: a small yellow mountain train crosses a stone viaduct at dusk, seen from a hillside across the valley. Cel shaded train with clean confident linework and flat warm colours, lit carriage windows glowing amber, a thin trail of steam behind it. Painted watercolour background of pine forest, layered blue ridges and a deep teal sky with the last warm light on the horizon, soft mist gathering in the valley floor. Wide composition with the viaduct running across the lower third, generous sky above, a few birds as small dark marks. Quiet, warm, unhurried mood, the look of a studio feature still rather than a digital illustration, subtle film grain. No people, no text, no signature, no watermark.
プロンプト

A single frame from a hand drawn 2D animated feature: a small yellow mountain train crosses a stone viaduct at dusk, seen from a hillside across the valley. Cel shaded train with clean confident linework and flat warm colours, lit carriage windows glowing amber, a thin trail of steam behind it. Painted watercolour background of pine forest, layered blue ridges and a deep teal sky with the last warm light on the horizon, soft mist gathering in the valley floor. Wide composition with the viaduct running across the lower third, generous sky above, a few birds as small dark marks. Quiet, warm, unhurried mood, the look of a studio feature still rather than a digital illustration, subtle film grain. No people, no text, no signature, no watermark.

02

数字の合う図表

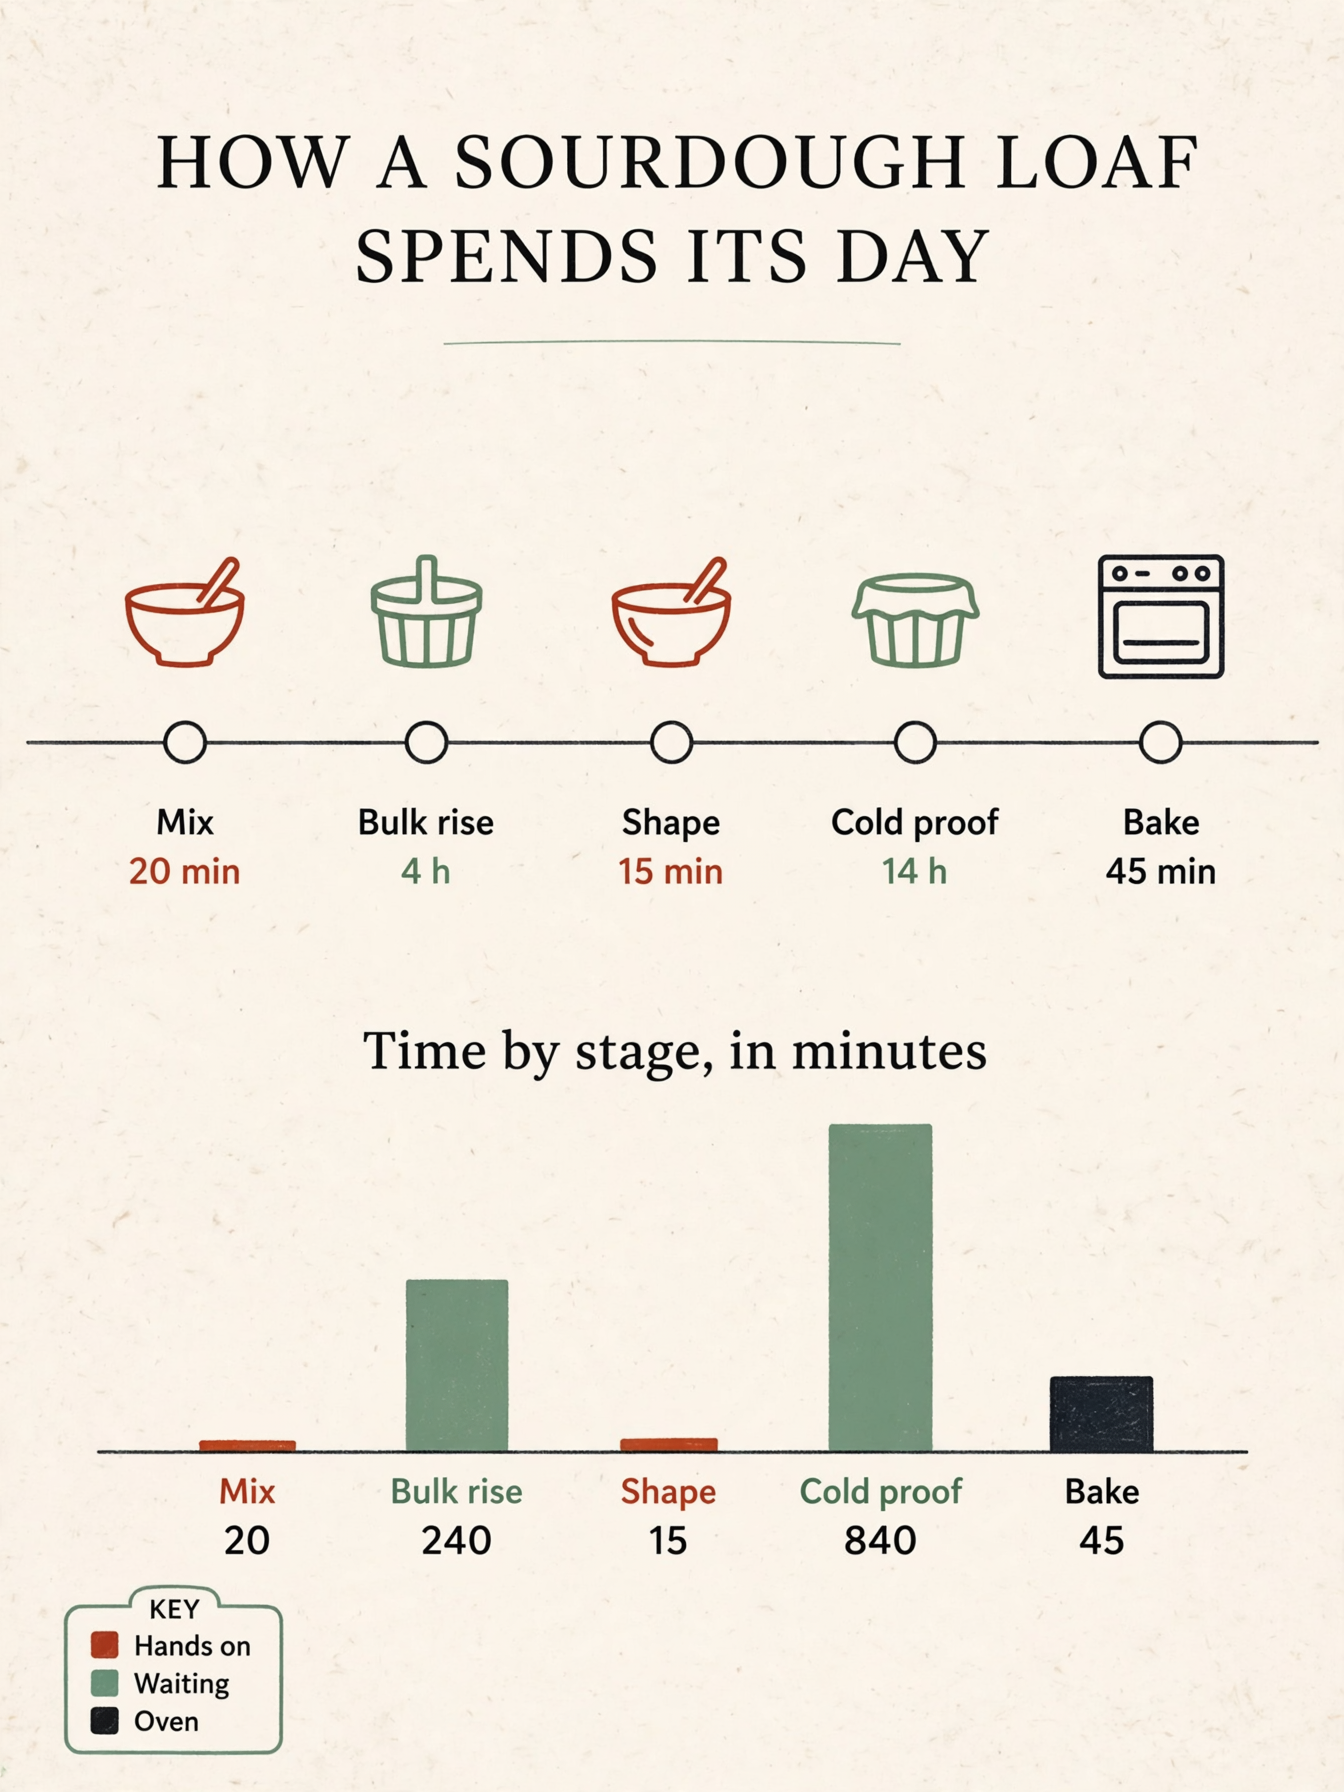
1ページの焼成タイムライン。棒の高さが、下に印刷された数字とちゃんと一致します。ラベルと数値が食い違いません。描き直さずにそのまま資料へ入れられます。

数字の合う図表: A single page printed infographic titled 'HOW A SOURDOUGH LOAF SPENDS ITS DAY', portrait layout on warm off-white paper. Across the middle runs a horizontal timeline with five labelled stages and their durations, in order 'Mix 20 min', 'Bulk rise 4 h', 'Shape 15 min', 'Cold proof 14 h', 'Bake 45 min'. Below it sits a simple bar chart titled 'Time by stage, in minutes' with five bars whose heights are strictly proportional to the values 20, 240, 15, 840 and 45, so the 840 bar is three and a half times as tall as the 240 bar and the 20 bar is barely visible, each bar labelled with its own number under it. A small key in the lower left carries three colour swatches labelled 'Hands on', 'Waiting', 'Oven'. Flat editorial design in ink black, warm clay red and sage green, thin rules, clear type hierarchy, plenty of whitespace, three simple line icons for a mixing bowl, a proofing basket and an oven. All labels short and legible, spelled exactly as written, every number matching its bar. No other text, no logos, no watermark.
プロンプト

A single page printed infographic titled 'HOW A SOURDOUGH LOAF SPENDS ITS DAY', portrait layout on warm off-white paper. Across the middle runs a horizontal timeline with five labelled stages and their durations, in order 'Mix 20 min', 'Bulk rise 4 h', 'Shape 15 min', 'Cold proof 14 h', 'Bake 45 min'. Below it sits a simple bar chart titled 'Time by stage, in minutes' with five bars whose heights are strictly proportional to the values 20, 240, 15, 840 and 45, so the 840 bar is three and a half times as tall as the 240 bar and the 20 bar is barely visible, each bar labelled with its own number under it. A small key in the lower left carries three colour swatches labelled 'Hands on', 'Waiting', 'Oven'. Flat editorial design in ink black, warm clay red and sage green, thin rules, clear type hierarchy, plenty of whitespace, three simple line icons for a mixing bowl, a proofing basket and an oven. All labels short and legible, spelled exactly as written, every number matching its bar. No other text, no logos, no watermark.

03

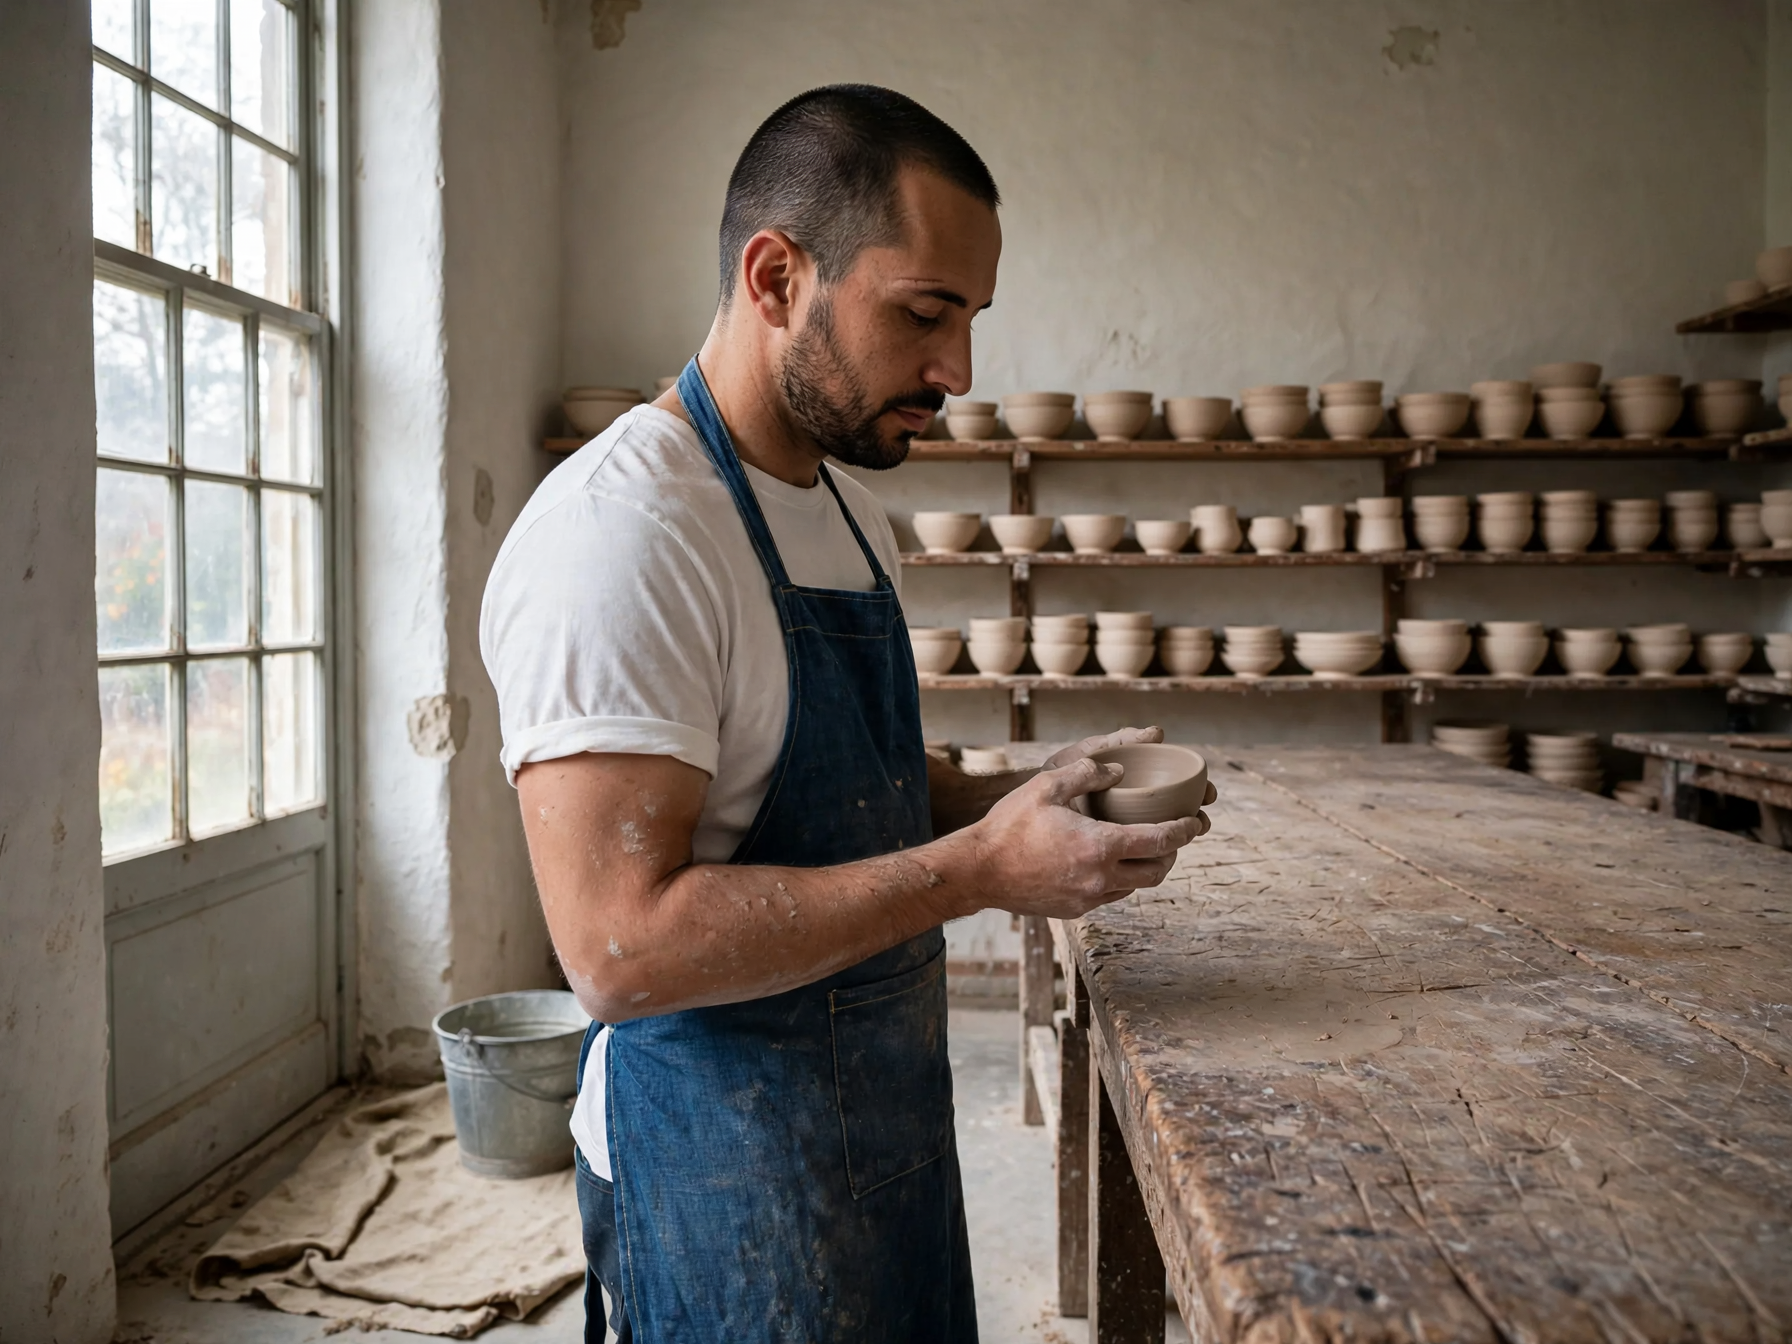
参考3枚から写真1枚

顔は1枚目、エプロンは2枚目、工房は3枚目から。それが1枚の写真として返ります。エプロンは縫い目もポケットも保ったまま、窓の光は人にも部屋にも同じように落ちます。

参考3枚から写真1枚: Use the first reference for the person, the second for the garment and the third for the setting. Keep the same man, his face, beard, haircut and build unchanged, and place him standing at the long workbench from the third reference, wearing the indigo cross back linen apron from the second reference over a plain white tee with the sleeves pushed to the elbow. Three quarter view from camera left, he is turning a small unglazed bowl in his hands and looking down at it. Match the light of the room: soft daylight from the tall window on the left, warm bounce off the plaster wall, a short shadow under the bench. The apron ties, topstitching and pocket shape stay exactly as in the reference, and the room keeps its own props and layout. Natural skin texture, fine linen weave, clay dust on the forearms, photoreal, 50mm lens, shallow depth of field. No extra people, no text, no logos, no watermark.
プロンプト

Use the first reference for the person, the second for the garment and the third for the setting. Keep the same man, his face, beard, haircut and build unchanged, and place him standing at the long workbench from the third reference, wearing the indigo cross back linen apron from the second reference over a plain white tee with the sleeves pushed to the elbow. Three quarter view from camera left, he is turning a small unglazed bowl in his hands and looking down at it. Match the light of the room: soft daylight from the tall window on the left, warm bounce off the plaster wall, a short shadow under the bench. The apron ties, topstitching and pocket shape stay exactly as in the reference, and the room keeps its own props and layout. Natural skin texture, fine linen weave, clay dust on the forearms, photoreal, 50mm lens, shallow depth of field. No extra people, no text, no logos, no watermark.

Muse Image で作れるもの

誰も撮っていない映画のスチル

アニメ長編のある一瞬を指定すれば、その一コマが返ります。セル画の線に描き込んだ背景、絵コンテの前に空気が決まります。

見せて崩れない1ページ解説

タイムライン、棒、凡例のラベルと数値が一致するので、資料にも配布物にも、デザイナーが描き直さずに入ります。

同じ人物に、別の服と場所

顔と服と場所を別々の写真から集めて1枚にまとめます。チームの人物写真、ルックブック、繰り返し出るキャラクターに向きます。

Muse Image を選ぶ場面

Muse Image は Meta Superintelligence Labs の画像モデルで、2026年7月に Meta AI と同時に公開され、その週の Arena ではテキストから画像、単一画像の編集、複数画像の編集のいずれでも2位に入りました。道具を使うモデルです。図表や QR コードを正確にするためにコードを書き、描く前に事実を調べ、最初の一枚を自分で批評して描き直してから渡します。Vidney ではテキストから画像と画像から画像が使え、参考画像は最大10枚、比率は 1:1、4:3、3:4、16:9、9:16。出力サイズは1種類で解像度の選択はなく、1回3クレジットです。絵が中身の事実と食い違ってはいけないときに選んでください。

Muse Imageで画像を生成する方法

VidneyでMuse Imageを使い、3ステップでAI画像を作成します。

Glowing panels with one model selected from severalStreams of light forming into an emerging imageA finished image materializing from a vortex of glowing light

Muse Image vs GPT Image 2.5 vs Midjourney V8.1 vs Grok Imagine Image 2.0

類似モデルとスペックを並べて比較。すべて Vidney で実行できます。

Muse ImageGPT Image 2.5Midjourney V8.1Grok Imagine Image 2.0
タスクモードテキストから画像 · 画像から画像テキストから画像 · 画像から画像テキストから画像 · 画像から画像テキストから画像 · 画像から画像
解像度1K · 2K · 4K1K · 2K
コスト1回の生成につき3クレジット1回の生成につき3〜5クレジット1回の生成につき18クレジット1回の生成につき9〜15クレジット

関連モデル

Vidneyで実行できるAI画像モデルをほかにもご覧ください。

公開中

同じページに2つの速さ、打ち込んだ文字はそのまま綴られて返ります。

1回の生成につき3〜5クレジット
公開中

Nano Banana 2でAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき3クレジット
公開中

GPT Image 2.0でAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき3クレジット
公開中

GPT Image 1.5でAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき3クレジット
MidjourneyMidjourney V7
公開中

Midjourney V7でAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき6クレジット
公開中

Nano BananaでAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき6クレジット

よくある質問

Muse Imageとは何ですか?

Muse ImageはVidneyで実行できるAI画像モデルです。1つのスタジオでテキストから画像と画像から画像に対応しています。

Muse Imageは1回の生成でいくらかかりますか?

Muse Imageは1回の生成につき3クレジットです。正確なクレジットコストは、実行前に生成ボタンへ表示されます。

Muse Imageはどのアスペクト比に対応していますか?

Muse Imageは次のアスペクト比に対応しています:1:1、4:3、3:4、16:9、9:16。

Muse Imageは無料で使えますか?

はい。Vidneyに登録すると付与されるクレジットで、Muse Imageを無料で試せます。お試しにクレジットカードは不要です。以降は1回の生成につき3クレジットで、正確なコストはクレジットを使う前に必ず生成ボタンへ表示されるので、知らないうちに課金されることはありません。

Muse Imageで作った画像は商用利用できますか?

はい。VidneyでMuse Imageを使って生成した画像は、商用プロジェクトに自由に使えます。広告、SNS投稿、クライアントワーク、商品ビジュアルなどに利用可能です。成果物の権利はあなたのもので、Vidneyは生成と保存を担うだけです。

Muse Imageは透かし(ウォーターマーク)を入れますか?

いいえ。Vidneyで生成したMuse Imageの画像は透かしのないクリーンな状態で書き出されます。Vidneyのロゴは入らないので、そのまま公開したりクライアントへ納品したりできます。

Muse Imageの代わりに使えるおすすめのモデルは?

VidneyでMuse Imageに最も近いのはGPT Image 2.5、Midjourney V8.1およびGrok Imagine Image 2.0です。どれも同じワークスペース内で共通のクレジット残高から使えるので、同じプロンプトをそれぞれのモデルで実行して、結果を並べて見比べられます。

Muse Imageを使うのにAPIキーやプロバイダーアカウントは必要ですか?

いいえ。Vidneyがあなたに代わってMuse Imageを実行します。管理すべきAPIキーも、別途用意するプロバイダーアカウントもありません。

今すぐMuse Imageで作成