速いほう
Flare
たいていの作業は Flare から始めるのがおすすめです。Flare の強みは速さで、レイアウトを待つのではなく試行を重ねられる速さで返ってきます。私たち自身の計測では、4K が 47 秒で完成しました。この世代の持ち味である文字の再現と部分的な修正は、そのままこちらでも使えます。
こんなときに
- 最初の下書きと方向性の探索
- 1 つのブリーフから複数のバリエーションを量産
- 何度も直しを重ねる画面やポスター
AI画像生成
同じページに2つの速さ、打ち込んだ文字はそのまま綴られて返ります。
出力
GPT Image 2.5 には 2 つのバージョンがあり、このページではどちらも同じ料金で使えます。違いは速さと精度です。
OpenAI は GPT Image 2.5 を、同じインターフェースを共有する 2 つのバリアントとして提供しています。この世代の特長として挙げられる、引用符で囲んだ文字を書いたとおりに描くことと、指定した要素だけを直すことは、どちらのバリアントも同じようにこなします。要素の多いプロンプトでは、どちらでももう一度出し直すことがあります。Flare は OpenAI が多くの用途の既定として挙げるほうで、GPT Image 2 の約半分の時間で画像を返します。Sunburst は精度を最優先し、複雑なディテールをより忠実に保ちますが、完成までに時間がかかります。Vidney では両者とも同じプロンプト、最大 4 枚の参照画像、同じ 5 種類のアスペクト比、同じ 1K・2K・4K のサイズを受け付け、どのサイズでもクレジットは同額です。選択が影響するのは残高ではなく、待ち時間と仕上がりだけです。
速いほう
たいていの作業は Flare から始めるのがおすすめです。Flare の強みは速さで、レイアウトを待つのではなく試行を重ねられる速さで返ってきます。私たち自身の計測では、4K が 47 秒で完成しました。この世代の持ち味である文字の再現と部分的な修正は、そのままこちらでも使えます。
こんなときに
正確なほう
Sunburst は 2 つのうち、より正確に修正できるほうで、何ひとつずれてはいけない 1 枚のためのものです。要素を 1 つ指定すれば、残りの画面はそのまま残るように作られています。4K では看板の小さな文字のような細部も、拡大して読める大きさで描かれます。その丁寧さは時間と引き換えです。Flare が 47 秒で終えた同じ 4K を、Sunburst は 64 秒かけて描きました。
こんなときに
まず Flare で始め、編集を崩したくないとき、細部を近くで見られるときに Sunburst へ切り替えてください。どちらも上のジェネレーターのモデルメニューに GPT Image 2.5 Flare と GPT Image 2.5 Sunburst として並んでおり、クレジットは同じです。
深夜のコンビニの前にいる 5 人の友人を、店の窓明かりと街灯 1 本だけで撮った 1 枚。顔はそれぞれ別の人物として描かれ、笑い方も目つきも違い、蛍光灯の下の肌には本物の質感があります。誰もカメラに向かってポーズをとっていません。
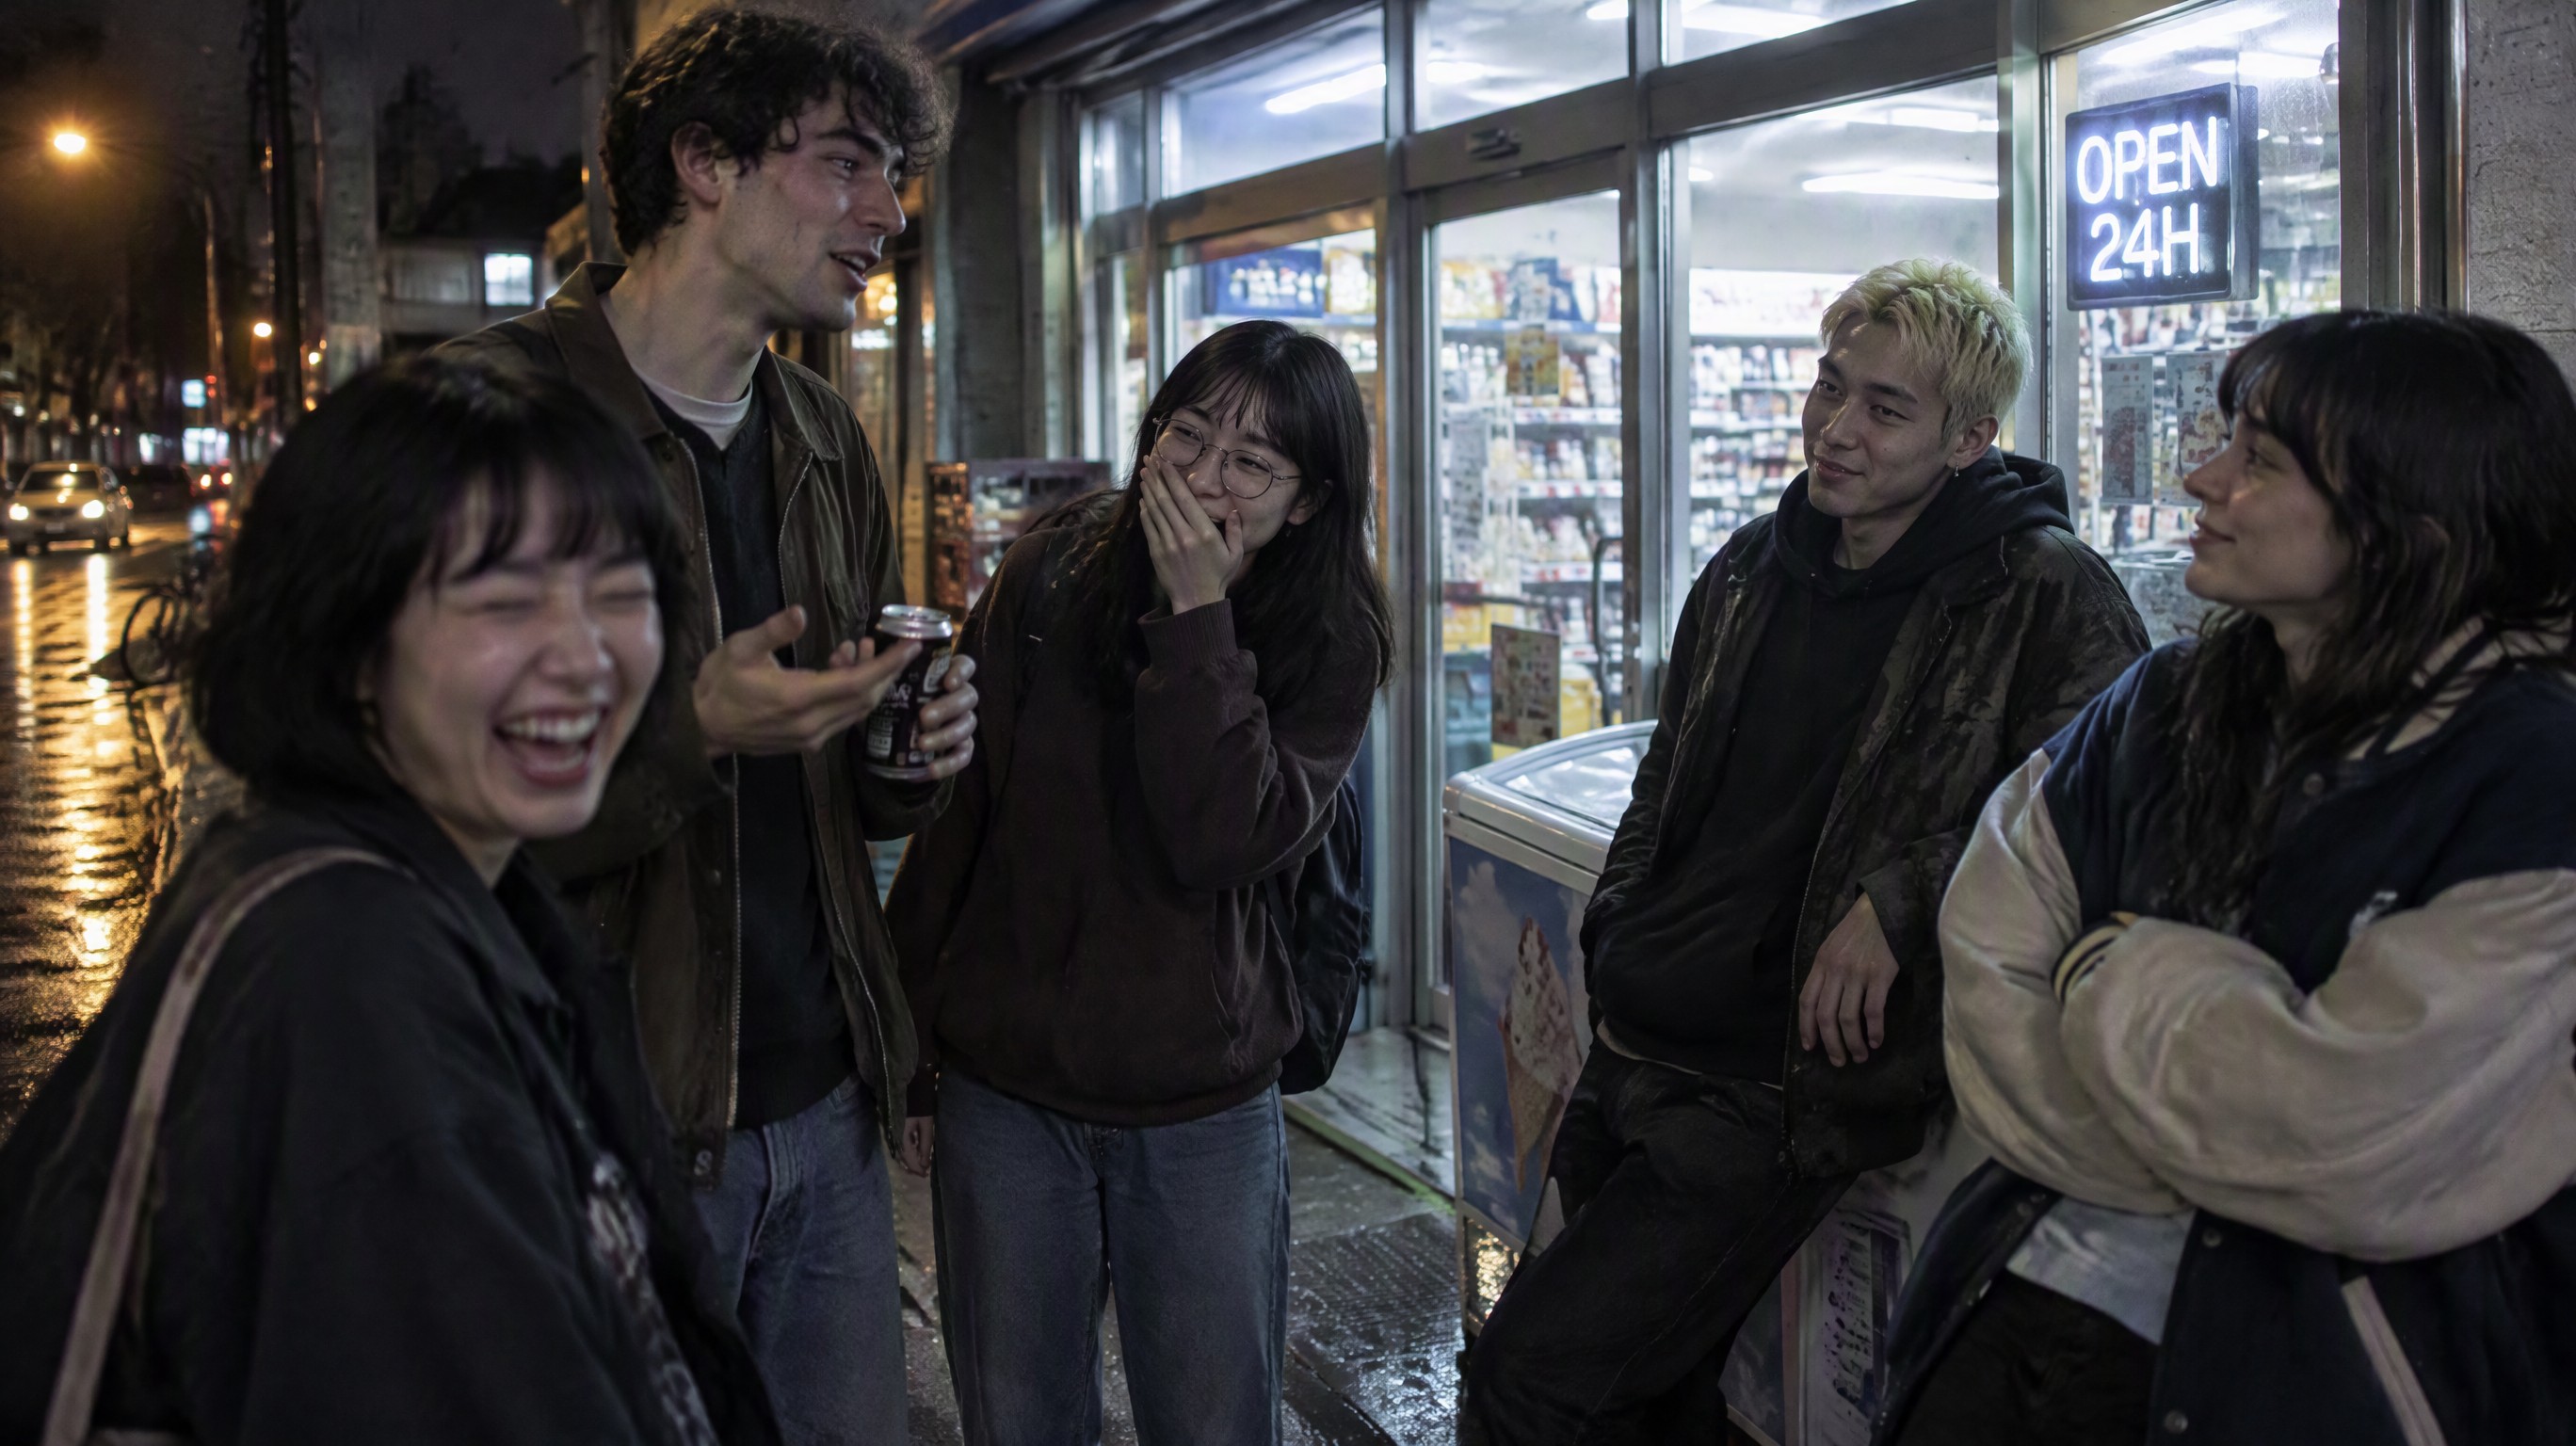
Photorealistic candid photograph of five friends in their early twenties hanging out on the sidewalk in front of a small 24-hour convenience store late at night, laughing and talking in the middle of a story. Each face is clearly different and clearly lit: a young woman with a short black bob laughing with her eyes squeezed shut, a tall young man mid-sentence gesturing with a canned coffee, a young woman in round glasses covering her grin with one hand, a young man with bleached hair leaning against the ice-cream freezer by the door with a lopsided smirk, and a young woman in an oversized varsity jacket looking sideways at her friend with a fond half-smile. Natural mixed lighting only: cool white fluorescent light spilling from the store windows onto the pavement, one warm streetlamp far to the left, soft reflections on slightly damp asphalt. Shot on a 35mm lens at f/2 from a few steps away, the friend nearest the camera slightly out of focus, real skin texture with pores and a little shine, no beauty retouching, nobody posing for the camera. The storefront is generic and unbranded; the only readable text is a small glowing sign reading 'OPEN 24H'. Documentary photography, muted colours, faint film grain.
左は海にせり出すガラス張りのレストラン、右はその断面ディテール。青銅パネルから岩盤アンカーまで、7 つの中国語の注記が並びます。注記の文字はすべて判読でき、図と写真は部位ごとに対応しています。
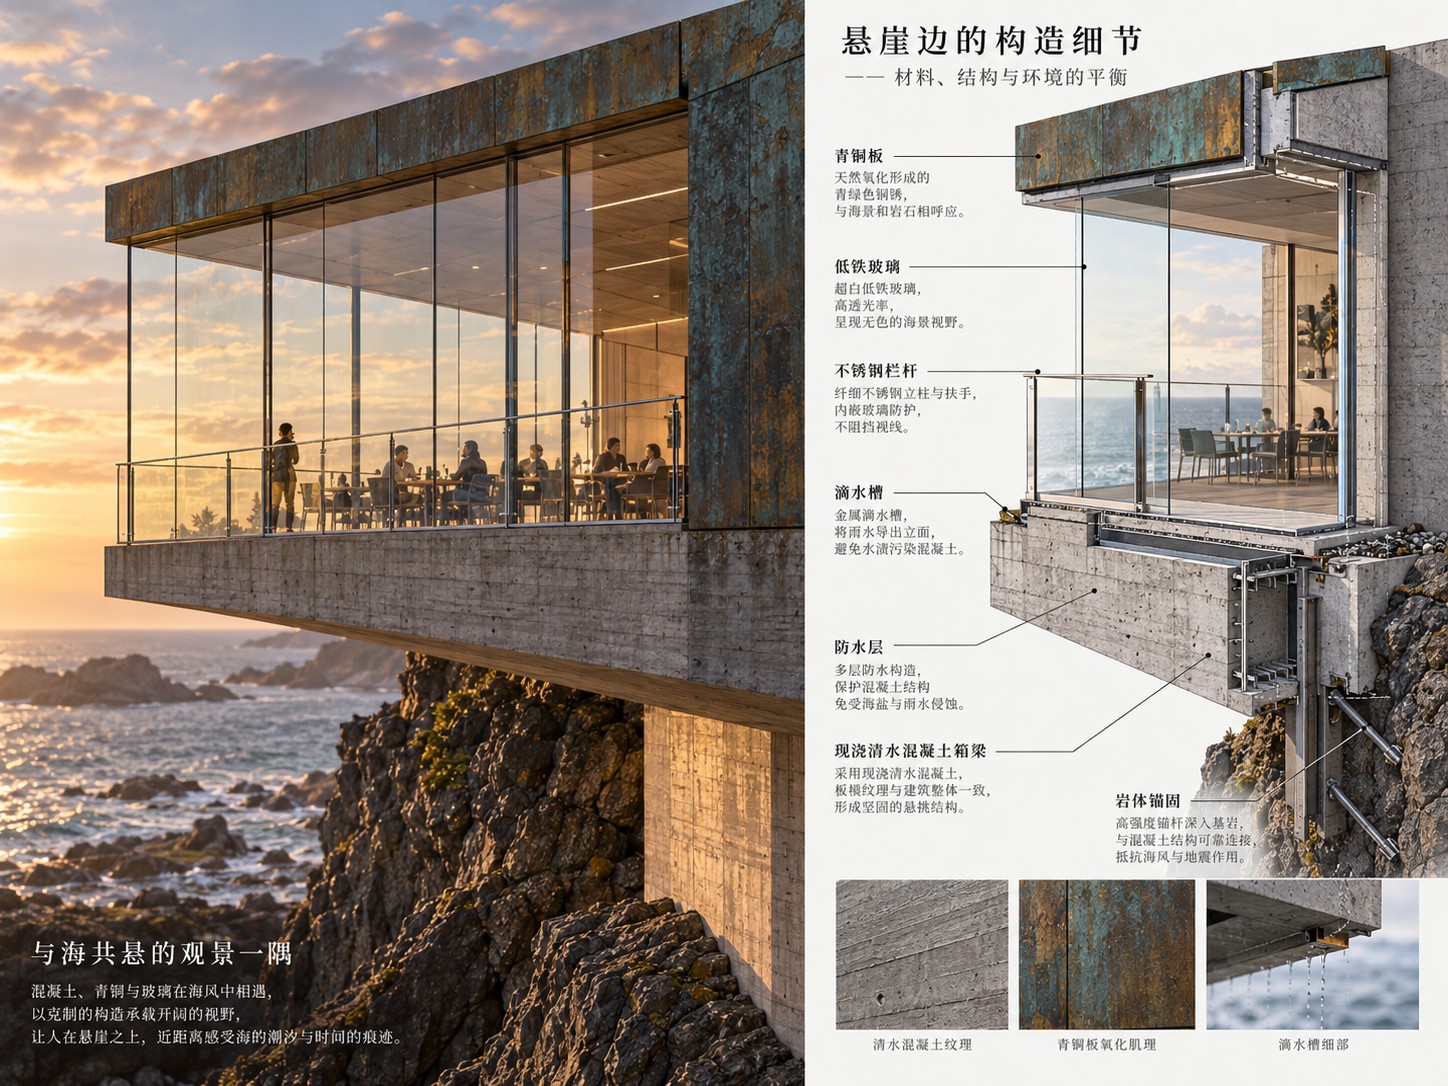
A two-part editorial spread on one 4:3 canvas. Left half: a photorealistic architectural photograph at golden hour of a small glass-walled restaurant cantilevered from a dark basalt cliff over the sea, the box clad in green-patinated bronze panels and carried on a raw board-marked concrete beam, floor to ceiling low-iron glazing with a thin stainless steel guardrail, diners at tables inside lit by the low sun, waves breaking on the rocks below, soft clouds. Right half on warm off-white paper: an annotated construction detail of the same cantilever drawn as a clean cut-away render with hairline leader lines, titled '悬崖边的构造细节' with the subtitle '材料、结构与环境的平衡', and seven callouts in Chinese reading '青铜板', '低铁玻璃', '不锈钢栏杆', '滴水槽', '防水层', '现浇清水混凝土箱梁', '岩体锚固', each with two or three short lines of explanation in small grey type; along the bottom three small material swatches captioned '清水混凝土纹理', '青铜板氧化肌理', '滴水槽细部'. Bottom left of the photograph a white caption block reading '与海共悬的观景一隅' with three short lines of copy beneath. Editorial typography, generous margins, every character rendered clearly, no other text.
川に架かる苔むした倒木の上に漢服の二人。頭上には縁に露をためた半透明の桃色の花弁、背後にはカルスト峰と滝が霞へ溶けていきます。逆光、霧、濡れた苔がひとつの光として描かれ、焦点の合った衣のひだは鮮明です。
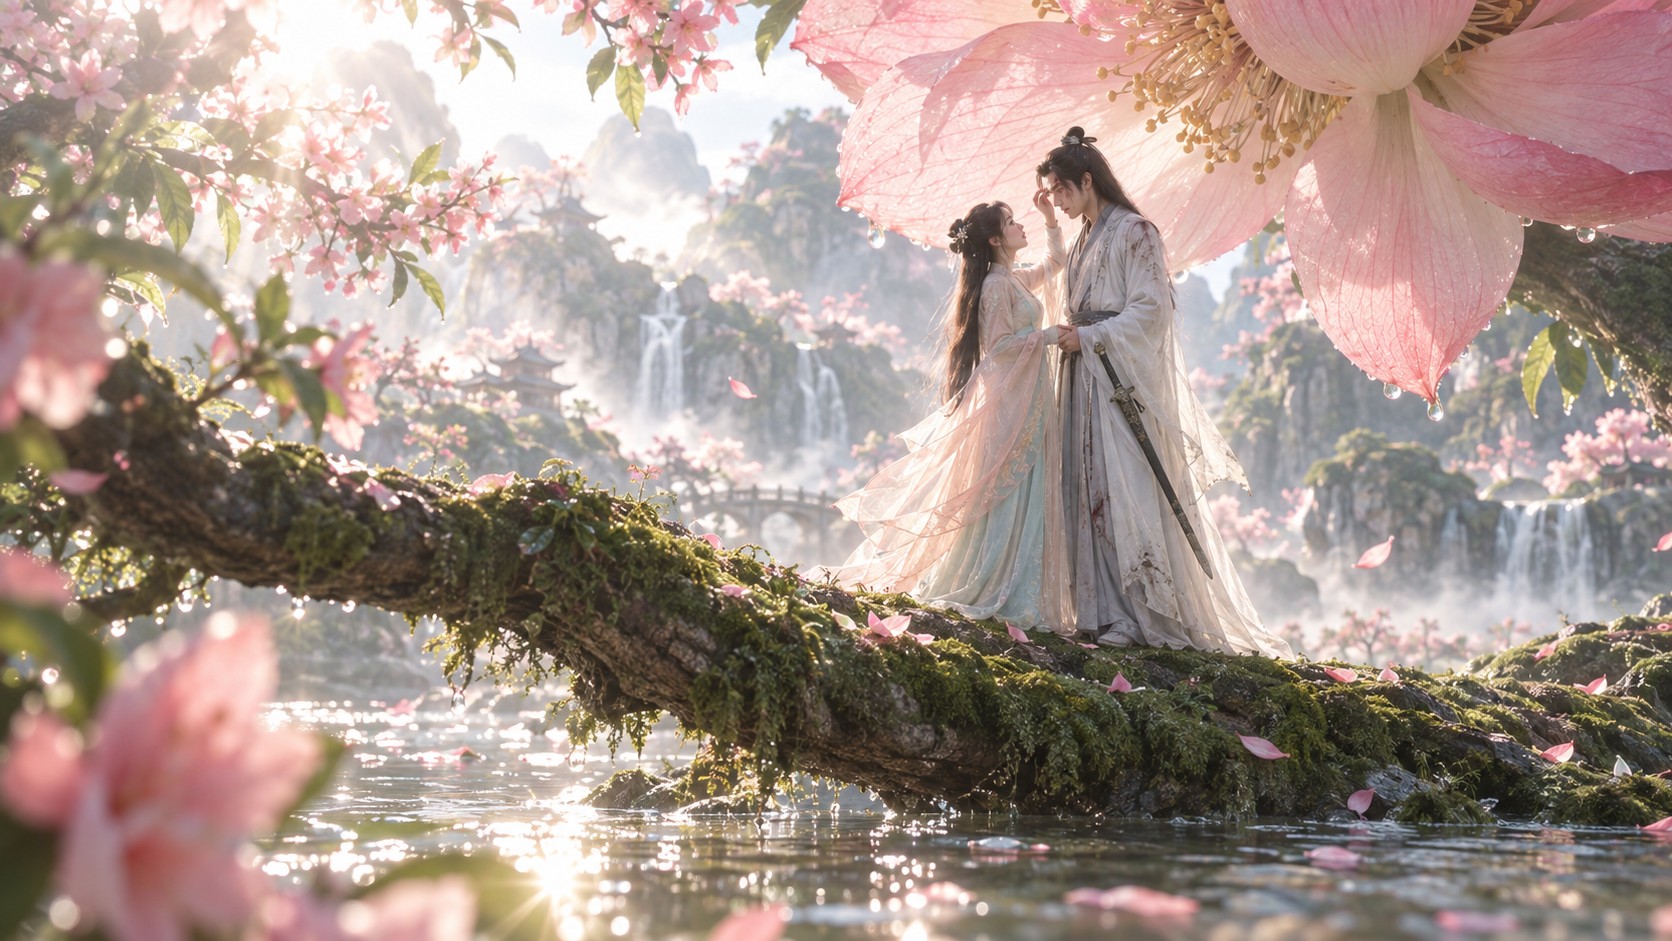
Cinematic wide shot in a Chinese xianxia fantasy world, photoreal CG. A young woman in flowing pale pink and mint layered hanfu with long black hair and a jade hairpin stands on a moss-covered fallen tree trunk that bridges a shallow river, gently touching the cheek of a young swordsman in white and grey robes with a sword at his hip; both in profile, close together. Above them a giant translucent pink blossom leans over the trunk, its petals the size of sails with dewdrops on the edges and golden stamens. Behind them misty karst peaks with waterfalls, a stone arch bridge and distant pavilion roofs, peach trees in full bloom, petals drifting down onto the water. Backlit morning sun, volumetric haze, soft lens bloom, sparkle and ripples on the water in the foreground, shallow depth of field on the blossoms nearest the camera. Ethereal and romantic, with detailed fabric and wet moss textures.
台座に立つ 1/6 スケールの植物学者フィギュア。ガラスのヘルメット、真鍮のテラリウムタンク、刺繍入りのキャンバスコートを商品写真のように撮影。ガラス、真鍮、革、布がそれぞれの質感を保ち、銘板の「CLOUD-TOP BOTANIST」も欠けなく読めます。
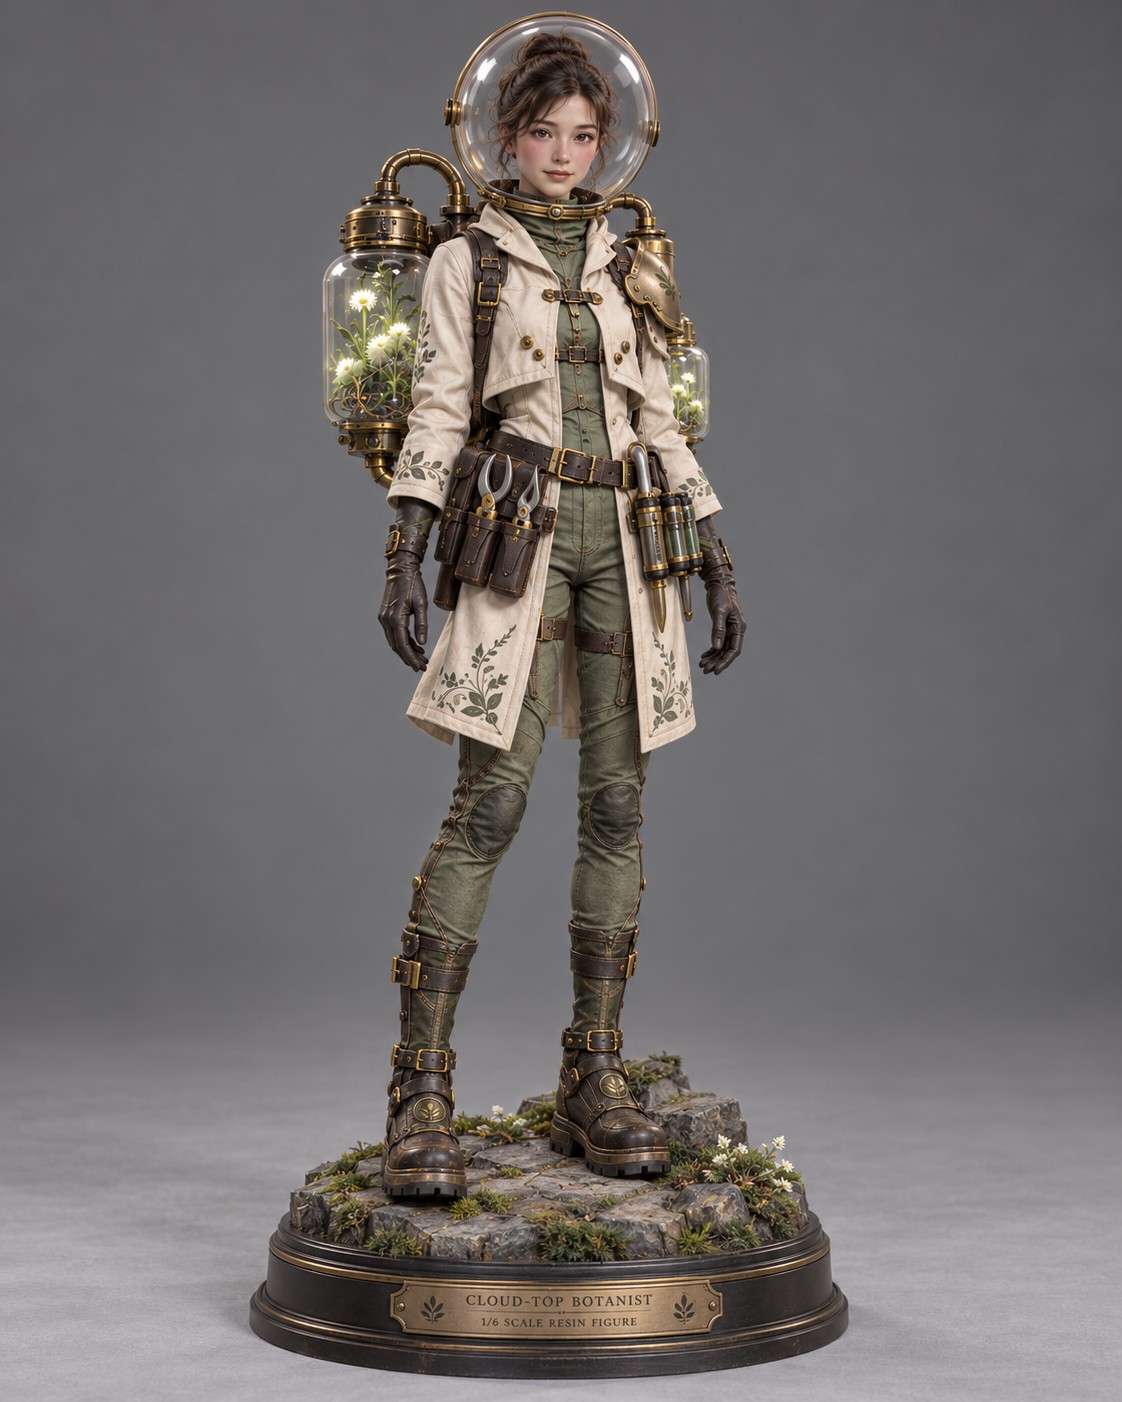
Studio product photograph of a 1/6 scale resin collectible figure: a young woman botanist explorer standing on a rocky mossy base with tiny white wildflowers, wearing a glass dome helmet with brass fittings, a cream canvas coat with green leaf embroidery over an olive utility suit, a leather tool belt holding pruning shears and glass vials, dark leather gloves and tall buckled boots. On her back two brass and glass terrarium canisters with glowing white daisies inside. The figure stands on a round black plinth with a brass plaque reading 'CLOUD-TOP BOTANIST' and a smaller line '1/6 SCALE RESIN FIGURE'. Plain grey seamless backdrop, soft even studio light with a gentle shadow under the base, sharp focus from helmet to boots, visible material finishes: matte fabric, polished brass, clear glass, worn leather. Vertical 3:4 framing.
キャンペーンのスチール、チーム紹介ページ、SNS 投稿。5、6 人が写っていても一人ひとりの顔立ちと表情が違い、光はその場にある光のままです。
製品シート、構造ディテール、解説図。写真のような画像とラベル付きの注記を同じ紙面に置いても、中国語と英語の小さな文字がどちらも読めます。
企画提案用の映画的なスチール、あるいは商品ページのように撮ったフィギュアやパッケージ。ガラス、金属、布、肌がそれぞれの質感を保ちます。
GPT Image 2.5 は OpenAI が2026年9月に公開した画像モデルで、Vidney では2つの版を同じページに置いています。速いほうの Flare は OpenAI 自身が多くの用途で既定にしている版、遅いほうの Sunburst は精密な修正のための版です。どちらもテキストから画像、画像から画像に対応し、参考画像は最大4枚。比率は 1:1、4:3、3:4、16:9、9:16、出力は 1K、2K、4K で、4K はおよそ830万画素にあたります。品質は中間の段に固定で、透明背景、マスク編集、上位の品質段はいまは開いていません。画面の中の文字が一度で正しくないと困る仕事に向きます。
VidneyでGPT Image 2.5を使い、3ステップでAI画像を作成します。
類似モデルとスペックを並べて比較。すべて Vidney で実行できます。
| GPT Image 2.5 | Muse Image | Midjourney V8.1 | Grok Imagine Image 2.0 | |
|---|---|---|---|---|
| タスクモード | テキストから画像 · 画像から画像 | テキストから画像 · 画像から画像 | テキストから画像 · 画像から画像 | テキストから画像 · 画像から画像 |
| 解像度 | 1K · 2K · 4K | — | — | 1K · 2K |
| コスト | 1回の生成につき3〜5クレジット | 1回の生成につき3クレジット | 1回の生成につき18クレジット | 1回の生成につき9〜15クレジット |
Vidneyで実行できるAI画像モデルをほかにもご覧ください。
GPT Image 2.5はVidneyで実行できるAI画像モデルです。1つのスタジオでテキストから画像と画像から画像に対応しています。
GPT Image 2.5は1回の生成につき3〜5クレジットです。正確なクレジットコストは、実行前に生成ボタンへ表示されます。
GPT Image 2.5は次のアスペクト比に対応しています:1:1、4:3、3:4、16:9、9:16。
はい。Vidneyに登録すると付与されるクレジットで、GPT Image 2.5を無料で試せます。お試しにクレジットカードは不要です。以降は1回の生成につき3〜5クレジットで、正確なコストはクレジットを使う前に必ず生成ボタンへ表示されるので、知らないうちに課金されることはありません。
はい。VidneyでGPT Image 2.5を使って生成した画像は、商用プロジェクトに自由に使えます。広告、SNS投稿、クライアントワーク、商品ビジュアルなどに利用可能です。成果物の権利はあなたのもので、Vidneyは生成と保存を担うだけです。
いいえ。Vidneyで生成したGPT Image 2.5の画像は透かしのないクリーンな状態で書き出されます。Vidneyのロゴは入らないので、そのまま公開したりクライアントへ納品したりできます。
VidneyでGPT Image 2.5に最も近いのはMuse Image、Midjourney V8.1およびGrok Imagine Image 2.0です。どれも同じワークスペース内で共通のクレジット残高から使えるので、同じプロンプトをそれぞれのモデルで実行して、結果を並べて見比べられます。
いいえ。Vidneyがあなたに代わってGPT Image 2.5を実行します。管理すべきAPIキーも、別途用意するプロバイダーアカウントもありません。