Vidney

AI画像生成

画像から画像

参照画像を新しいAI画像へ変換。対応モデルを自由に選んで。

Vidney ワークベンチ

モデル 22 件

このモードは画像の参照のみ使えます。プロンプトでは Image 1、Image 2 と指定します。

ご自身が権利を持つファイルのみアップロードしてください。

0/2000
必要:9 クレジット

出力

サンプル

何が作れるか

ここで使えるモデルの実際のプロンプトと生成結果です。
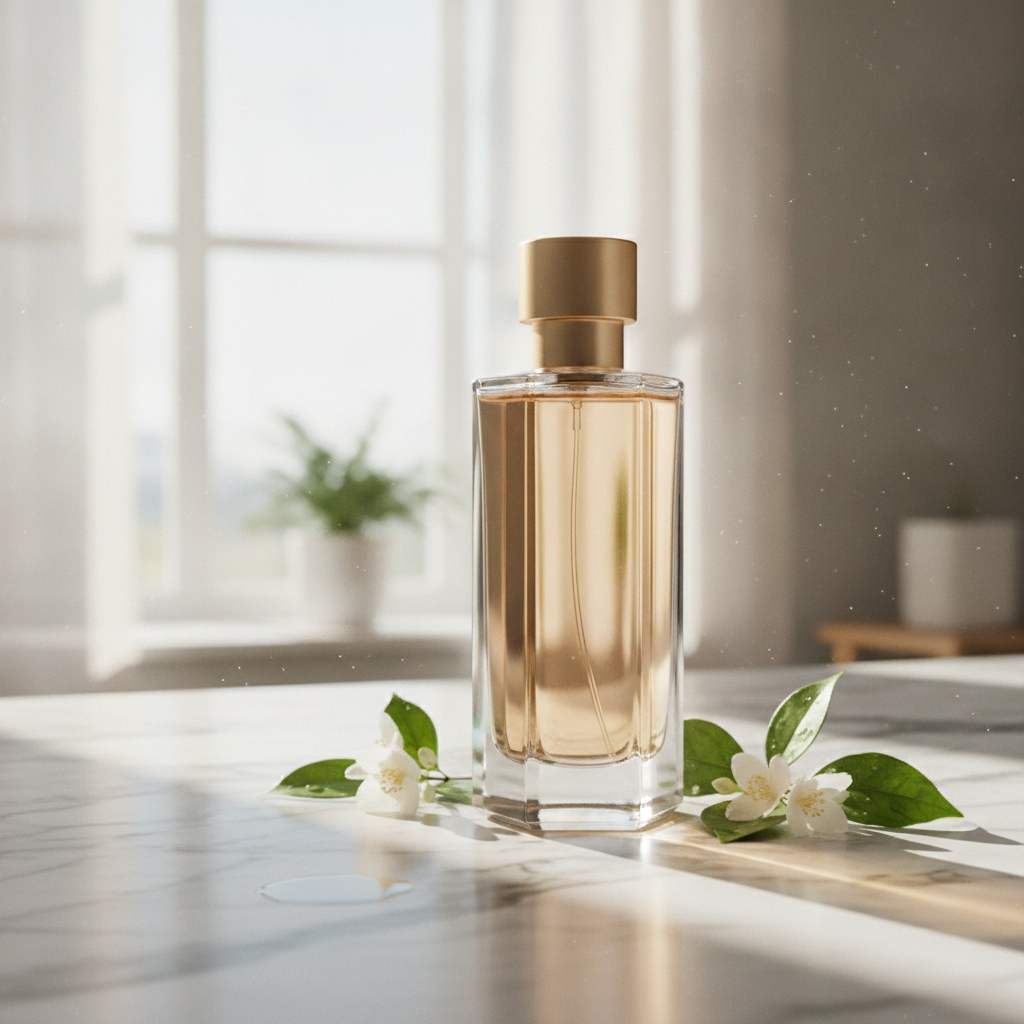
Multi-reference image fusion — A sleek perfume bottle from a studio shot placed on a sunlit marble countertop with soft morning light, composited as one natural scene
GeminiNano Banana

A sleek perfume bottle from a studio shot placed on a sunlit marble countertop with soft morning light, composited as one natural scene

A coffee label ready to print — E-commerce hero photograph of a stand-up kraft paper coffee bag with a matte cream label, square format, on a seamless warm beige background with a few roasted coffee beans scattered in front. The label text is large, crisp and spelled exactly: NORTH RIDGE in a bold black serif across the top, COFFEE ROASTERS in small spaced capitals under it, ETHIOPIA GUJI in medium black capitals in the middle, Washed · Light Roast on the next line, Peach · Jasmine · Honey on the line below, and 250 g at the bottom right of the label. Soft window light from the left, a gentle shadow, realistic paper texture and printing. No other text, no logos.
QwenQwen Image 3.0

E-commerce hero photograph of a stand-up kraft paper coffee bag with a matte cream label, square format, on a seamless warm beige background with a few roasted coffee beans scattered in front. The label text is large, crisp and spelled exactly: NORTH RIDGE in a bold black serif across the top, COFFEE ROASTERS in small spaced capitals under it, ETHIOPIA GUJI in medium black capitals in the middle, Washed · Light Roast on the next line, Peach · Jasmine · Honey on the line below, and 250 g at the bottom right of the label. Soft window light from the left, a gentle shadow, realistic paper texture and printing. No other text, no logos.

Texture at every scale — Photoreal interior of a small Japanese tea house at dawn during light rain, square format: tatami with visible weave, a low black lacquer table with a single ceramic cup and a thread of steam, shoji screens glowing with grey morning light, wet dark stepping stones and a bamboo ladle in the garden seen through the open engawa, a blank hanging scroll on the wall. Directional light from the screens on the left, soft shadows, fine wood grain on every post, precise texture at every scale from the cup to the garden. 50mm lens look, deep focus. No people, no text, no watermark.
QwenQwen Image 3.0 Pro

Photoreal interior of a small Japanese tea house at dawn during light rain, square format: tatami with visible weave, a low black lacquer table with a single ceramic cup and a thread of steam, shoji screens glowing with grey morning light, wet dark stepping stones and a bamboo ladle in the garden seen through the open engawa, a blank hanging scroll on the wall. Directional light from the screens on the left, soft shadows, fine wood grain on every post, precise texture at every scale from the cup to the garden. 50mm lens look, deep focus. No people, no text, no watermark.

画像から画像向けのモデル

20のモデルがこのタスクに対応しています。いずれかを開くと詳細な仕様を確認できます。

公開中

アリババの Wan 2.7 は画を作ってから動かします。静止画、編集、音つき動画を一つのモデルファミリーで。

1回の生成につき15〜126クレジット
公開中

小さくて速い Flux 3。テキストから1枚を作るのも、最大10枚の参考画像で1か所だけ変えるのも。

1回の生成につき3クレジット
公開中

Google の新しい Flash 画像モデル。文字は書いたとおりに戻り、次の編集でも顔はそのままです。

1回の生成につき3クレジット
公開中

同じページに2つの速さ、打ち込んだ文字はそのまま綴られて返ります。

1回の生成につき3〜5クレジット
公開中

Meta の画像モデルは、返す前に自分の下描きを自分で見直します。

1回の生成につき3クレジット
MidjourneyMidjourney V8.1
公開中

見慣れた Midjourney の絵に、ようやく読める見出しが付きました。

1回の生成につき18クレジット

Grok Imagine Image 2.0でAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき9〜15クレジット
公開中

仕上げ品質の生成と元画像に忠実な編集を担うQwen Image 3.0の高精細版です。

1回の生成につき15クレジット
公開中

1つのモデルで、文章から新しい画面を作り、一言の指示で既存の画面を直せます。

1回の生成につき12クレジット
公開中

Google の軽量版 Nano Banana。1K の画像と素早い編集を、大量の制作に。

1回の生成につき3クレジット
公開中

Nano Banana 2でAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき3クレジット
公開中

Nano Banana ProでAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき12クレジット
公開中

Seedream 5.0 LiteでAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき9クレジット
公開中

GPT Image 2.0でAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき3クレジット
MidjourneyMidjourney V7
公開中

Midjourney V7でAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき6クレジット
公開中

Nano BananaでAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき6クレジット
公開中

Seedream 4.5でAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき12クレジット
公開中

Flux KontextでAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき6〜12クレジット
公開中

GPT Image 1.5でAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき3クレジット
公開中

Seedream 4.0でAI画像を生成。テキストから画像と画像から画像を、Vidneyの1つのスタジオで。

1回の生成につき6〜9クレジット

Vidneyの画像から画像の使い方

Vidneyの画像から画像を使い、3ステップでAI画像を作成します。
Glowing panels with one model selected from severalStreams of light forming into an emerging imageA finished image materializing from a vortex of glowing light

よくある質問

Vidneyの画像から画像とは何ですか?

Vidneyの画像から画像を使えば、画像から画像から対応モデルでAI画像を1つのスタジオで作成できます。

画像から画像ではどのモデルが使えますか?

Wan 2.7、Flux 3 Klein、Nano Banana 2.1、GPT Image 2.5、Muse Image、Midjourney V8.1、Grok Imagine Image 2.0、Qwen Image 3.0 Pro、Qwen Image 3.0、Nano Banana 2 Lite、Nano Banana 2、Nano Banana Pro、Seedream 5.0 Lite、GPT Image 2.0、Midjourney V7、Nano Banana、Seedream 4.5、Flux Kontext、GPT Image 1.5およびSeedream 4.0が使えます。

画像から画像を使うのにAPIキーは必要ですか?

いいえ。Vidneyがプロバイダーへの接続と決済を引き受けます。管理すべきAPIキーも、用意すべきプロバイダーアカウントもありません。
Vidneyの画像から画像を試す