Vidney

Gerador de Imagem com IA

GPT Image 2.5

Duas velocidades na mesma página, e as palavras que você digitou voltam escritas certo.

Workbench Vidney

21 modelos
0/2000
Necessário: 3 créditos

Saída

Exemplo

GPT Image 2.5: Flare ou Sunburst?

O GPT Image 2.5 chega em duas versões, e esta página oferece as duas pelo mesmo preço. O que as separa é velocidade contra precisão.

A OpenAI entrega o GPT Image 2.5 como duas variantes atrás de uma única interface. O que a OpenAI destaca nesta geração, o texto entre aspas exatamente como foi digitado e as edições que só tocam o elemento nomeado, as duas variantes fazem igualmente bem, e um prompt carregado pode pedir uma segunda passada em qualquer das duas. Flare é a que a OpenAI aponta como padrão para a maioria das aplicações: gera uma imagem em cerca de metade do tempo que o GPT Image 2 levava. Sunburst coloca a precisão em primeiro lugar: preserva detalhes complexos com mais fidelidade e demora mais para concluir. Na Vidney, as duas aceitam os mesmos prompts, até quatro imagens de referência, as mesmas cinco proporções e os mesmos tamanhos 1K, 2K e 4K, e custam os mesmos créditos em cada tamanho. A escolha nunca mexe no seu saldo, só no relógio e no resultado.

A rápida

Flare

A maior parte do trabalho deveria começar com Flare. O que Flare acrescenta é velocidade: volta rápido o bastante para iterar um layout em vez de esperar por ele, e nos nossos próprios testes uma imagem 4K terminou em 47 segundos. O letreiro limpo e as edições contidas pelas quais esta geração é conhecida estão igualmente aqui, só que mais rápido.

Escolha para

  • Primeiros rascunhos e exploração de direções
  • Séries de variações sobre um mesmo briefing
  • Telas e cartazes que vão passar por várias revisões

A precisa

Sunburst

Sunburst é a mais precisa das duas para editar, feita para a imagem em que nada pode sair do lugar. Nomeie um elemento e o resto da imagem deve ficar onde está; em 4K, detalhes finos como a letra miúda continuam legíveis ao dar zoom. Esse cuidado custa tempo: a mesma imagem 4K que Flare concluiu em 47 segundos levou 64 segundos em Sunburst.

Escolha para

  • Edições em que só a parte nomeada pode mudar
  • Uma linha de produtos que precisa bater com uma foto aprovada
  • Trabalhos em 4K que serão vistos em tamanho grande ou impressos

Comece em Flare e mude para Sunburst assim que uma edição precisar se manter ou um detalhe tiver de resistir a um olhar de perto. As duas estão no menu de modelos do gerador acima, como GPT Image 2.5 Flare e GPT Image 2.5 Sunburst, com os mesmos créditos.

O que o GPT Image 2.5 faz bem

01

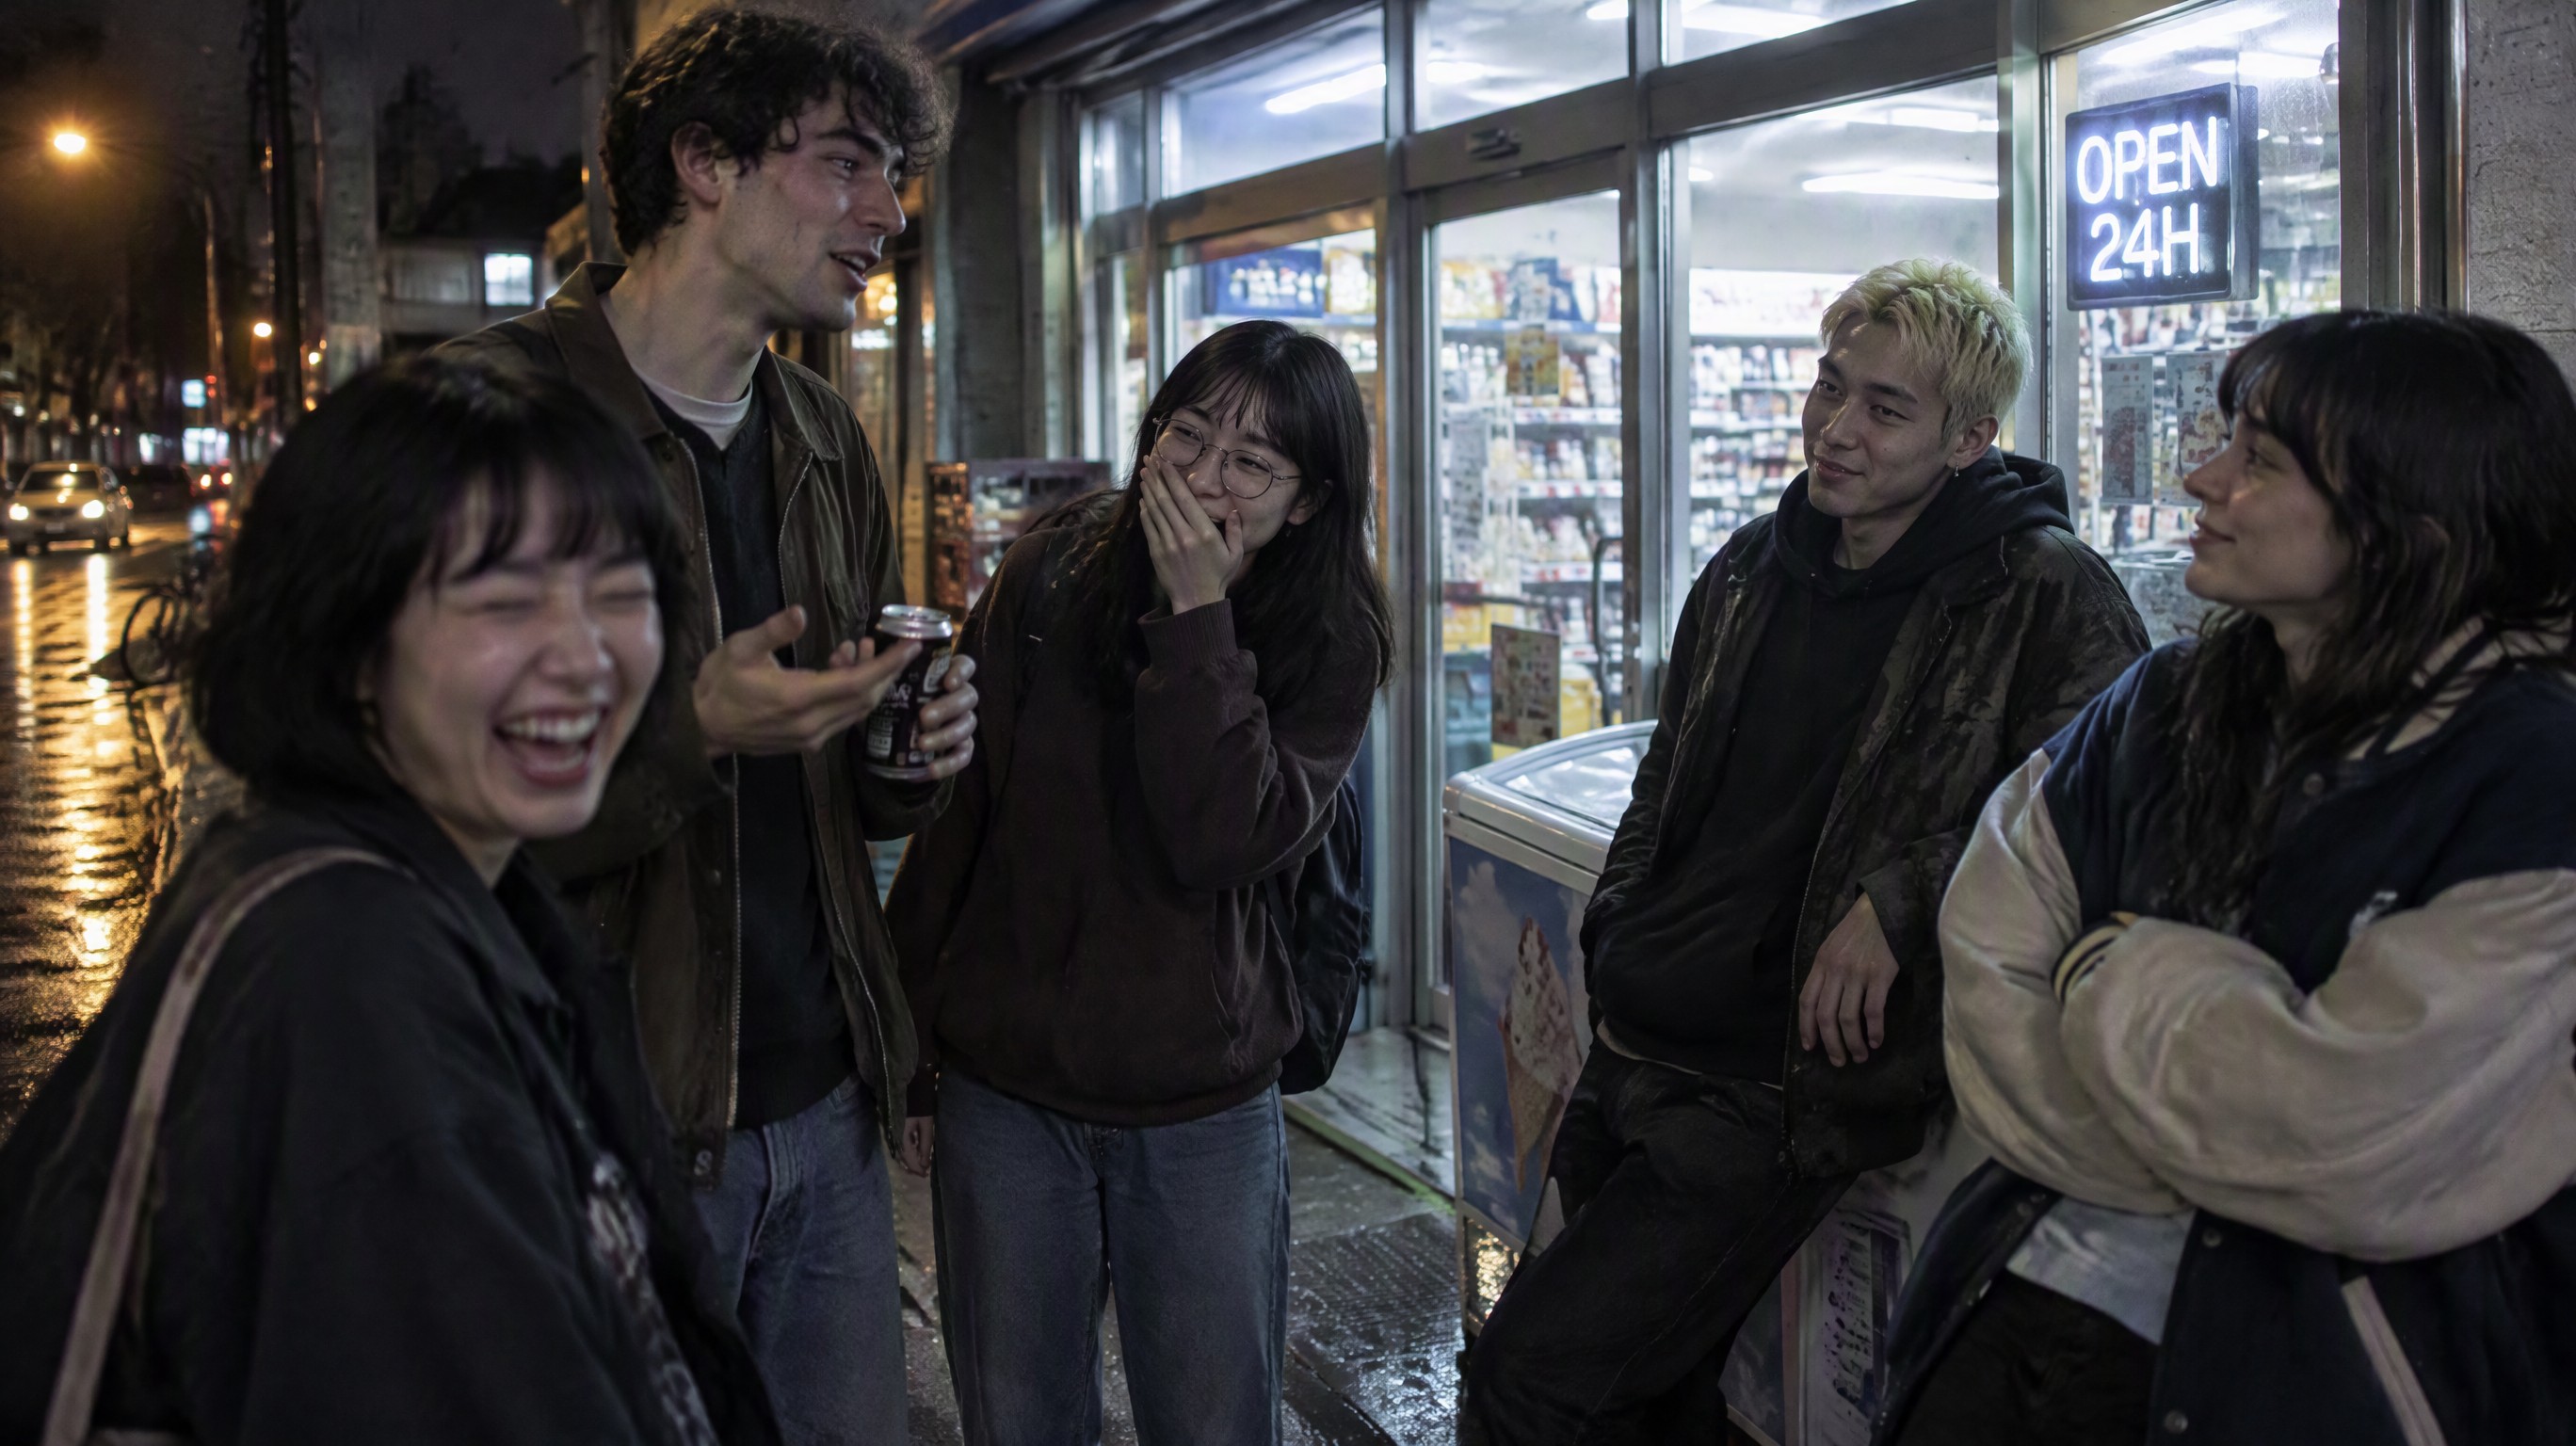
Cinco rostos, nenhum igual

Cinco amigos diante de uma loja de conveniência depois da meia-noite, iluminados só pela vitrine e por um poste. Cada rosto é uma pessoa diferente, um riso diferente, um olhar diferente, pele real sob a luz dura das lâmpadas, e ninguém posa para a câmera.

Cinco rostos, nenhum igual: Photorealistic candid photograph of five friends in their early twenties hanging out on the sidewalk in front of a small 24-hour convenience store late at night, laughing and talking in the middle of a story. Each face is clearly different and clearly lit: a young woman with a short black bob laughing with her eyes squeezed shut, a tall young man mid-sentence gesturing with a canned coffee, a young woman in round glasses covering her grin with one hand, a young man with bleached hair leaning against the ice-cream freezer by the door with a lopsided smirk, and a young woman in an oversized varsity jacket looking sideways at her friend with a fond half-smile. Natural mixed lighting only: cool white fluorescent light spilling from the store windows onto the pavement, one warm streetlamp far to the left, soft reflections on slightly damp asphalt. Shot on a 35mm lens at f/2 from a few steps away, the friend nearest the camera slightly out of focus, real skin texture with pores and a little shine, no beauty retouching, nobody posing for the camera. The storefront is generic and unbranded; the only readable text is a small glowing sign reading 'OPEN 24H'. Documentary photography, muted colours, faint film grain.
Prompt

Photorealistic candid photograph of five friends in their early twenties hanging out on the sidewalk in front of a small 24-hour convenience store late at night, laughing and talking in the middle of a story. Each face is clearly different and clearly lit: a young woman with a short black bob laughing with her eyes squeezed shut, a tall young man mid-sentence gesturing with a canned coffee, a young woman in round glasses covering her grin with one hand, a young man with bleached hair leaning against the ice-cream freezer by the door with a lopsided smirk, and a young woman in an oversized varsity jacket looking sideways at her friend with a fond half-smile. Natural mixed lighting only: cool white fluorescent light spilling from the store windows onto the pavement, one warm streetlamp far to the left, soft reflections on slightly damp asphalt. Shot on a 35mm lens at f/2 from a few steps away, the friend nearest the camera slightly out of focus, real skin texture with pores and a little shine, no beauty retouching, nobody posing for the camera. The storefront is generic and unbranded; the only readable text is a small glowing sign reading 'OPEN 24H'. Documentary photography, muted colours, faint film grain.

02

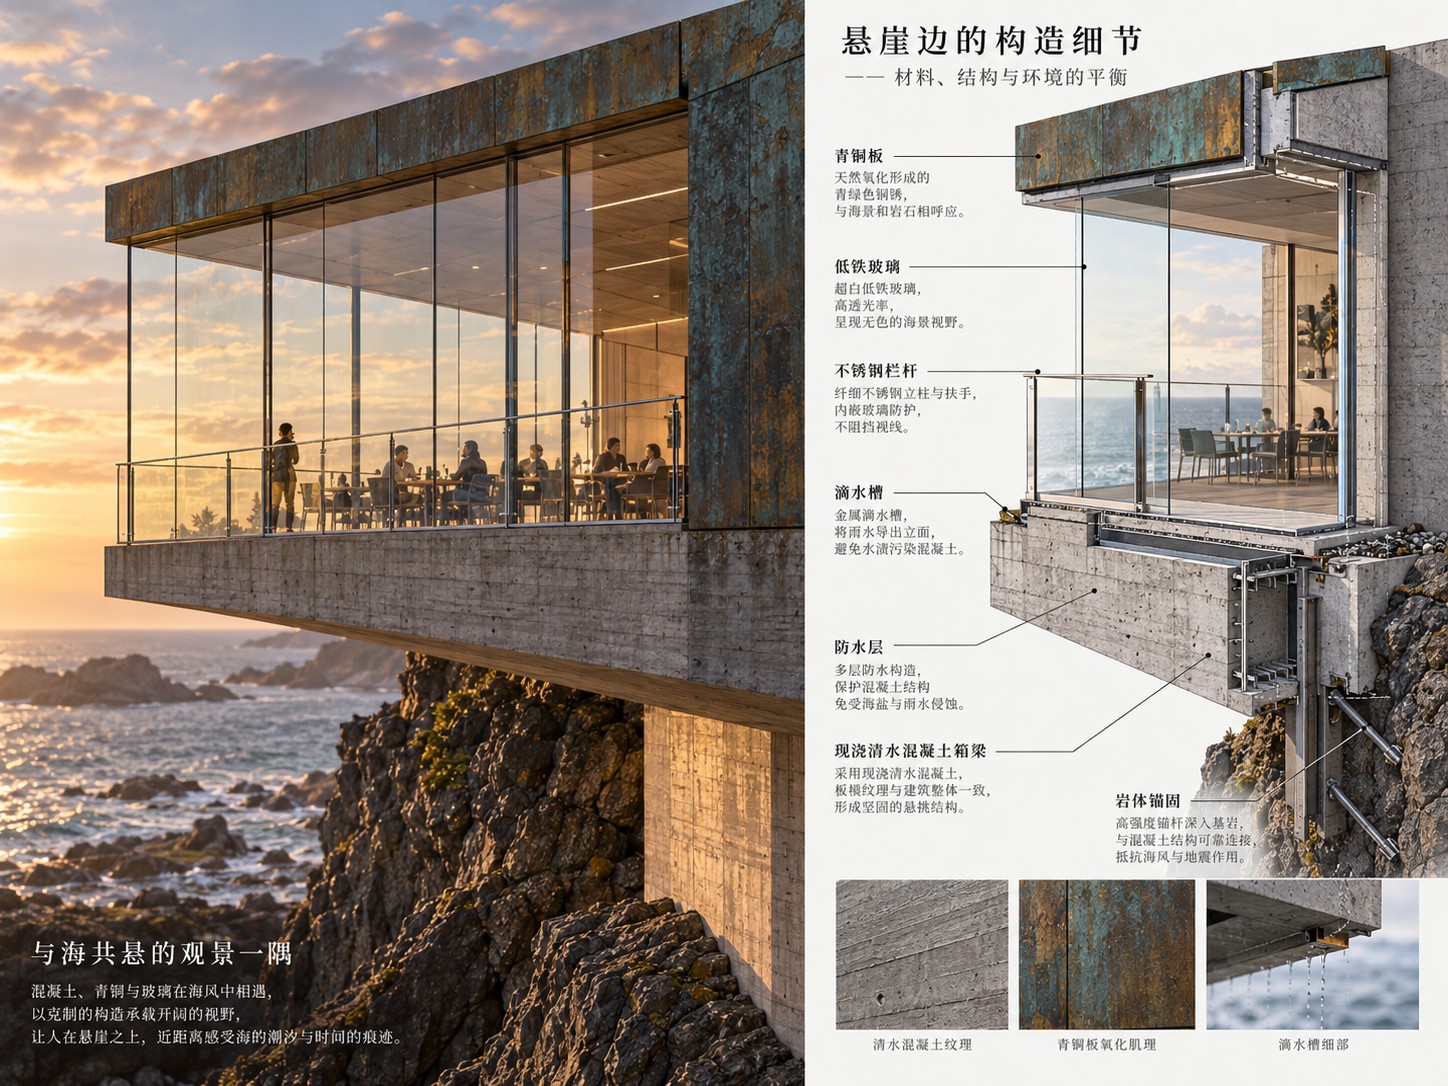
Uma foto e seu desenho construtivo, lado a lado

À esquerda um restaurante envidraçado em balanço sobre o mar, à direita seu detalhe em corte com sete anotações em chinês, do revestimento de bronze patinado até as ancoragens na rocha. Cada caractere das anotações continua legível, e o desenho bate com a foto peça por peça.

Uma foto e seu desenho construtivo, lado a lado: A two-part editorial spread on one 4:3 canvas. Left half: a photorealistic architectural photograph at golden hour of a small glass-walled restaurant cantilevered from a dark basalt cliff over the sea, the box clad in green-patinated bronze panels and carried on a raw board-marked concrete beam, floor to ceiling low-iron glazing with a thin stainless steel guardrail, diners at tables inside lit by the low sun, waves breaking on the rocks below, soft clouds. Right half on warm off-white paper: an annotated construction detail of the same cantilever drawn as a clean cut-away render with hairline leader lines, titled '悬崖边的构造细节' with the subtitle '材料、结构与环境的平衡', and seven callouts in Chinese reading '青铜板', '低铁玻璃', '不锈钢栏杆', '滴水槽', '防水层', '现浇清水混凝土箱梁', '岩体锚固', each with two or three short lines of explanation in small grey type; along the bottom three small material swatches captioned '清水混凝土纹理', '青铜板氧化肌理', '滴水槽细部'. Bottom left of the photograph a white caption block reading '与海共悬的观景一隅' with three short lines of copy beneath. Editorial typography, generous margins, every character rendered clearly, no other text.
Prompt

A two-part editorial spread on one 4:3 canvas. Left half: a photorealistic architectural photograph at golden hour of a small glass-walled restaurant cantilevered from a dark basalt cliff over the sea, the box clad in green-patinated bronze panels and carried on a raw board-marked concrete beam, floor to ceiling low-iron glazing with a thin stainless steel guardrail, diners at tables inside lit by the low sun, waves breaking on the rocks below, soft clouds. Right half on warm off-white paper: an annotated construction detail of the same cantilever drawn as a clean cut-away render with hairline leader lines, titled '悬崖边的构造细节' with the subtitle '材料、结构与环境的平衡', and seven callouts in Chinese reading '青铜板', '低铁玻璃', '不锈钢栏杆', '滴水槽', '防水层', '现浇清水混凝土箱梁', '岩体锚固', each with two or three short lines of explanation in small grey type; along the bottom three small material swatches captioned '清水混凝土纹理', '青铜板氧化肌理', '滴水槽细部'. Bottom left of the photograph a white caption block reading '与海共悬的观景一隅' with three short lines of copy beneath. Editorial typography, generous margins, every character rendered clearly, no other text.

03

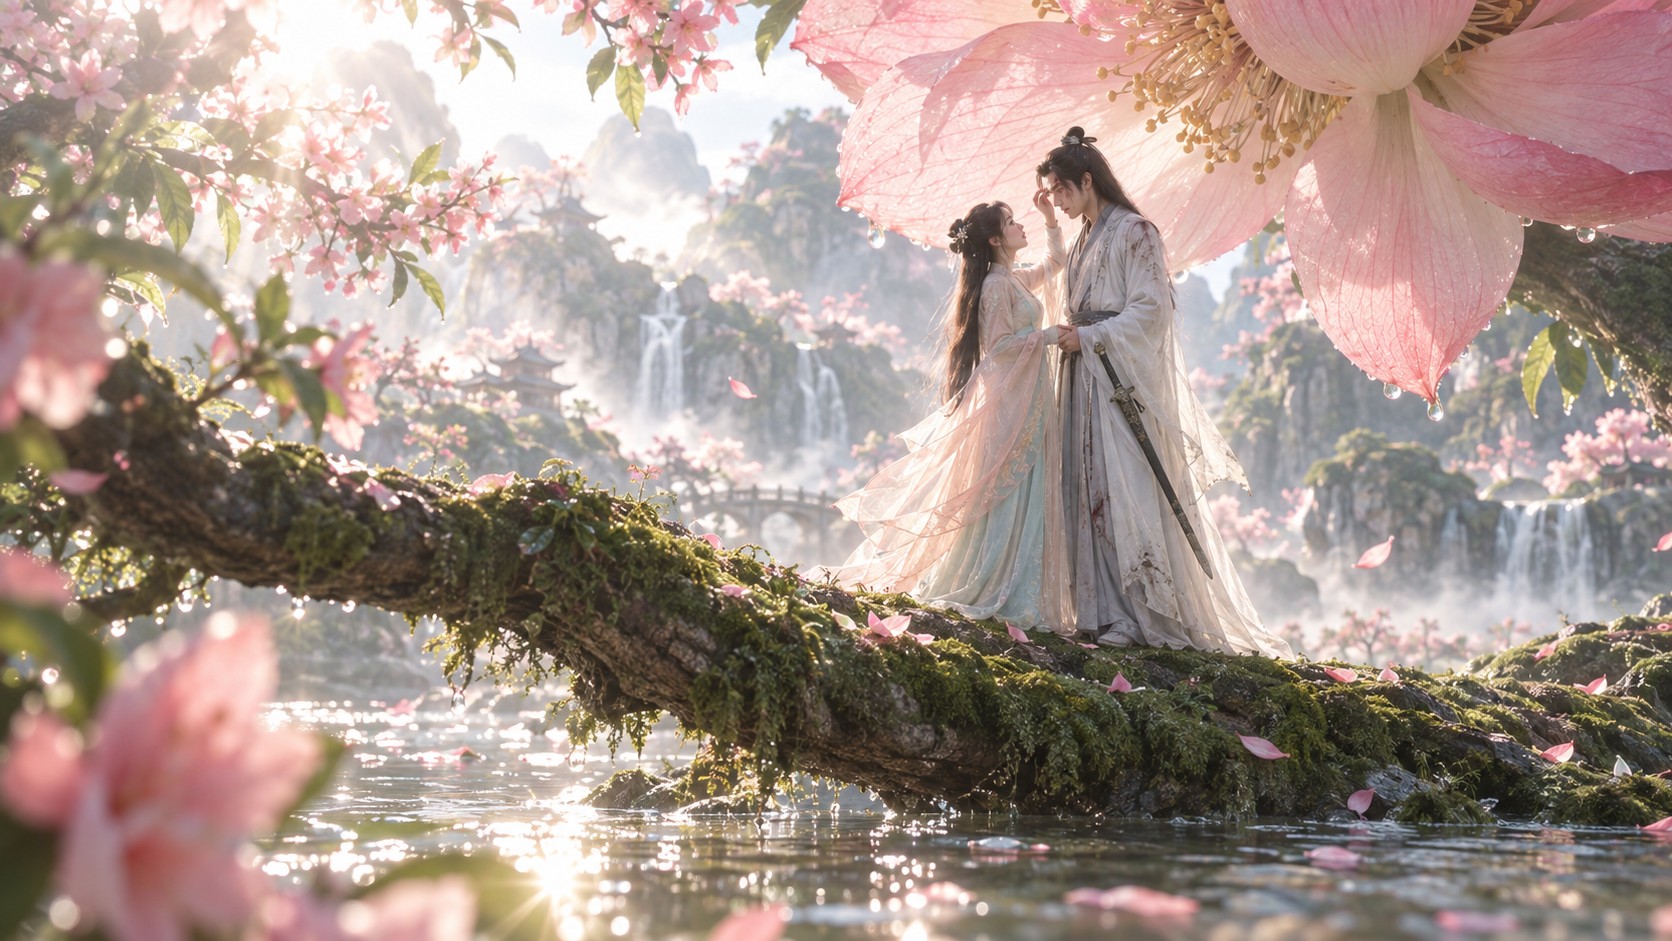
Uma flor do tamanho de uma vela de barco

Duas figuras em hanfu sobre um tronco musgoso que cruza um rio, sob uma pétala rosa translúcida com orvalho na borda, picos cársticos e cachoeiras se dissolvendo na névoa ao fundo. Contraluz, névoa e musgo molhado se leem como uma só luz, e as dobras do tecido ficam nítidas onde o foco cai.

Uma flor do tamanho de uma vela de barco: Cinematic wide shot in a Chinese xianxia fantasy world, photoreal CG. A young woman in flowing pale pink and mint layered hanfu with long black hair and a jade hairpin stands on a moss-covered fallen tree trunk that bridges a shallow river, gently touching the cheek of a young swordsman in white and grey robes with a sword at his hip; both in profile, close together. Above them a giant translucent pink blossom leans over the trunk, its petals the size of sails with dewdrops on the edges and golden stamens. Behind them misty karst peaks with waterfalls, a stone arch bridge and distant pavilion roofs, peach trees in full bloom, petals drifting down onto the water. Backlit morning sun, volumetric haze, soft lens bloom, sparkle and ripples on the water in the foreground, shallow depth of field on the blossoms nearest the camera. Ethereal and romantic, with detailed fabric and wet moss textures.
Prompt

Cinematic wide shot in a Chinese xianxia fantasy world, photoreal CG. A young woman in flowing pale pink and mint layered hanfu with long black hair and a jade hairpin stands on a moss-covered fallen tree trunk that bridges a shallow river, gently touching the cheek of a young swordsman in white and grey robes with a sword at his hip; both in profile, close together. Above them a giant translucent pink blossom leans over the trunk, its petals the size of sails with dewdrops on the edges and golden stamens. Behind them misty karst peaks with waterfalls, a stone arch bridge and distant pavilion roofs, peach trees in full bloom, petals drifting down onto the water. Backlit morning sun, volumetric haze, soft lens bloom, sparkle and ripples on the water in the foreground, shallow depth of field on the blossoms nearest the camera. Ethereal and romantic, with detailed fabric and wet moss textures.

04

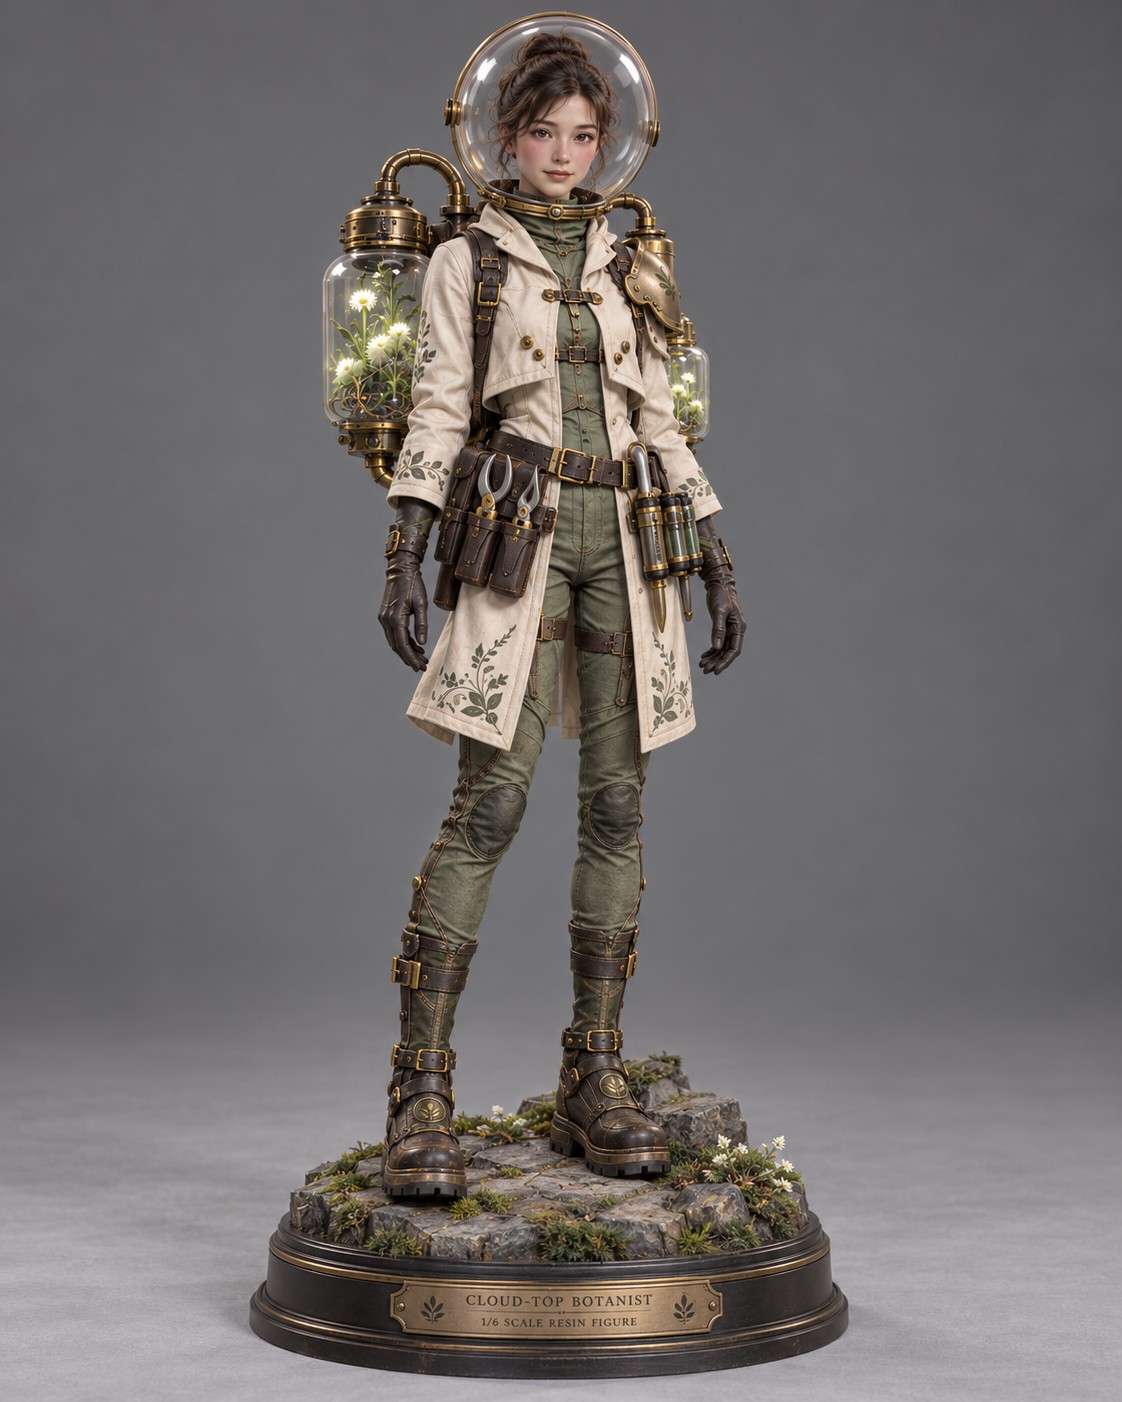
Um colecionável que dá vontade de pegar

Uma figura em escala 1/6 de uma botânica exploradora sobre a base, capacete de vidro, tanques terrário de latão e casaco de lona bordado, fotografada como um anúncio de produto. Vidro, latão, couro e tecido mantêm cada um seu acabamento, e a placa traz “CLOUD-TOP BOTANIST” por inteiro.

Um colecionável que dá vontade de pegar: Studio product photograph of a 1/6 scale resin collectible figure: a young woman botanist explorer standing on a rocky mossy base with tiny white wildflowers, wearing a glass dome helmet with brass fittings, a cream canvas coat with green leaf embroidery over an olive utility suit, a leather tool belt holding pruning shears and glass vials, dark leather gloves and tall buckled boots. On her back two brass and glass terrarium canisters with glowing white daisies inside. The figure stands on a round black plinth with a brass plaque reading 'CLOUD-TOP BOTANIST' and a smaller line '1/6 SCALE RESIN FIGURE'. Plain grey seamless backdrop, soft even studio light with a gentle shadow under the base, sharp focus from helmet to boots, visible material finishes: matte fabric, polished brass, clear glass, worn leather. Vertical 3:4 framing.
Prompt

Studio product photograph of a 1/6 scale resin collectible figure: a young woman botanist explorer standing on a rocky mossy base with tiny white wildflowers, wearing a glass dome helmet with brass fittings, a cream canvas coat with green leaf embroidery over an olive utility suit, a leather tool belt holding pruning shears and glass vials, dark leather gloves and tall buckled boots. On her back two brass and glass terrarium canisters with glowing white daisies inside. The figure stands on a round black plinth with a brass plaque reading 'CLOUD-TOP BOTANIST' and a smaller line '1/6 SCALE RESIN FIGURE'. Plain grey seamless backdrop, soft even studio light with a gentle shadow under the base, sharp focus from helmet to boots, visible material finishes: matte fabric, polished brass, clear glass, worn leather. Vertical 3:4 framing.

O que criar com o GPT Image 2.5

Fotos de grupo em que cada rosto é uma pessoa

Imagens de campanha, páginas de equipe e posts sociais com cinco ou seis pessoas no quadro, cada uma com seus traços e sua expressão, iluminadas só pela luz que a cena realmente tem.

Layouts anotados em mais de um idioma

Fichas de produto, detalhes construtivos e infográficos que combinam uma imagem fotorrealista com anotações rotuladas, em que a letra miúda em chinês e em inglês continua legível.

Cenas e produtos com cara de acabado

Stills cinematográficos para uma apresentação, ou colecionáveis e embalagens fotografados como um anúncio de produto, em que vidro, metal, tecido e pele mantêm cada um seu acabamento.

Para quem é o GPT Image 2.5

O GPT Image 2.5 é o modelo de imagem da OpenAI lançado em setembro de 2026, e a Vidney reúne as duas variantes na mesma página: o Flare, o mais rápido dos dois e a escolha padrão da própria OpenAI para quase todo trabalho, e o Sunburst, o mais lento, feito para edições precisas. Os dois rodam texto para imagem e imagem para imagem, aceitam até quatro imagens de referência e cobrem 1:1, 4:3, 3:4, 16:9 e 9:16 em 1K, 2K ou 4K, com o 4K equivalendo a cerca de 8,3 milhões de pixels. A qualidade fica fixa aqui no degrau intermediário, e fundo transparente, edição com máscara e os degraus de qualidade mais altos seguem fechados por enquanto. Escolha-o quando as palavras dentro da imagem precisarem sair certas de primeira.

Como criar imagem com o GPT Image 2.5

Crie imagem com IA usando o GPT Image 2.5 na Vidney em três passos.

Glowing panels with one model selected from severalStreams of light forming into an emerging imageA finished image materializing from a vortex of glowing light

GPT Image 2.5 vs Muse Image vs Midjourney V8.1 vs Grok Imagine Image 2.0

Especificações lado a lado com modelos semelhantes, todos na Vidney.

GPT Image 2.5Muse ImageMidjourney V8.1Grok Imagine Image 2.0
Modos de tarefaTexto para Imagem · Imagem para ImagemTexto para Imagem · Imagem para ImagemTexto para Imagem · Imagem para ImagemTexto para Imagem · Imagem para Imagem
Resolução1K · 2K · 4K1K · 2K
Custo3–5 créditos por geração3 créditos por geração18 créditos por geração9–15 créditos por geração

Modelos relacionados

Mais modelos de imagem com IA que você pode rodar na Vidney.

No ar

Crie imagem com IA usando o GPT Image 2.0: texto para imagem e imagem para imagem, tudo em um só espaço na Vidney.

3 créditos por geração
No ar

Crie imagem com IA usando o GPT Image 1.5: texto para imagem e imagem para imagem, tudo em um só espaço na Vidney.

3 créditos por geração
No ar

O modelo de imagem da Meta revisa o próprio rascunho antes de devolver a imagem.

3 créditos por geração
No ar

Crie imagem com IA usando o Nano Banana 2: texto para imagem e imagem para imagem, tudo em um só espaço na Vidney.

3 créditos por geração
MidjourneyMidjourney V7
No ar

Crie imagem com IA usando o Midjourney V7: texto para imagem e imagem para imagem, tudo em um só espaço na Vidney.

6 créditos por geração
No ar

Crie imagem com IA usando o Nano Banana: texto para imagem e imagem para imagem, tudo em um só espaço na Vidney.

6 créditos por geração

Perguntas frequentes

O que é o GPT Image 2.5?

O GPT Image 2.5 é um modelo de imagem com IA que você roda na Vidney. Ele oferece texto para imagem e imagem para imagem em um só espaço.

Quanto custa cada geração do GPT Image 2.5?

O GPT Image 2.5 custa 3–5 créditos por geração. O valor exato em créditos aparece no botão de gerar antes de você rodar.

Quais proporções o GPT Image 2.5 suporta?

O GPT Image 2.5 suporta as seguintes proporções: 1:1, 4:3, 3:4, 16:9, 9:16.

O GPT Image 2.5 é grátis?

Dá para começar a usar o GPT Image 2.5 de graça na Vidney com os créditos que você ganha ao se cadastrar, sem precisar de cartão para testar. Depois disso, cada geração custa 3–5 créditos por geração, e o valor exato sempre aparece no botão de gerar antes de você gastar qualquer crédito.

Posso usar comercialmente os imagems criados com o GPT Image 2.5?

Sim. Os imagems que você cria com o GPT Image 2.5 na Vidney são seus para usar em projetos comerciais: anúncios, posts em redes sociais, trabalho para clientes e conteúdo de produto. O resultado é seu; a Vidney só cuida da geração e do armazenamento.

O GPT Image 2.5 coloca marca d'água?

Não. Os imagems gerados com o GPT Image 2.5 na Vidney saem limpos, sem marca d'água da Vidney, prontos para publicar ou entregar a um cliente do jeito que estão.

Quais são as melhores alternativas ao GPT Image 2.5?

As alternativas ao GPT Image 2.5 mais próximas no Vidney são Muse Image, Midjourney V8.1 e Grok Imagine Image 2.0. Todas rodam no mesmo espaço de trabalho, com um único saldo de créditos, então você pode rodar o mesmo prompt em cada uma e comparar os resultados lado a lado.

Preciso de chave de API ou conta de provedor para usar o GPT Image 2.5?

Não. A Vidney roda o GPT Image 2.5 por você; não há chaves de API para gerenciar nem conta de provedor separada para configurar.

Crie com o GPT Image 2.5 agora