KI-Bildgenerator

GPT Image 2.5

Zwei Geschwindigkeiten auf einer Seite, und die getippten Wörter kommen richtig geschrieben zurück.

Vidney Workbench

21 Modelle
0/2000
Erforderlich: 3 Credits

Ausgabe

Beispiel

GPT Image 2.5: Flare oder Sunburst?

GPT Image 2.5 gibt es in zwei Versionen, und diese Seite bietet beide zum gleichen Preis. Der Unterschied liegt zwischen Tempo und Präzision.

OpenAI liefert GPT Image 2.5 als zwei Varianten hinter einer gemeinsamen Schnittstelle. Was OpenAI für diese Generation anführt, Text in Anführungszeichen genau wie eingegeben und Änderungen nur am benannten Element, können beide Varianten gleichermaßen; ein überladener Prompt braucht bei beiden mitunter einen zweiten Durchgang. Flare ist die Variante, die OpenAI für die meisten Anwendungen als Standard nennt, und sie rendert in etwa der halben Zeit, die GPT Image 2 brauchte. Sunburst stellt Präzision voran: Es bewahrt komplexe Details treuer und braucht länger bis zum fertigen Bild. Auf Vidney nehmen beide dieselben Prompts, bis zu vier Referenzbilder, dieselben fünf Seitenverhältnisse und dieselben Größen 1K, 2K und 4K an, und sie kosten in jeder Größe dieselben Credits. Die Wahl ändert nichts am Guthaben, nur an Wartezeit und Ergebnis.

Die schnelle Variante

Flare

Die meiste Arbeit sollte mit Flare beginnen. Was Flare hinzufügt, ist Tempo: Es kommt schnell genug zurück, um ein Layout zu iterieren, statt darauf zu warten, und in unseren eigenen Tests war ein 4K-Bild nach 47 Sekunden fertig. Die saubere Schrift und die eng gefassten Änderungen, für die diese Generation bekannt ist, sind hier ebenso vorhanden, nur schneller.

Die richtige Wahl für

  • Erste Entwürfe und das Ausloten von Richtungen
  • Serien von Varianten zu einem Briefing
  • Screens und Plakate, die mehrere Überarbeitungsrunden durchlaufen

Die präzise Variante

Sunburst

Sunburst ist die präzisere der beiden Varianten, gedacht für das Bild, in dem nichts verrutschen darf. Wird ein Element benannt, soll der Rest des Bildes bleiben, wo er ist, und in 4K bleiben feine Details wie kleine Schrift beim Hineinzoomen lesbar. Diese Sorgfalt kostet Zeit: Dasselbe 4K-Bild, das Flare in 47 Sekunden fertigstellte, brauchte bei Sunburst 64 Sekunden.

Die richtige Wahl für

  • Bearbeitungen, bei denen sich nur der benannte Teil ändern darf
  • Eine Produktlinie, die zu einer freigegebenen Aufnahme passen muss
  • 4K-Arbeiten, die groß gezeigt oder gedruckt werden

Der Einstieg gehört Flare, der Wechsel zu Sunburst kommt, sobald eine Bearbeitung halten oder ein Detail den nahen Blick bestehen muss. Beide stehen im Modellmenü des Generators oben als GPT Image 2.5 Flare und GPT Image 2.5 Sunburst, zu denselben Credits.

Was GPT Image 2.5 gut kann

01

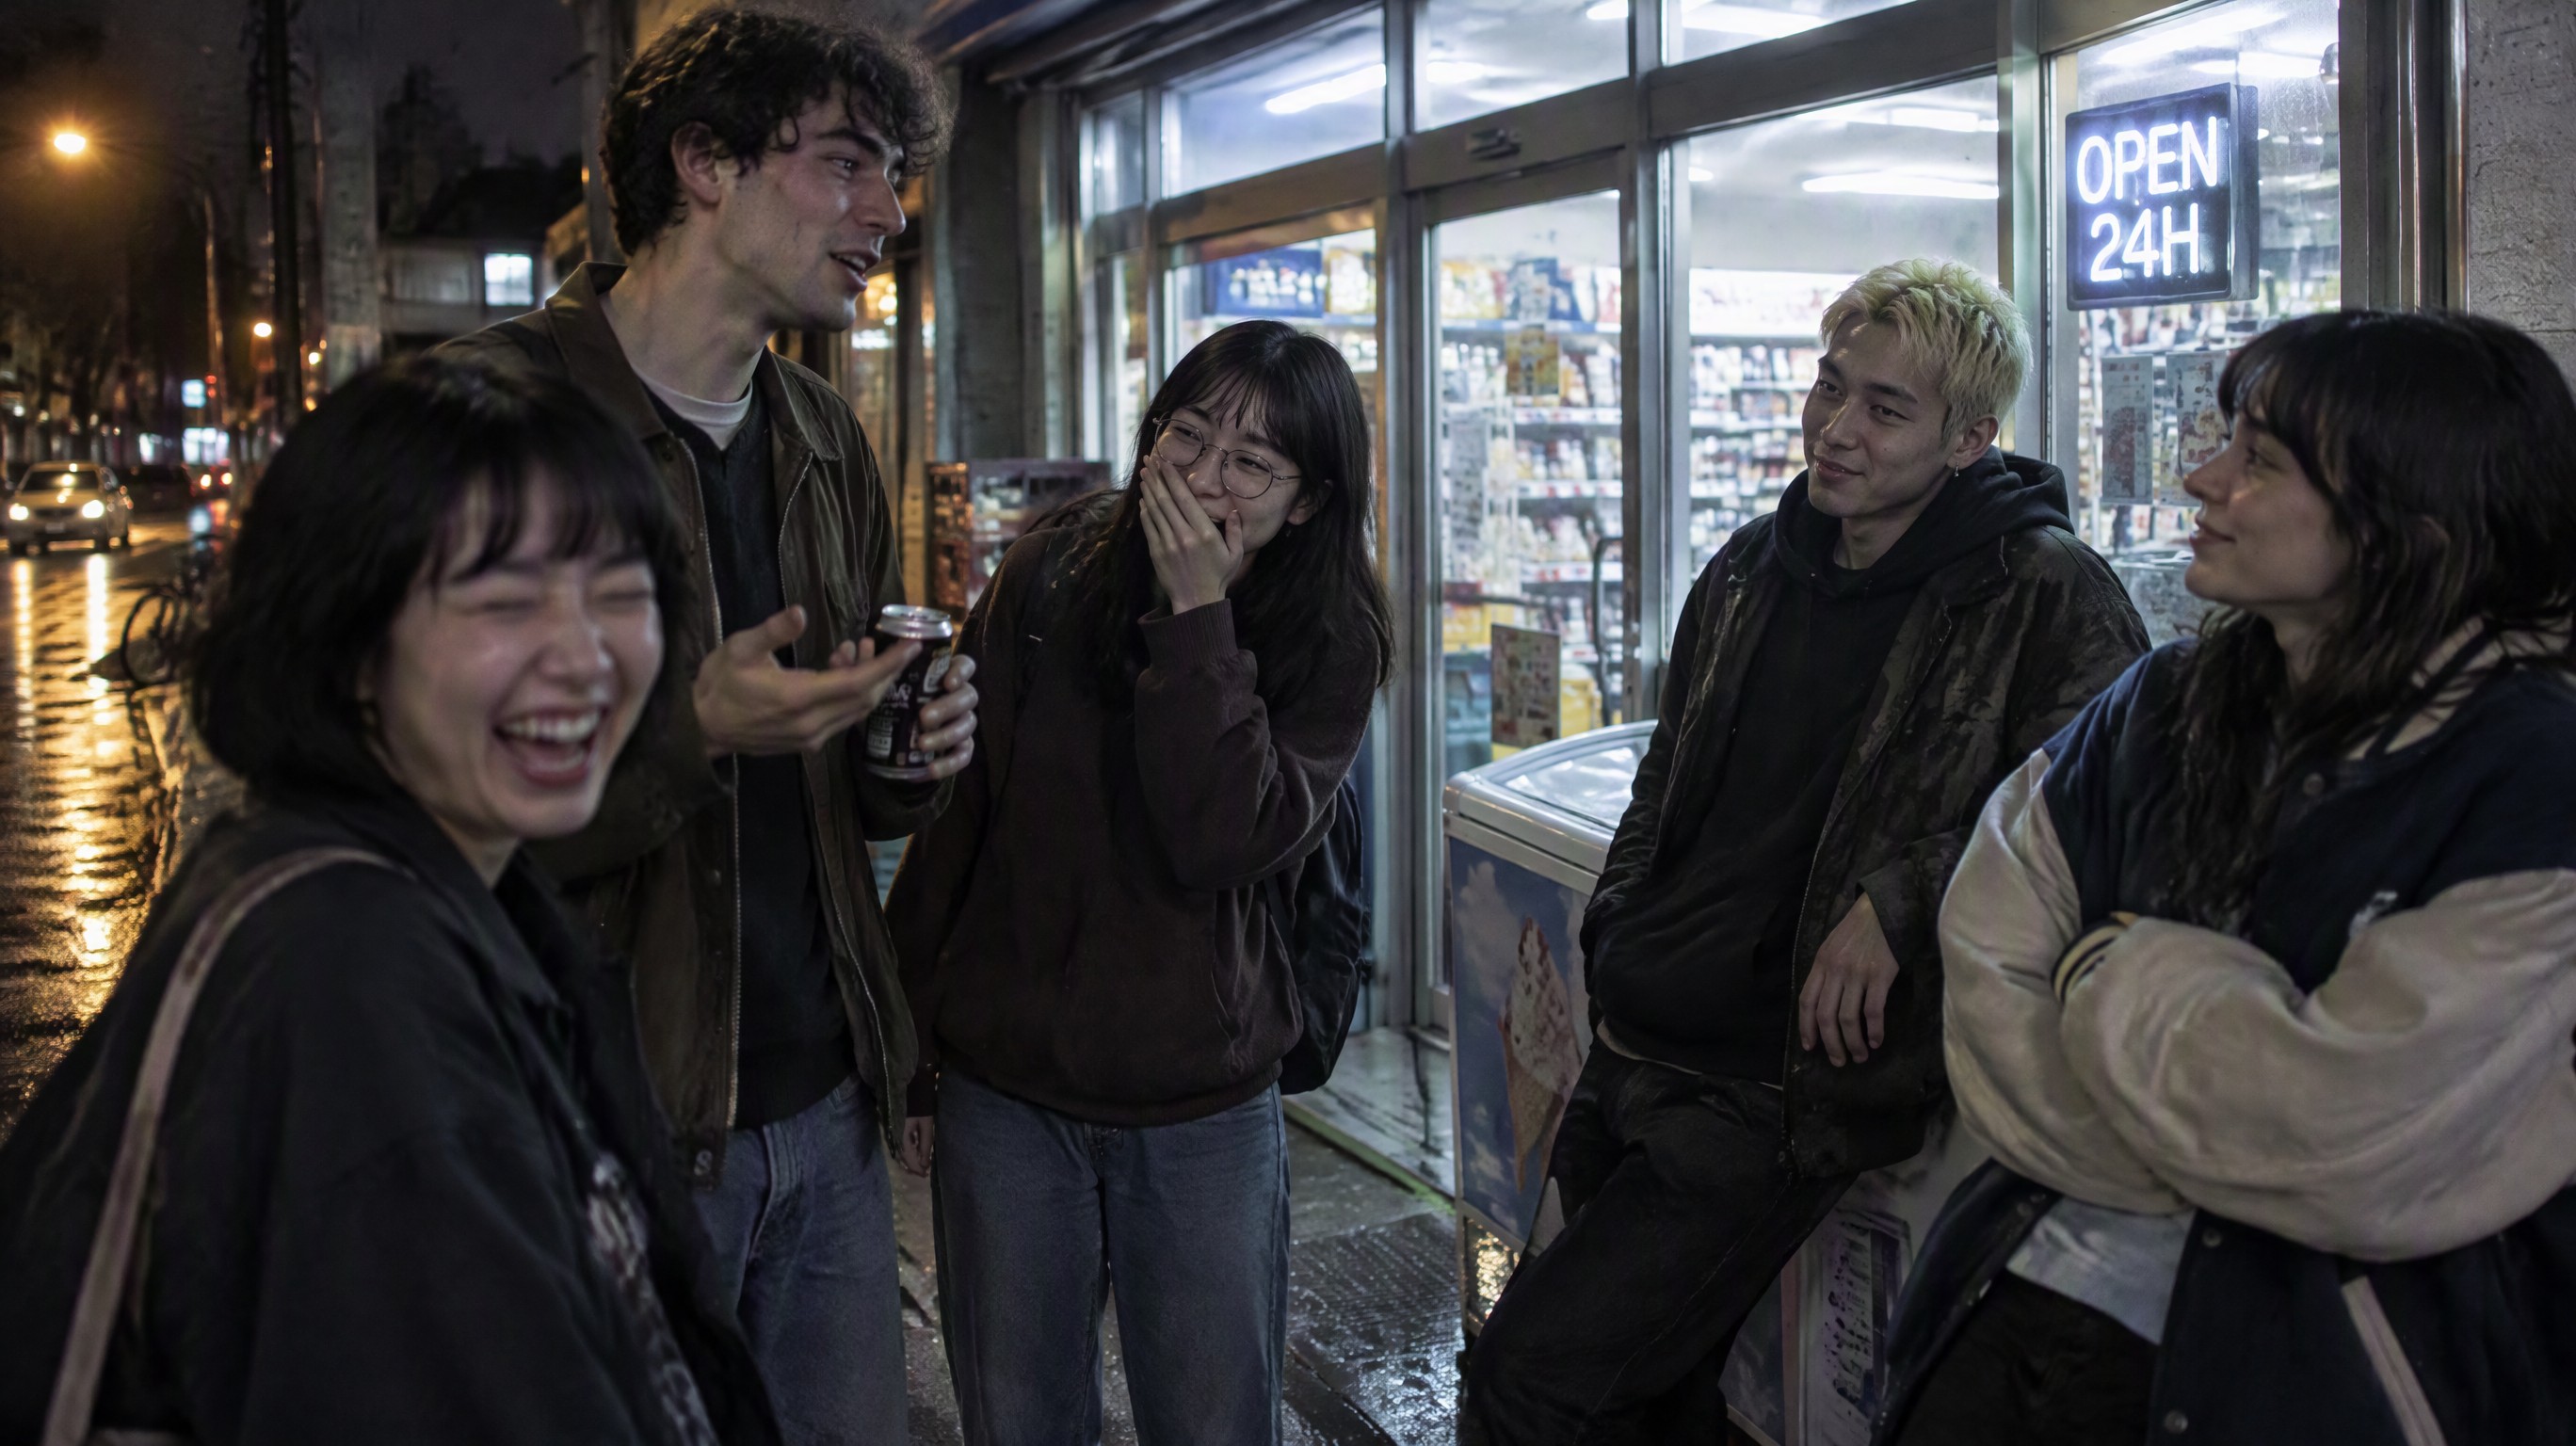
Fünf Gesichter, keines wie das andere

Fünf Freunde nach Mitternacht vor einem rund um die Uhr geöffneten Kiosk, beleuchtet nur vom Schaufenster und einer Straßenlaterne. Jedes Gesicht ist eine eigene Person, ein anderes Lachen, andere Augen, echte Haut unter hartem Neonlicht, und niemand posiert für die Kamera.

Fünf Gesichter, keines wie das andere: Photorealistic candid photograph of five friends in their early twenties hanging out on the sidewalk in front of a small 24-hour convenience store late at night, laughing and talking in the middle of a story. Each face is clearly different and clearly lit: a young woman with a short black bob laughing with her eyes squeezed shut, a tall young man mid-sentence gesturing with a canned coffee, a young woman in round glasses covering her grin with one hand, a young man with bleached hair leaning against the ice-cream freezer by the door with a lopsided smirk, and a young woman in an oversized varsity jacket looking sideways at her friend with a fond half-smile. Natural mixed lighting only: cool white fluorescent light spilling from the store windows onto the pavement, one warm streetlamp far to the left, soft reflections on slightly damp asphalt. Shot on a 35mm lens at f/2 from a few steps away, the friend nearest the camera slightly out of focus, real skin texture with pores and a little shine, no beauty retouching, nobody posing for the camera. The storefront is generic and unbranded; the only readable text is a small glowing sign reading 'OPEN 24H'. Documentary photography, muted colours, faint film grain.
Prompt

Photorealistic candid photograph of five friends in their early twenties hanging out on the sidewalk in front of a small 24-hour convenience store late at night, laughing and talking in the middle of a story. Each face is clearly different and clearly lit: a young woman with a short black bob laughing with her eyes squeezed shut, a tall young man mid-sentence gesturing with a canned coffee, a young woman in round glasses covering her grin with one hand, a young man with bleached hair leaning against the ice-cream freezer by the door with a lopsided smirk, and a young woman in an oversized varsity jacket looking sideways at her friend with a fond half-smile. Natural mixed lighting only: cool white fluorescent light spilling from the store windows onto the pavement, one warm streetlamp far to the left, soft reflections on slightly damp asphalt. Shot on a 35mm lens at f/2 from a few steps away, the friend nearest the camera slightly out of focus, real skin texture with pores and a little shine, no beauty retouching, nobody posing for the camera. The storefront is generic and unbranded; the only readable text is a small glowing sign reading 'OPEN 24H'. Documentary photography, muted colours, faint film grain.

02

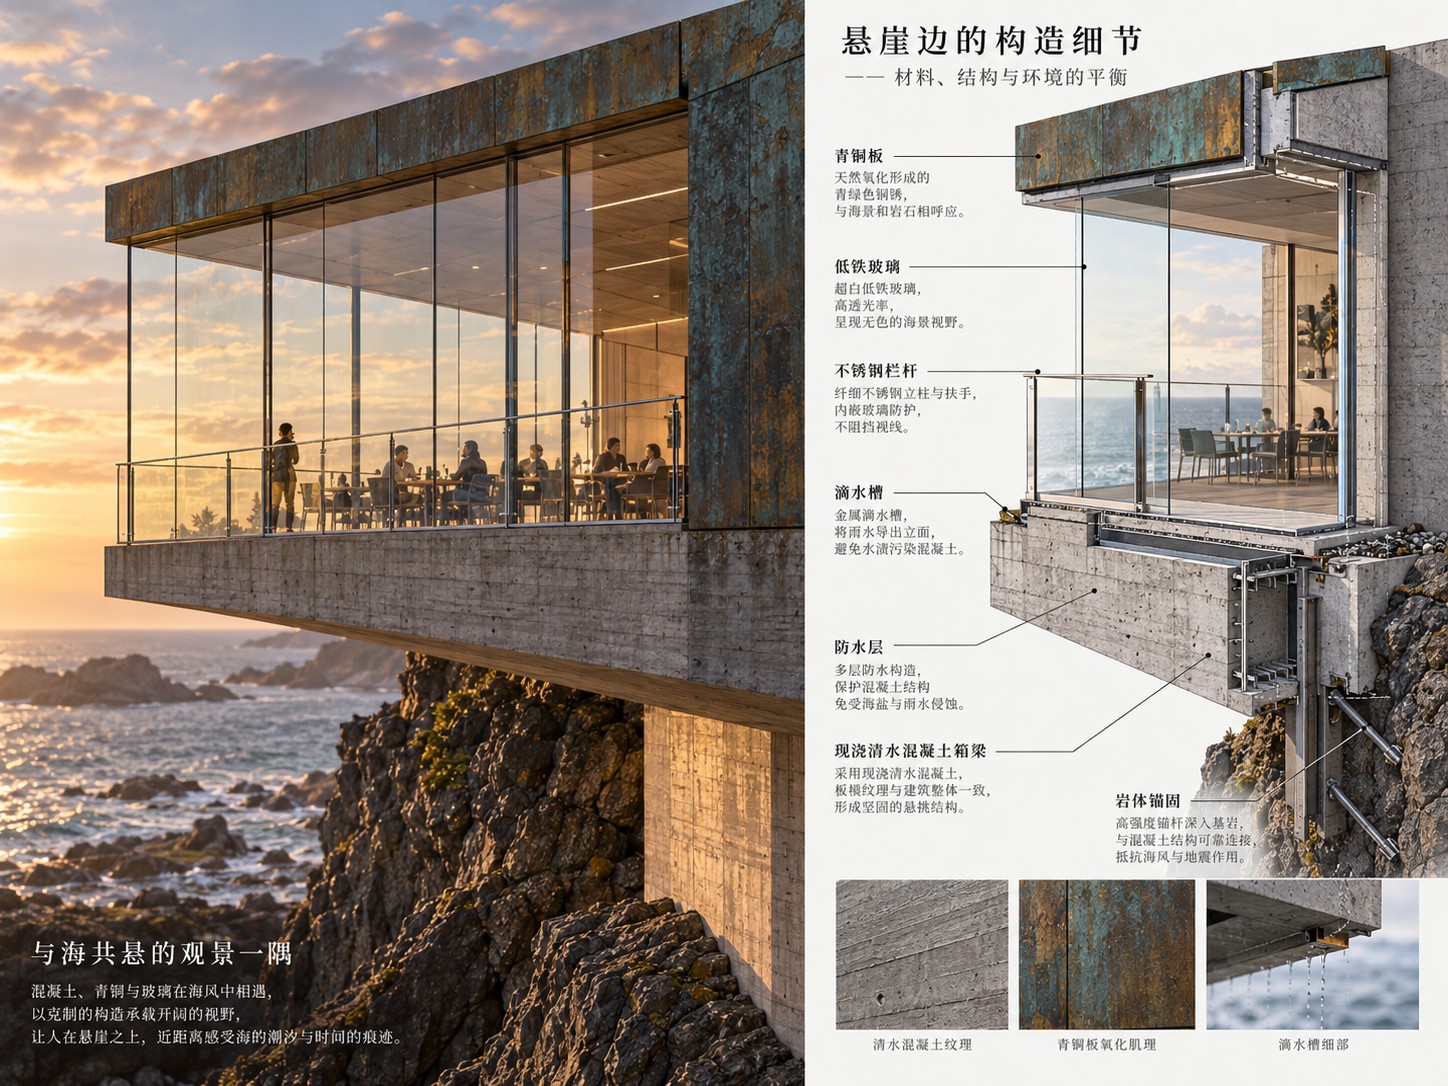
Ein Foto und seine Konstruktionszeichnung nebeneinander

Links ein verglastes Restaurant, das über das Meer auskragt, rechts sein Schnittdetail mit sieben chinesischen Beschriftungen von der patinierten Bronzeverkleidung bis zu den Felsankern. Jedes Zeichen in den Anmerkungen bleibt lesbar, und die Zeichnung passt Teil für Teil zum Foto.

Ein Foto und seine Konstruktionszeichnung nebeneinander: A two-part editorial spread on one 4:3 canvas. Left half: a photorealistic architectural photograph at golden hour of a small glass-walled restaurant cantilevered from a dark basalt cliff over the sea, the box clad in green-patinated bronze panels and carried on a raw board-marked concrete beam, floor to ceiling low-iron glazing with a thin stainless steel guardrail, diners at tables inside lit by the low sun, waves breaking on the rocks below, soft clouds. Right half on warm off-white paper: an annotated construction detail of the same cantilever drawn as a clean cut-away render with hairline leader lines, titled '悬崖边的构造细节' with the subtitle '材料、结构与环境的平衡', and seven callouts in Chinese reading '青铜板', '低铁玻璃', '不锈钢栏杆', '滴水槽', '防水层', '现浇清水混凝土箱梁', '岩体锚固', each with two or three short lines of explanation in small grey type; along the bottom three small material swatches captioned '清水混凝土纹理', '青铜板氧化肌理', '滴水槽细部'. Bottom left of the photograph a white caption block reading '与海共悬的观景一隅' with three short lines of copy beneath. Editorial typography, generous margins, every character rendered clearly, no other text.
Prompt

A two-part editorial spread on one 4:3 canvas. Left half: a photorealistic architectural photograph at golden hour of a small glass-walled restaurant cantilevered from a dark basalt cliff over the sea, the box clad in green-patinated bronze panels and carried on a raw board-marked concrete beam, floor to ceiling low-iron glazing with a thin stainless steel guardrail, diners at tables inside lit by the low sun, waves breaking on the rocks below, soft clouds. Right half on warm off-white paper: an annotated construction detail of the same cantilever drawn as a clean cut-away render with hairline leader lines, titled '悬崖边的构造细节' with the subtitle '材料、结构与环境的平衡', and seven callouts in Chinese reading '青铜板', '低铁玻璃', '不锈钢栏杆', '滴水槽', '防水层', '现浇清水混凝土箱梁', '岩体锚固', each with two or three short lines of explanation in small grey type; along the bottom three small material swatches captioned '清水混凝土纹理', '青铜板氧化肌理', '滴水槽细部'. Bottom left of the photograph a white caption block reading '与海共悬的观景一隅' with three short lines of copy beneath. Editorial typography, generous margins, every character rendered clearly, no other text.

03

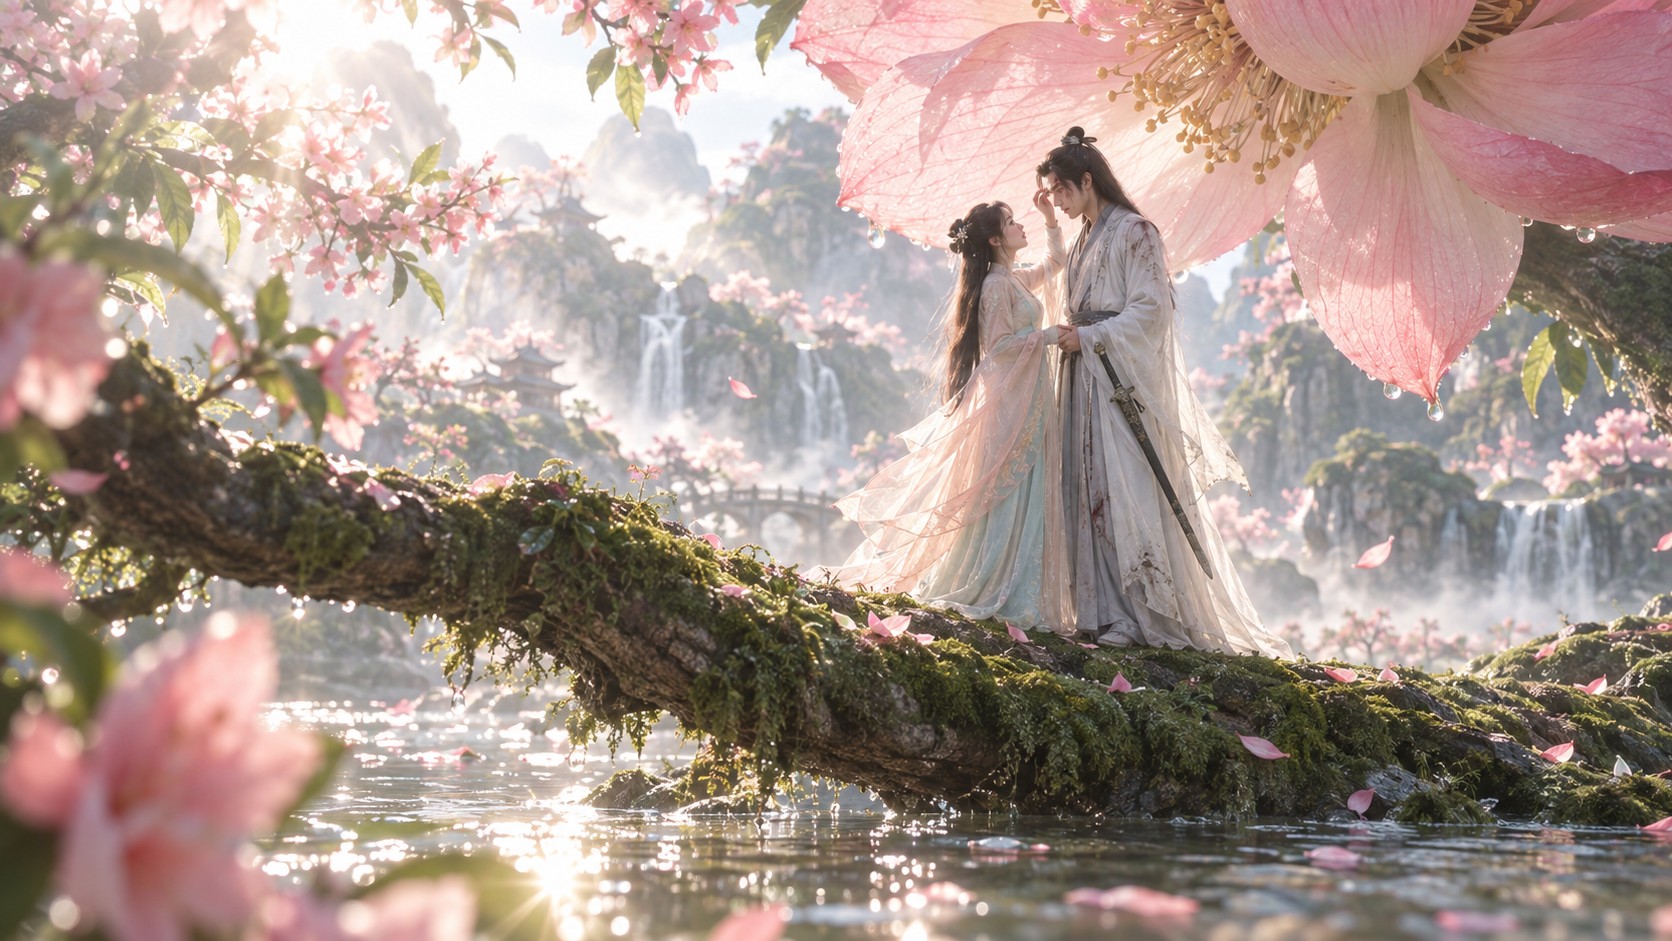
Eine Blüte so groß wie ein Segel

Zwei Figuren in Hanfu auf einem bemoosten Stamm über einem Fluss, unter einem durchscheinenden rosa Blütenblatt mit Tau am Rand, dahinter Karstgipfel und Wasserfälle im Dunst. Gegenlicht, Nebel und nasses Moos lesen sich als ein Licht, und die Stofffalten sind dort scharf, wo der Fokus liegt.

Eine Blüte so groß wie ein Segel: Cinematic wide shot in a Chinese xianxia fantasy world, photoreal CG. A young woman in flowing pale pink and mint layered hanfu with long black hair and a jade hairpin stands on a moss-covered fallen tree trunk that bridges a shallow river, gently touching the cheek of a young swordsman in white and grey robes with a sword at his hip; both in profile, close together. Above them a giant translucent pink blossom leans over the trunk, its petals the size of sails with dewdrops on the edges and golden stamens. Behind them misty karst peaks with waterfalls, a stone arch bridge and distant pavilion roofs, peach trees in full bloom, petals drifting down onto the water. Backlit morning sun, volumetric haze, soft lens bloom, sparkle and ripples on the water in the foreground, shallow depth of field on the blossoms nearest the camera. Ethereal and romantic, with detailed fabric and wet moss textures.
Prompt

Cinematic wide shot in a Chinese xianxia fantasy world, photoreal CG. A young woman in flowing pale pink and mint layered hanfu with long black hair and a jade hairpin stands on a moss-covered fallen tree trunk that bridges a shallow river, gently touching the cheek of a young swordsman in white and grey robes with a sword at his hip; both in profile, close together. Above them a giant translucent pink blossom leans over the trunk, its petals the size of sails with dewdrops on the edges and golden stamens. Behind them misty karst peaks with waterfalls, a stone arch bridge and distant pavilion roofs, peach trees in full bloom, petals drifting down onto the water. Backlit morning sun, volumetric haze, soft lens bloom, sparkle and ripples on the water in the foreground, shallow depth of field on the blossoms nearest the camera. Ethereal and romantic, with detailed fabric and wet moss textures.

04

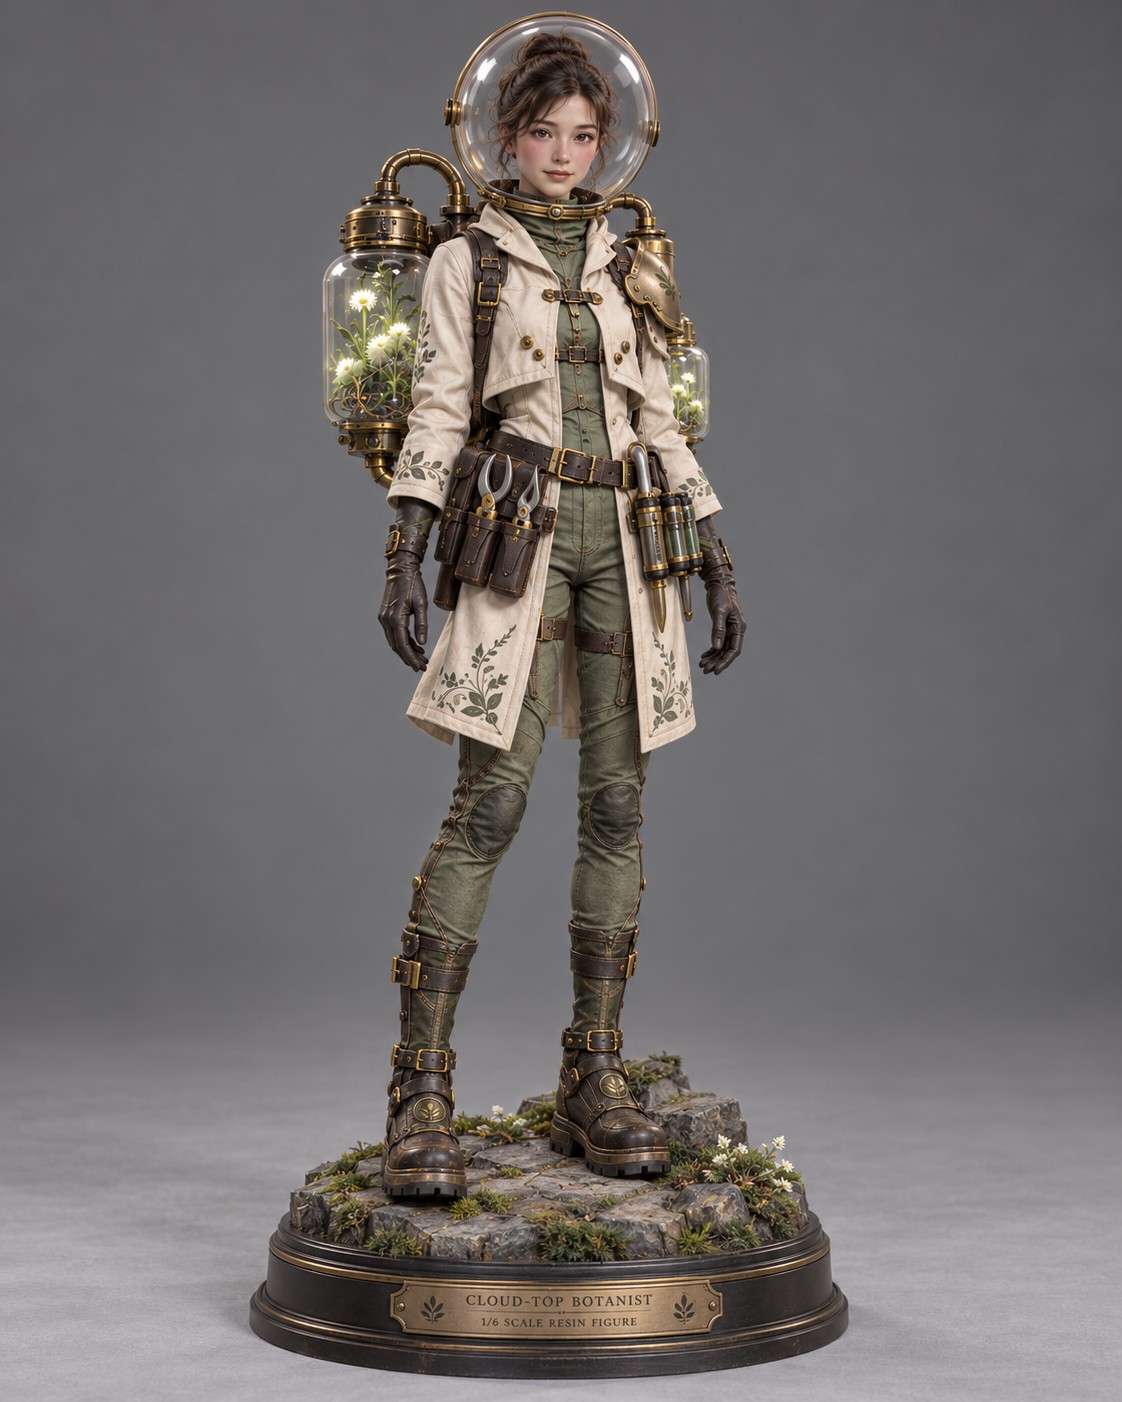
Eine Sammelfigur zum Anfassen

Eine Botanikerfigur im Maßstab 1:6 auf ihrem Sockel, Glashelm, Terrarientanks aus Messing und bestickter Canvasmantel, fotografiert wie ein Produktbild. Glas, Messing, Leder und Stoff behalten jeweils ihre eigene Oberfläche, und das Schild trägt vollständig „CLOUD-TOP BOTANIST“.

Eine Sammelfigur zum Anfassen: Studio product photograph of a 1/6 scale resin collectible figure: a young woman botanist explorer standing on a rocky mossy base with tiny white wildflowers, wearing a glass dome helmet with brass fittings, a cream canvas coat with green leaf embroidery over an olive utility suit, a leather tool belt holding pruning shears and glass vials, dark leather gloves and tall buckled boots. On her back two brass and glass terrarium canisters with glowing white daisies inside. The figure stands on a round black plinth with a brass plaque reading 'CLOUD-TOP BOTANIST' and a smaller line '1/6 SCALE RESIN FIGURE'. Plain grey seamless backdrop, soft even studio light with a gentle shadow under the base, sharp focus from helmet to boots, visible material finishes: matte fabric, polished brass, clear glass, worn leather. Vertical 3:4 framing.
Prompt

Studio product photograph of a 1/6 scale resin collectible figure: a young woman botanist explorer standing on a rocky mossy base with tiny white wildflowers, wearing a glass dome helmet with brass fittings, a cream canvas coat with green leaf embroidery over an olive utility suit, a leather tool belt holding pruning shears and glass vials, dark leather gloves and tall buckled boots. On her back two brass and glass terrarium canisters with glowing white daisies inside. The figure stands on a round black plinth with a brass plaque reading 'CLOUD-TOP BOTANIST' and a smaller line '1/6 SCALE RESIN FIGURE'. Plain grey seamless backdrop, soft even studio light with a gentle shadow under the base, sharp focus from helmet to boots, visible material finishes: matte fabric, polished brass, clear glass, worn leather. Vertical 3:4 framing.

Was du mit GPT Image 2.5 machst

Gruppenbilder, in denen jedes Gesicht eine Person ist

Kampagnenmotive, Teamseiten und Social-Posts mit fünf oder sechs Leuten im Bild, jede und jeder mit eigenen Zügen und eigenem Ausdruck, beleuchtet nur von dem Licht, das die Szene wirklich hat.

Beschriftete Layouts in mehr als einer Sprache

Produktblätter, Konstruktionsdetails und Erklärgrafiken, die ein fotorealistisches Bild mit beschrifteten Hinweisen kombinieren, wobei chinesische wie englische Kleinschrift lesbar bleibt.

Szenen und Produkte, die fertig wirken

Filmische Standbilder für einen Pitch oder Sammelfiguren und Verpackungen, fotografiert wie ein Produktbild, bei denen Glas, Metall, Stoff und Haut jeweils ihre eigene Oberfläche behalten.

Wer zu GPT Image 2.5 greift

GPT Image 2.5 ist das Bildmodell von OpenAI aus dem September 2026, und Vidney stellt beide Varianten auf eine Seite: Flare, die schnellere und für die meiste Arbeit auch OpenAIs eigene Voreinstellung, und Sunburst, die langsamere für präzise Korrekturen. Beide laufen von Text zu Bild und von Bild zu Bild, nehmen bis zu vier Referenzbilder und decken 1:1, 4:3, 3:4, 16:9 und 9:16 in 1K, 2K oder 4K ab, wobei 4K rund 8,3 Millionen Pixel ergibt. Die Qualität steht fest auf der mittleren Stufe, transparente Hintergründe, maskiertes Bearbeiten und die höheren Qualitätsstufen bleiben vorerst zu. Nimm es, wenn die Wörter im Bild schon beim ersten Versuch stimmen müssen.

So erstellst du Bild-Inhalte mit GPT Image 2.5

Erstelle KI-Bild-Inhalte mit GPT Image 2.5 auf Vidney in drei Schritten.

Glowing panels with one model selected from severalStreams of light forming into an emerging imageA finished image materializing from a vortex of glowing light

GPT Image 2.5 vs Muse Image vs Midjourney V8.1 vs Grok Imagine Image 2.0

Spezifikationen neben ähnlichen Modellen, alle auf Vidney nutzbar.

GPT Image 2.5Muse ImageMidjourney V8.1Grok Imagine Image 2.0
AufgabenmodiText zu Bild · Bild zu BildText zu Bild · Bild zu BildText zu Bild · Bild zu BildText zu Bild · Bild zu Bild
Auflösung1K · 2K · 4K1K · 2K
Kosten3–5 Credits pro Generierung3 Credits pro Generierung18 Credits pro Generierung9–15 Credits pro Generierung

Verwandte Modelle

Weitere KI-Bild-Modelle, die du auf Vidney nutzen kannst.

Live

Erstelle KI-Bild-Inhalte mit GPT Image 2.0: Text zu Bild und Bild zu Bild, alles aus einem Vidney Workspace.

3 Credits pro Generierung
Live

Erstelle KI-Bild-Inhalte mit GPT Image 1.5: Text zu Bild und Bild zu Bild, alles aus einem Vidney Workspace.

3 Credits pro Generierung
Live

Metas Bildmodell prüft den eigenen Entwurf, bevor das Bild zurückkommt.

3 Credits pro Generierung
Live

Erstelle KI-Bild-Inhalte mit Nano Banana 2: Text zu Bild und Bild zu Bild, alles aus einem Vidney Workspace.

3 Credits pro Generierung
MidjourneyMidjourney V7
Live

Erstelle KI-Bild-Inhalte mit Midjourney V7: Text zu Bild und Bild zu Bild, alles aus einem Vidney Workspace.

6 Credits pro Generierung
Live

Erstelle KI-Bild-Inhalte mit Nano Banana: Text zu Bild und Bild zu Bild, alles aus einem Vidney Workspace.

6 Credits pro Generierung

Häufige Fragen

Was ist GPT Image 2.5?

GPT Image 2.5 ist ein KI-Bild-Modell, das du auf Vidney nutzen kannst. Es unterstützt Text zu Bild und Bild zu Bild aus einem einzigen Workspace.

Wie viel kostet GPT Image 2.5 pro Generierung?

GPT Image 2.5 kostet 3–5 Credits pro Generierung. Die genauen Credit-Kosten stehen vor dem Lauf auf dem Generieren-Button.

Welche Seitenverhältnisse unterstützt GPT Image 2.5?

GPT Image 2.5 unterstützt folgende Seitenverhältnisse: 1:1, 4:3, 3:4, 16:9, 9:16.

Ist GPT Image 2.5 kostenlos nutzbar?

Du kannst GPT Image 2.5 auf Vidney mit deinen Start-Credits kostenlos ausprobieren, ohne Kreditkarte zum Testen. Danach kostet jeder Lauf 3–5 Credits pro Generierung, und der genaue Preis steht immer vor dem Klick auf dem Generieren-Button. Abgerechnet wird transparent in Credits, ohne Abo-Zwang und ohne versteckte Gebühren.

Darf ich mit GPT Image 2.5 erstellte Bild-Inhalte kommerziell nutzen?

Ja. Bild-Inhalte, die du mit GPT Image 2.5 auf Vidney erstellst, kannst du kommerziell verwenden: für Werbung, Social-Media-Posts, Kundenprojekte und Produktinhalte. Die Rechte am Ergebnis bleiben bei dir; Vidney übernimmt nur Generierung und Speicherung, sodass auch B2B-Teams die Ausgaben einsetzen können.

Fügt GPT Image 2.5 ein Wasserzeichen hinzu?

Nein. Bild-Inhalte, die mit GPT Image 2.5 auf Vidney entstehen, werden sauber und ohne Vidney-Wasserzeichen ausgeliefert: direkt veröffentlichungsfertig oder ohne Nachbearbeitung an Kunden übergebbar.

Was sind die besten Alternativen zu GPT Image 2.5?

Die ähnlichsten Alternativen zu GPT Image 2.5 auf Vidney sind Muse Image, Midjourney V8.1 und Grok Imagine Image 2.0. Alle laufen im selben Workspace über ein gemeinsames Credit-Guthaben. So kannst du denselben Prompt mit jedem Modell ausprobieren und die Ergebnisse direkt nebeneinander vergleichen.

Brauche ich einen API-Schlüssel oder ein Anbieter-Konto, um GPT Image 2.5 zu nutzen?

Nein. Vidney führt GPT Image 2.5 für dich aus, ohne API-Schlüssel zu verwalten und ohne separates Anbieter-Konto einzurichten.

Jetzt mit GPT Image 2.5 erstellen