Vidney

Generador de Imágenes IA

Muse Image

El modelo de imagen de Meta revisa su propio borrador antes de devolverte la imagen.

Espacio de trabajo Vidney

21 modelos
0/2000
Necesarios: 3 créditos

Resultado

Muestra

Lo que Muse Image hace bien

01

Un fotograma de película de animación

Un tren de montaña cruza un viaducto al anochecer, trazado con línea limpia sobre un valle pintado a la acuarela. Parece un fotograma sacado de un largometraje, hasta el brillo en las ventanillas de los vagones.
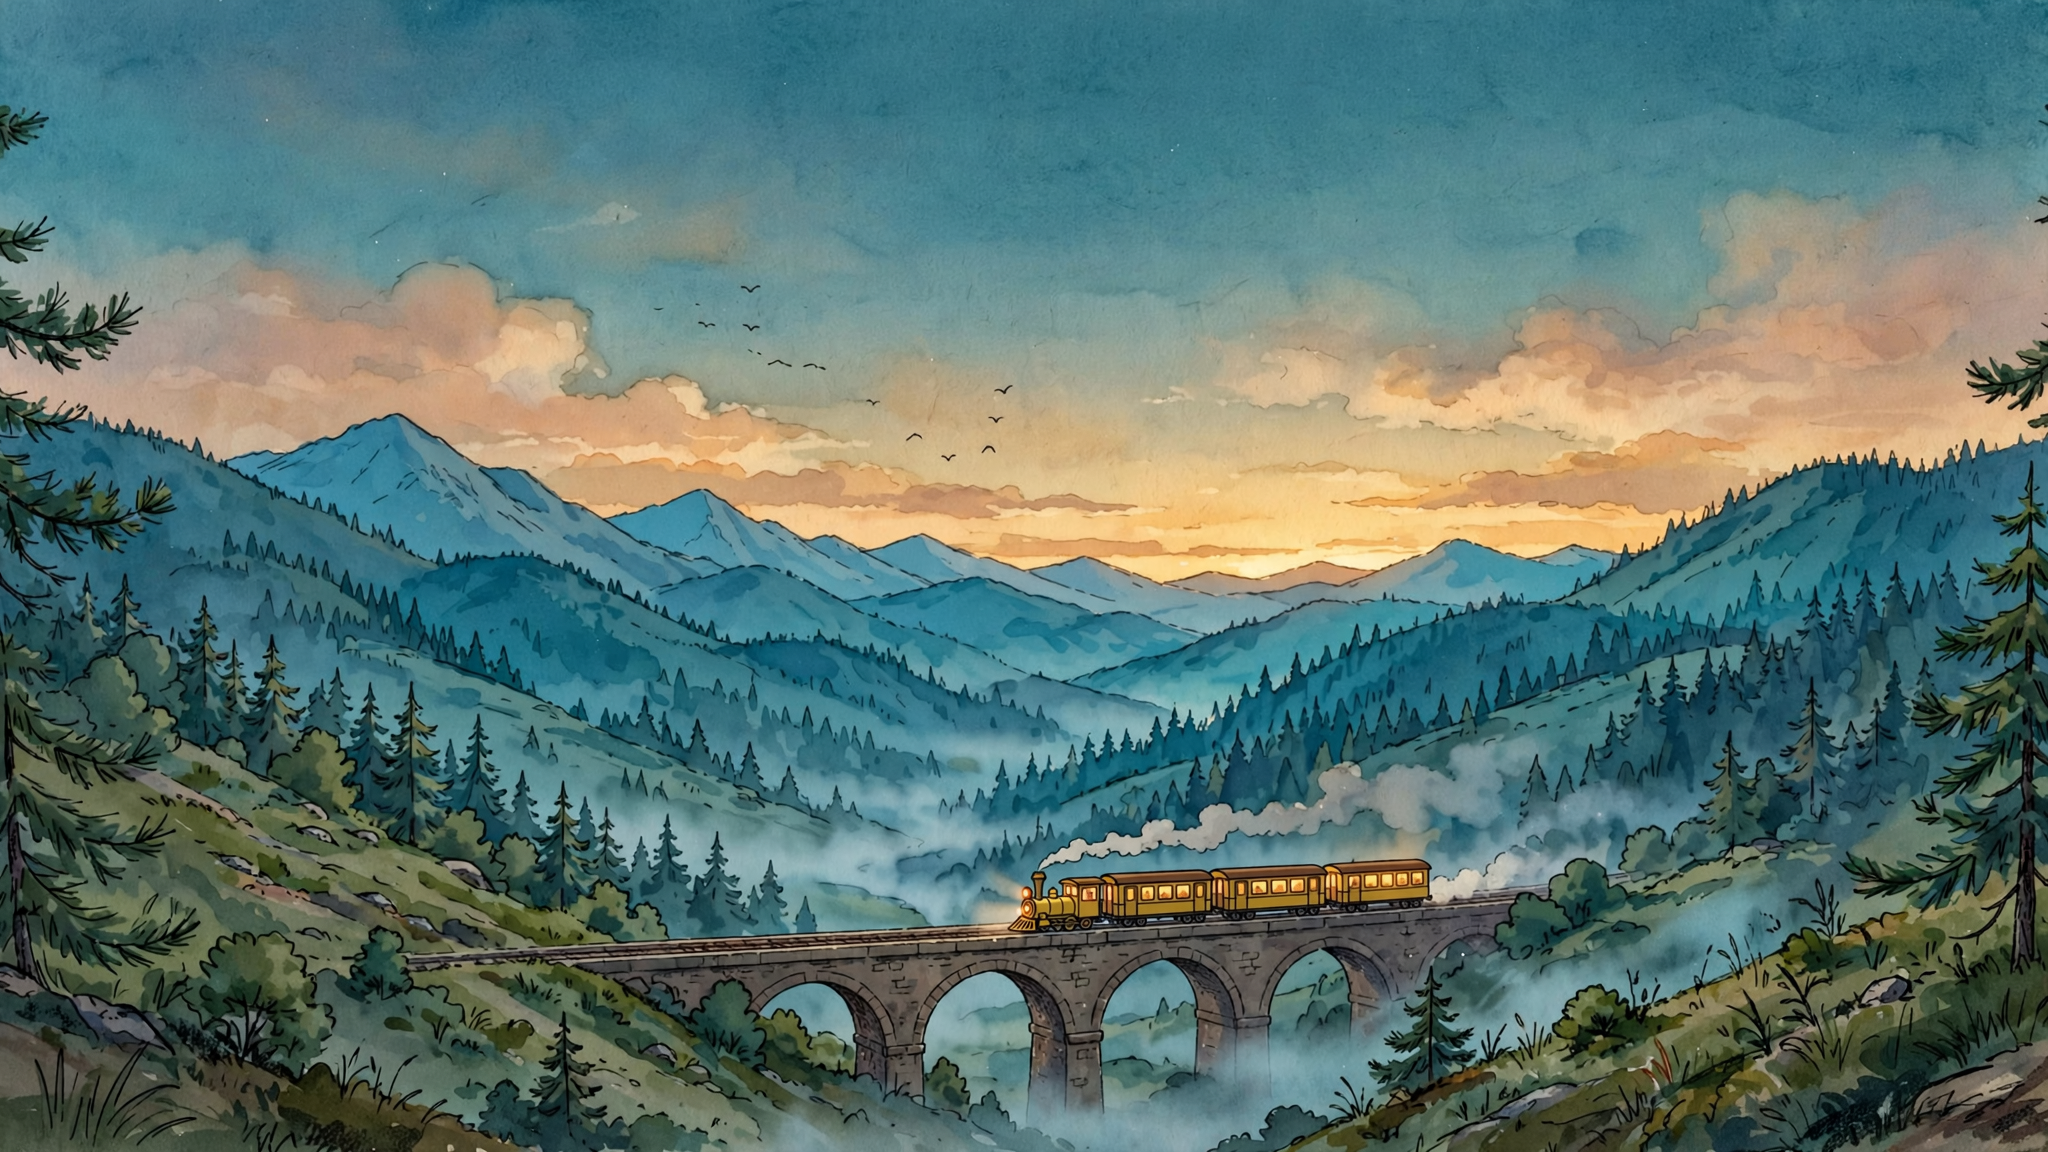
Un fotograma de película de animación: A single frame from a hand drawn 2D animated feature: a small yellow mountain train crosses a stone viaduct at dusk, seen from a hillside across the valley. Cel shaded train with clean confident linework and flat warm colours, lit carriage windows glowing amber, a thin trail of steam behind it. Painted watercolour background of pine forest, layered blue ridges and a deep teal sky with the last warm light on the horizon, soft mist gathering in the valley floor. Wide composition with the viaduct running across the lower third, generous sky above, a few birds as small dark marks. Quiet, warm, unhurried mood, the look of a studio feature still rather than a digital illustration, subtle film grain. No people, no text, no signature, no watermark.
Prompt

A single frame from a hand drawn 2D animated feature: a small yellow mountain train crosses a stone viaduct at dusk, seen from a hillside across the valley. Cel shaded train with clean confident linework and flat warm colours, lit carriage windows glowing amber, a thin trail of steam behind it. Painted watercolour background of pine forest, layered blue ridges and a deep teal sky with the last warm light on the horizon, soft mist gathering in the valley floor. Wide composition with the viaduct running across the lower third, generous sky above, a few birds as small dark marks. Quiet, warm, unhurried mood, the look of a studio feature still rather than a digital illustration, subtle film grain. No people, no text, no signature, no watermark.

02

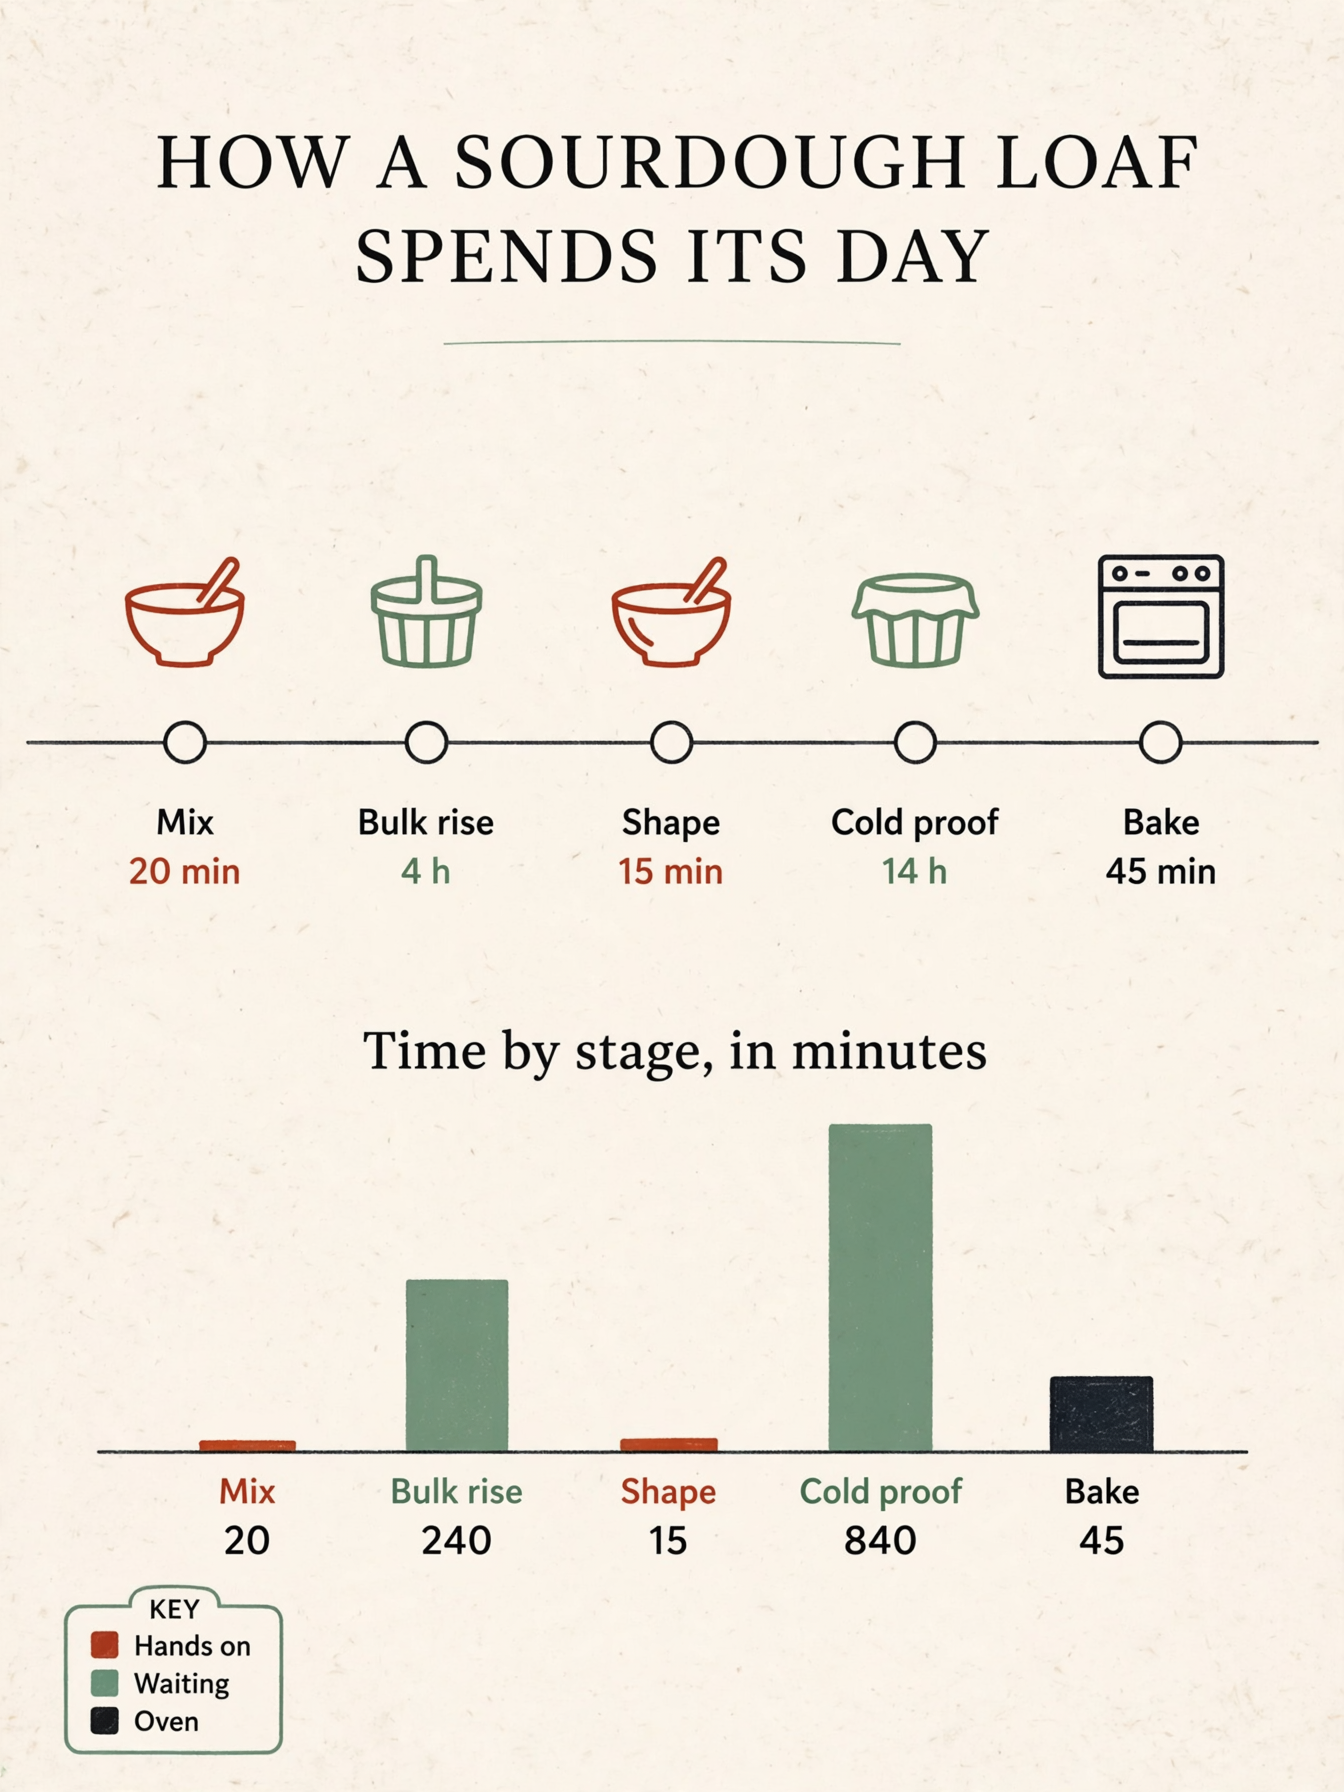
Un gráfico con cifras reales

Una cronología de horneado en una página, donde cada barra mide de verdad lo que dice la cifra impresa debajo. Las etiquetas y los números coinciden, así que la página entra en una presentación sin redibujarla.

Un gráfico con cifras reales: A single page printed infographic titled 'HOW A SOURDOUGH LOAF SPENDS ITS DAY', portrait layout on warm off-white paper. Across the middle runs a horizontal timeline with five labelled stages and their durations, in order 'Mix 20 min', 'Bulk rise 4 h', 'Shape 15 min', 'Cold proof 14 h', 'Bake 45 min'. Below it sits a simple bar chart titled 'Time by stage, in minutes' with five bars whose heights are strictly proportional to the values 20, 240, 15, 840 and 45, so the 840 bar is three and a half times as tall as the 240 bar and the 20 bar is barely visible, each bar labelled with its own number under it. A small key in the lower left carries three colour swatches labelled 'Hands on', 'Waiting', 'Oven'. Flat editorial design in ink black, warm clay red and sage green, thin rules, clear type hierarchy, plenty of whitespace, three simple line icons for a mixing bowl, a proofing basket and an oven. All labels short and legible, spelled exactly as written, every number matching its bar. No other text, no logos, no watermark.
Prompt

A single page printed infographic titled 'HOW A SOURDOUGH LOAF SPENDS ITS DAY', portrait layout on warm off-white paper. Across the middle runs a horizontal timeline with five labelled stages and their durations, in order 'Mix 20 min', 'Bulk rise 4 h', 'Shape 15 min', 'Cold proof 14 h', 'Bake 45 min'. Below it sits a simple bar chart titled 'Time by stage, in minutes' with five bars whose heights are strictly proportional to the values 20, 240, 15, 840 and 45, so the 840 bar is three and a half times as tall as the 240 bar and the 20 bar is barely visible, each bar labelled with its own number under it. A small key in the lower left carries three colour swatches labelled 'Hands on', 'Waiting', 'Oven'. Flat editorial design in ink black, warm clay red and sage green, thin rules, clear type hierarchy, plenty of whitespace, three simple line icons for a mixing bowl, a proofing basket and an oven. All labels short and legible, spelled exactly as written, every number matching its bar. No other text, no logos, no watermark.

03

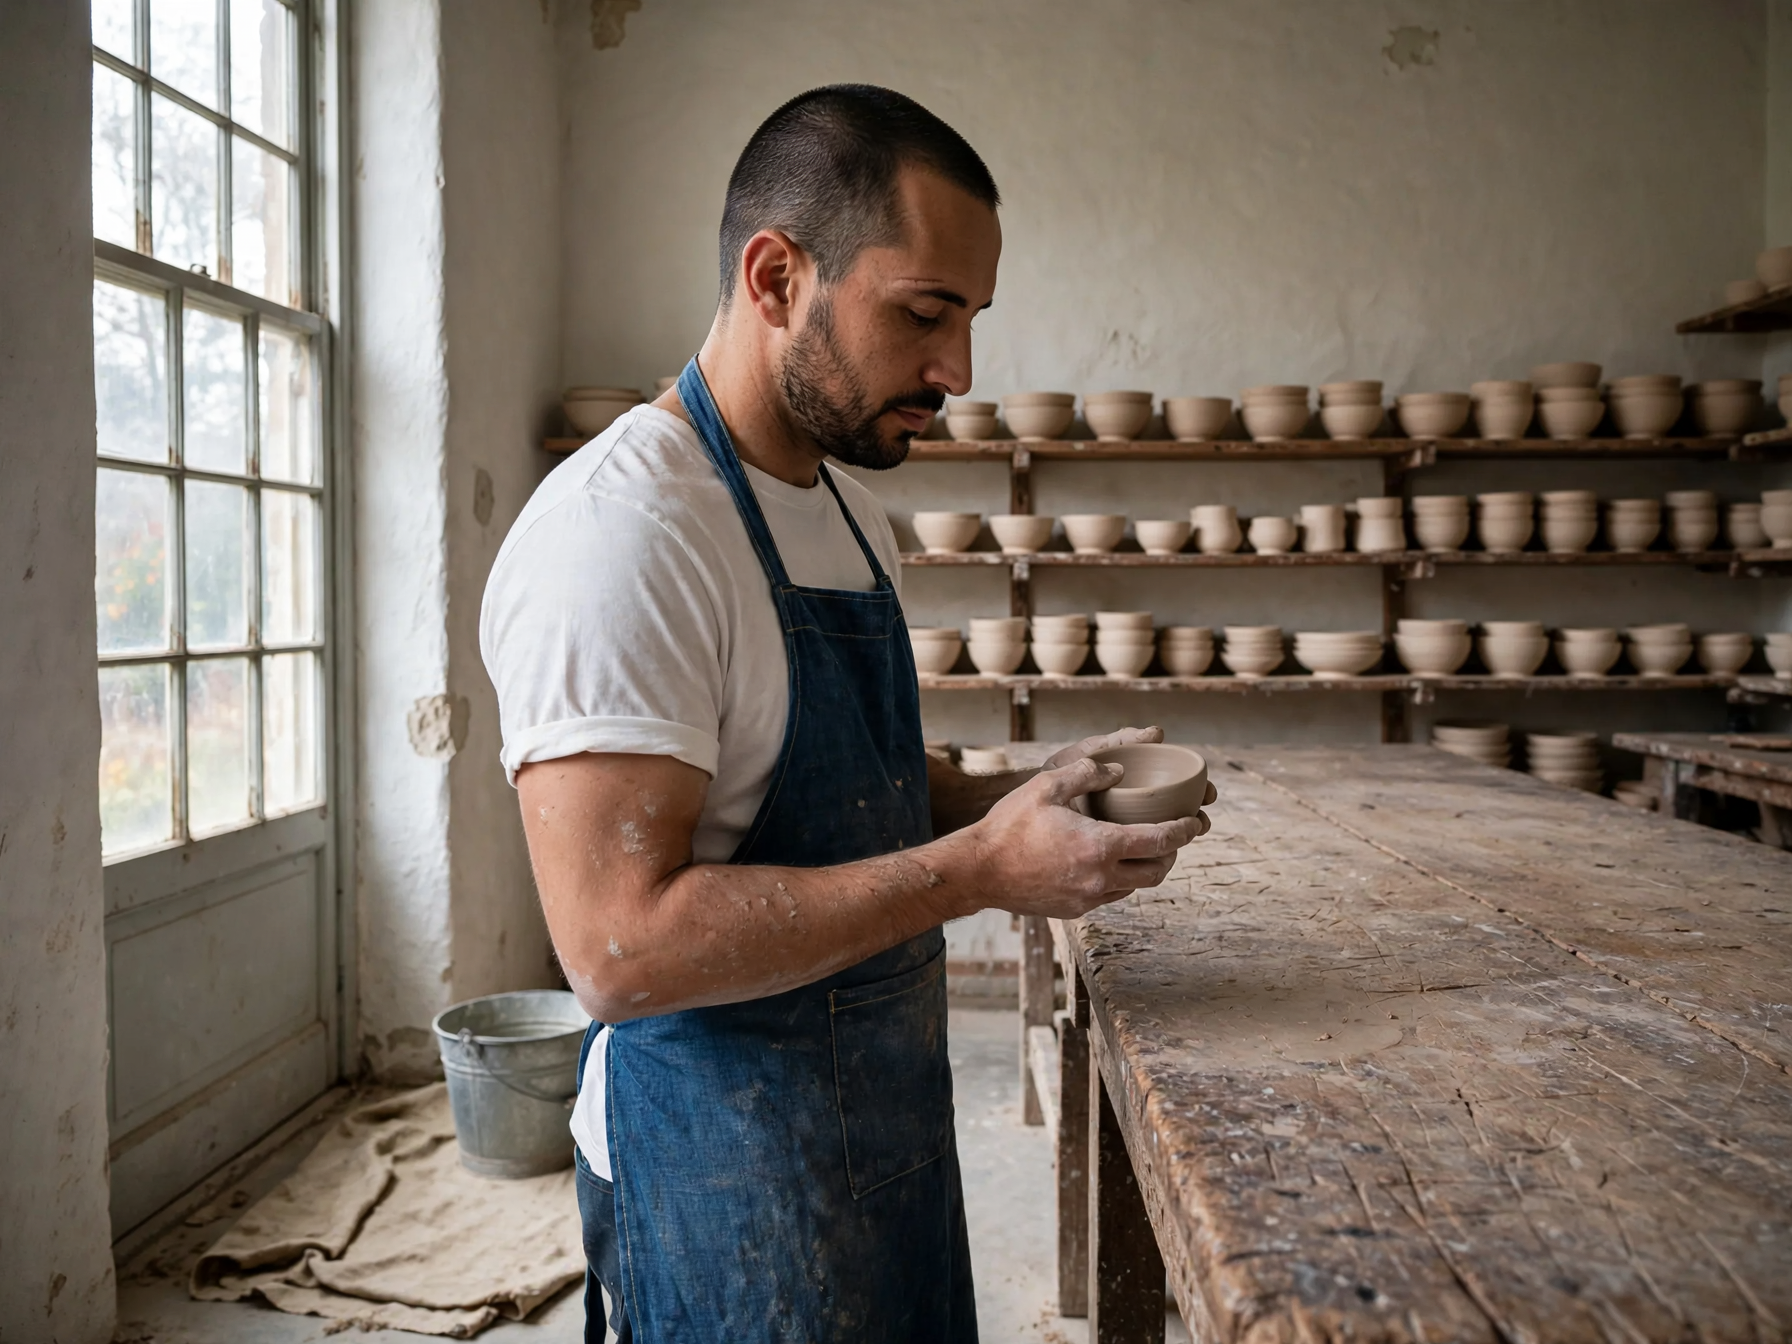
Tres referencias, una sola foto

La cara sale de una imagen, el delantal de una segunda y el taller de una tercera, y todo llega en una única toma. El delantal conserva sus costuras y su bolsillo, y la luz de la ventana cae sobre el hombre igual que cae sobre la sala.

Tres referencias, una sola foto: Use the first reference for the person, the second for the garment and the third for the setting. Keep the same man, his face, beard, haircut and build unchanged, and place him standing at the long workbench from the third reference, wearing the indigo cross back linen apron from the second reference over a plain white tee with the sleeves pushed to the elbow. Three quarter view from camera left, he is turning a small unglazed bowl in his hands and looking down at it. Match the light of the room: soft daylight from the tall window on the left, warm bounce off the plaster wall, a short shadow under the bench. The apron ties, topstitching and pocket shape stay exactly as in the reference, and the room keeps its own props and layout. Natural skin texture, fine linen weave, clay dust on the forearms, photoreal, 50mm lens, shallow depth of field. No extra people, no text, no logos, no watermark.
Prompt

Use the first reference for the person, the second for the garment and the third for the setting. Keep the same man, his face, beard, haircut and build unchanged, and place him standing at the long workbench from the third reference, wearing the indigo cross back linen apron from the second reference over a plain white tee with the sleeves pushed to the elbow. Three quarter view from camera left, he is turning a small unglazed bowl in his hands and looking down at it. Match the light of the room: soft daylight from the tall window on the left, warm bounce off the plaster wall, a short shadow under the bench. The apron ties, topstitching and pocket shape stay exactly as in the reference, and the room keeps its own props and layout. Natural skin texture, fine linen weave, clay dust on the forearms, photoreal, 50mm lens, shallow depth of field. No extra people, no text, no logos, no watermark.

Qué puedes crear con Muse Image

Fotogramas de una película que nadie rodó

Pide un momento concreto de un largometraje de animación y recibes ese fotograma, línea limpia sobre fondos pintados, con el tono ya puesto antes de que exista un storyboard.

Una página explicativa que aguanta

Cronologías, barras y leyendas donde las etiquetas y las cifras coinciden, para que la página vaya a una presentación o a un dosier sin que un diseñador la rehaga.

Una persona, ropa y sala prestadas

Combina una cara, una prenda y un lugar de fotos distintas en una sola imagen, útil para retratos de equipo, lookbooks y personajes recurrentes.

Para quién es Muse Image

Muse Image es el modelo de imagen de Meta Superintelligence Labs, presentado en julio de 2026 junto a Meta AI y segundo esa misma semana en las tablas de Arena tanto en texto a imagen como en edición de una imagen y de varias. Es un modelo que usa herramientas: aprendió a escribir código para que un gráfico o un código QR salgan exactos, a consultar un dato antes de dibujarlo y a criticar y rehacer su primer intento antes de entregar nada. En Vidney funciona de texto a imagen y de imagen a imagen con hasta diez imágenes de referencia, en 1:1, 4:3, 3:4, 16:9 y 9:16, con un único tamaño de salida y sin selector de resolución, por 3 créditos cada generación. Elígelo cuando la imagen tenga que coincidir con los datos que lleva dentro.

Cómo generar imagen con Muse Image

Crea imagen con IA usando Muse Image en Vidney en tres pasos.

Glowing panels with one model selected from severalStreams of light forming into an emerging imageA finished image materializing from a vortex of glowing light

Muse Image vs GPT Image 2.5 vs Midjourney V8.1 vs Grok Imagine Image 2.0

Especificaciones frente a modelos similares, todos disponibles en Vidney.

Muse ImageGPT Image 2.5Midjourney V8.1Grok Imagine Image 2.0
Modos de tareaTexto a imagen · Imagen a imagenTexto a imagen · Imagen a imagenTexto a imagen · Imagen a imagenTexto a imagen · Imagen a imagen
Resolución1K · 2K · 4K1K · 2K
Costo3 créditos por generación3–5 créditos por generación18 créditos por generación9–15 créditos por generación

Modelos relacionados

Más modelos de IA para generar imagen que puedes usar en Vidney.

Disponible

Dos velocidades en una misma página, y las palabras que escribes vuelven bien escritas.

3–5 créditos por generación
Disponible

Genera imagen con IA usando Nano Banana 2: texto a imagen e imagen a imagen, todo desde un solo espacio de trabajo de Vidney.

3 créditos por generación
Disponible

Genera imagen con IA usando GPT Image 2.0: texto a imagen e imagen a imagen, todo desde un solo espacio de trabajo de Vidney.

3 créditos por generación
Disponible

Genera imagen con IA usando GPT Image 1.5: texto a imagen e imagen a imagen, todo desde un solo espacio de trabajo de Vidney.

3 créditos por generación
MidjourneyMidjourney V7
Disponible

Genera imagen con IA usando Midjourney V7: texto a imagen e imagen a imagen, todo desde un solo espacio de trabajo de Vidney.

6 créditos por generación
Disponible

Genera imagen con IA usando Nano Banana: texto a imagen e imagen a imagen, todo desde un solo espacio de trabajo de Vidney.

6 créditos por generación

Preguntas frecuentes

¿Qué es Muse Image?

Muse Image es un modelo de IA para generar imagen que puedes usar en Vidney. Admite texto a imagen e imagen a imagen desde un solo espacio de trabajo.

¿Cuánto cuesta cada generación con Muse Image?

Muse Image cuesta 3 créditos por generación. El costo exacto en créditos aparece en el botón de generar antes de ejecutarlo.

¿Qué relaciones de aspecto admite Muse Image?

Muse Image admite las siguientes relaciones de aspecto: 1:1, 4:3, 3:4, 16:9, 9:16.

¿Es gratis usar Muse Image?

Sí, puedes empezar a usar Muse Image gratis en Vidney: al registrarte recibes créditos de bienvenida, sin tarjeta y sin compromiso, para probarlo de verdad. Después, cada generación cuesta 3 créditos por generación, y el costo exacto siempre aparece en el botón de generar antes de gastar un solo crédito.

¿Puedo usar lo que genero con Muse Image con fines comerciales?

Sí. Lo que generas con Muse Image en Vidney es tuyo para usarlo en proyectos comerciales: anuncios de producto, contenido para TikTok Shop, publicaciones en redes y trabajos para clientes. Tú conservas el resultado; Vidney solo se encarga de la generación y el almacenamiento.

¿Muse Image agrega marca de agua?

No. Lo que generas con Muse Image en Vidney se entrega limpio, sin marca de agua de Vidney, listo para publicar o entregar a un cliente tal cual, sin pasos extra de edición.

¿Cuáles son las mejores alternativas a Muse Image?

Las alternativas a Muse Image más cercanas en Vidney son GPT Image 2.5, Midjourney V8.1 y Grok Imagine Image 2.0. Todas funcionan en el mismo espacio de trabajo con un solo saldo de créditos, así que puedes correr el mismo prompt en cada una y comparar los resultados lado a lado.

¿Necesito una clave API o una cuenta de proveedor para usar Muse Image?

No. Vidney ejecuta Muse Image por ti: no hay claves API que gestionar ni cuentas de proveedor que configurar.

Crea con Muse Image ahora